PocketPal AI: running GGUF models on your phone, no account required
An app that brings language models directly to your phone.
At a glance
- What is it?
- PocketPal AI is a React Native app that runs quantized GGUF language models and ONNX voice models on iOS and Android. It is free, MIT-licensed, and built for people who want chat that works offline.
- Who is it for?
- Adopt PocketPal AI if you want an offline chat client on a phone you already own, or if you are a React Native developer who wants a working llama.rn integration to read. Do not adopt it as a server-side inference platform; the architecture is explicitly on-device, and the hardware table lists only CPU, Metal/OpenCL GPU, and Qualcomm Hexagon NPU paths, plus the Apple Neural Engine for Phonon on iOS.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
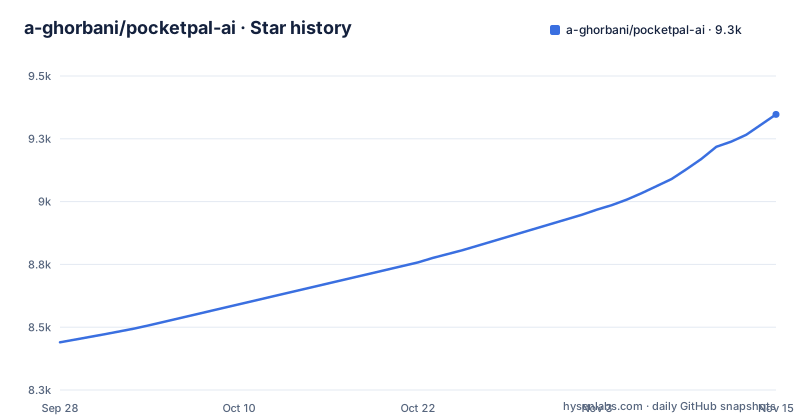
- a-ghorbani/pocketpal-ai9,347 ★ · +907
| Repository | 2026-09-28 | 2026-11-15 |
|---|---|---|
| a-ghorbani/pocketpal-ai | 8.4k | 9.3k |
907 Stars in the last 48 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem PocketPal AI actually solves
Most mobile AI apps are clients for someone else's server. The README states the project's position plainly: "Most AI apps are a thin window onto someone else's server." PocketPal inverts that. The model file lives on the device, inference runs on the device, and the README says prompts, responses, and documents stay there unless you turn on an online feature. It says chats and documents leave the phone only through features the user turns on: web search and page reading, a remote server, or a system voice the phone runs online.
The audience follows from that. It is for people who want a chat interface without creating an account, and for people who are offline often enough that a cloud round trip is not an option. It is also for React Native developers, because the repository is a working example of wiring llama.cpp into a mobile app through JSI. It is not for anyone who needs a large model. A phone is a phone, and the README's own guidance is to pick a model that fits your phone, which is a polite way of saying the ceiling is low.
The four-layer stack and where the tokens go
The README describes PocketPal as four layers with a strictly top-down dependency direction. At the top sits the React Native app: React Native Paper for UI, MobX for state, WatermelonDB for chat history. The AgentRunner drives each conversational turn, streams tokens, and dispatches Talents when the model calls a tool, then feeds the tool result back for a follow-up pass. Pals are the configurable personas layered on top, and PalsHub is the in-app marketplace where those personas are shared or sold.
Below that is the bridging layer. llama.rn connects JavaScript to LLM inference over JSI, while react-native-speech and onnxruntime-react-native connect to text-to-speech. The engines include llama.cpp for GGUF language models, whisper.cpp for speech recognition, and ONNX Runtime for the Kokoro, Kitten and Supertonic voice models. The bottom layer is hardware: CPU as the universal fallback, GPU through Metal on iOS and OpenCL on Qualcomm Adreno for Android, and NPU through Qualcomm Hexagon. The README notes that partial layer offloading happens when a full backend is unavailable.
That last detail is the most consequential part of the architecture. Offloading some layers to a GPU and leaving the rest on the CPU means performance is a function of the specific phone, not of the app version. Two users on the same release can have very different tokens-per-second numbers, and the app's own benchmarking feature exists partly because that variation is real.
Installing PocketPal AI and loading a first model
There is no build step for ordinary users. The README points to the App Store and Google Play, and the package identifier on the Play listing is com.pocketpalai. The three steps the README gives are: install the app, download a model from the Models screen, then load it and chat.
The only command shown here is for developers building from source. The repository is a React Native project with a yarn.lock and a postinstall script, and package.json exposes platform run scripts.
yarn install
yarn android
The android script maps to react-native run-android --mode=prodDebug, and there is a matching yarn ios that targets an iPhone 16 Pro simulator. The postinstall hook runs ./scripts/postinstall.sh.
For a first real use, follow the README's in-app path rather than the source build. Open the app, tap the menu, go to Models, and download a model that fits your phone. The README also describes adding a model from Hugging Face, and notes that gated Hugging Face models require your access token. After the download finishes, load the model and start a chat.
Where PocketPal AI breaks down
The clearest limitation is memory. A quantized model plus its KV cache has to fit in the phone's RAM alongside the app itself, and the README's quick start says only to pick a model that fits your phone.
Hardware acceleration is the second constraint, and it is narrower than the feature list suggests. The README names Metal on iOS, OpenCL on Qualcomm Adreno for Android, and Qualcomm Hexagon for NPU. That means the NPU path is Qualcomm Hexagon, apart from the Apple Neural Engine used for Phonon on iOS, and Android devices on other chipsets fall back to CPU or partial offload. The phrase "graceful fallback" in the README is accurate but it describes a performance cliff, not a feature that disappears.
Third, the app is not a document assistant in the RAG sense. The README mentions that documents stay on the device, but the feature list does not describe an embedding pipeline, a vector store, or file ingestion beyond model files. Anyone expecting to point it at a PDF corpus should check the current release notes first. Finally, PalsHub involves Supabase configuration and optional authentication, so the marketplace path is not the offline path; the .env.example separates ENABLE_PALSHUB_INTEGRATION, ENABLE_AUTHENTICATION, and ENABLE_OFFLINE_MODE as independent flags, which tells you the maintainers treat them as separable concerns.
PocketPal AI versus Private LLM and other on-device clients
The obvious comparison is with Apple-only on-device chat apps. The difference is in scope and platform coverage. PocketPal AI ships on both iOS and Android, and its Android story includes OpenCL and Hexagon acceleration paths that an iOS-only app has no reason to build. PocketPal is also MIT-licensed and its source is public, so the inference wiring can be inspected and forked.
The trade-off runs the other way on polish and support. A commercial app can bundle model curation, guarantee a tested device list, and answer support email. PocketPal's README leaves model selection to the user and its acceleration support is chipset-dependent. If you want a curated experience on an iPhone, the commercial option is defensible. If you want the same app on an Android phone and an iPad, or you want to read the llama.rn integration, PocketPal is the one that exists on both.
Maintenance, licensing, and what an upgrade costs
The repository is not archived, and the last push was on 2026-11-01. Releases are frequent: v1.21.2 on 2026-10-26, v1.21.4 on 2026-10-28, and v1.22.0 on 2026-10-30. The package.json version field is 1.22.0, matching the latest release tag.
The licence is MIT, which permits commercial use, modification, and redistribution provided the copyright notice and permission notice are retained. That is a permissive arrangement, but it is worth noting that the MIT grant covers the app's own code. The bundled engines are separate projects: llama.cpp and ONNX Runtime carry their own licences, and llama.rn and react-native-speech are third-party dependencies. Anyone redistributing a build should read those licences rather than assuming the MIT label covers the whole binary. This is not legal advice.
Upgrade cost is low for users, since App Store and Play updates are automatic. For developers tracking main, the cost is in native rebuilds: the postinstall script runs ./scripts/postinstall.sh and the repository carries a patches/ directory, and any change to llama.rn or the ONNX runtime requires a fresh native build on both platforms. The yarn ios:build script passes a long, fixed set of xcodebuild flags for the simulator SDK, so CI configuration will need attention whenever the Xcode toolchain moves.
Editorial conclusion
Adopt PocketPal AI if you want an offline chat client on a phone you already own, or if you are a React Native developer who wants a working llama.rn integration to read. Do not adopt it as a server-side inference platform; the architecture is explicitly on-device, and the hardware table lists only CPU, Metal/OpenCL GPU, and Qualcomm Hexagon NPU paths, plus the Apple Neural Engine for Phonon on iOS. Before relying on it, verify that your device's chipset appears in that acceleration table and confirm which model fits your phone's memory, since the README's quick start only tells you to pick one that fits your phone.
Frequently asked questions
What exactly is PocketPal AI?
It is a mobile app that runs language models and voice models directly on the phone rather than on a server. The README describes it as a private AI assistant that runs entirely on your phone, with on-device chat, text-to-speech, and tool use.
Is PocketPal AI free to use?
The app itself is free and MIT-licensed, and the README says chat, models, voices and tools are free with no account. The App Store and Google Play builds offer an optional one-time PocketPal Plus purchase for hands-free voice (builds from source include it), and PalsHub includes premium Pals via in-app purchase.
Is PocketPal AI safe and private?
The README states that every prompt, response, and document stays on your device unless you turn on an online feature: web search and page reading, a remote server, or a system voice your phone runs online. It says the app's other network use, such as model downloads, PalsHub, the opt-in benchmark leaderboard and feedback you submit, never attaches your chats.
Is PocketPal AI offline?
Yes. The README says you download a model once and it works with no connection and no account. The .env.example also exposes an ENABLE_OFFLINE_MODE feature flag, which indicates offline operation is a toggleable configuration rather than an accident of the architecture.
What is the best AI model for PocketPal?
The README does not name a best model. Its quick start says to pick a model that fits your phone, and it lists Gemma, Qwen, Phi, and Llama as supported GGUF families. The right answer depends on your phone's RAM and whether a GPU or NPU backend is available.
How do I use PocketPal AI for the first time?
Install it from the App Store or Google Play, open the menu and go to Models, then pick a model and tap Download. After the download completes, load the model and start chatting. The README also mentions adding a model from Hugging Face.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/a-ghorbani-pocketpal-ai)Star history chart for your README
[](https://hysenlabs.com/projects/a-ghorbani-pocketpal-ai)Was this useful?