qmd routes lex to BM25 and vec or hyde to the vector index, and running it off-host drops its own host check
mini cli search engine for your docs, knowledge bases, meeting notes, whatever. Tracking current sota approaches while being all local
At a glance
- What is it?
- qmd is a local search engine for markdown that fuses BM25 and vector results with reciprocal rank fusion before an LLM reranker sees them, all through node-llama-cpp and GGUF models. Its typed sub-queries never share a backend, its HTTP MCP transport exists to avoid reloading models per client, and binding it to 0.0.0.0 disables the Host validation (with only a startup warning) that protects your index from DNS rebinding.
- Who is it for?
- Adopt qmd when you want hybrid retrieval over markdown that never leaves the machine, and when an agent needs one CLI rather than a service to depend on. Do not adopt it if you need authentication on the search endpoint, since the HTTP transport is documented as unauthenticated and expects you to put your own auth in front of it, and do not bind it to a reachable interface without reading the origin rules first.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 29 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
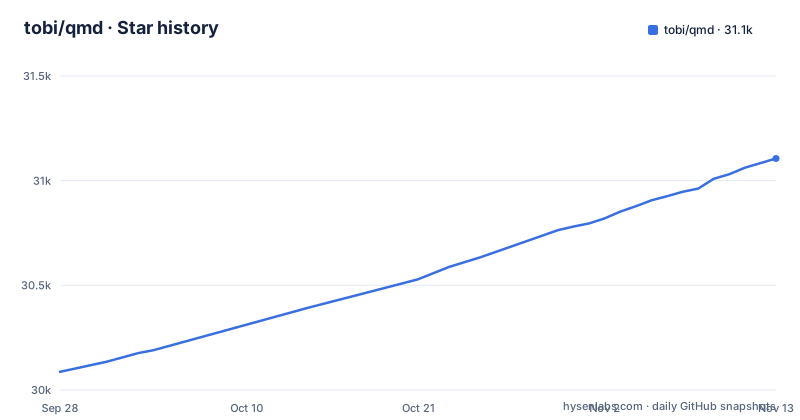
- tobi/qmd31,106 ★ · +1,019
| Repository | 2026-09-28 | 2026-11-13 |
|---|---|---|
| tobi/qmd | 30.1k | 31.1k |
1,019 Stars in the last 46 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Install is one global package, and the first real work is declaring collections
There are four ways to get the binary and they resolve to the same package name, `@tobilu/qmd`. Installing globally works under Node or Bun, and running it without installing goes through `npx` or `bunx`:
npm install -g @tobilu/qmd
bun install -g @tobilu/qmd
npx @tobilu/qmd ...
bunx @tobilu/qmd ...
After that the first real task is not searching but declaring what to search. Collections are added with a path and a name:
qmd collection add ~/notes --name notes
qmd collection add ~/Documents/meetings --name meetings
qmd collection add ~/work/docs --name docs
What makes collections more than a filter is the context attached to them. Each piece of context is returned when matching sub-documents are returned, and the structure works as a tree. The README calls this the key feature of QMD and gives the reason plainly: it lets a language model make much better contextual choices. A bare list of filenames gives a model no signal about what a folder contains or how it relates to the parent, whereas a returned context block does.
That design suits agentic workflows, which the README calls out. The stated purpose is an on-device search engine for everything you need to remember, covering markdown notes, meeting transcripts, documentation and knowledge bases, searchable by keyword or natural language.
lex goes to BM25, vec and hyde go to the vector index, and neither is shared
The retrieval pipeline has one rule worth internalising: typed expansions are routed exclusively. A sub-query typed `lex` goes to BM25 full-text search. Sub-queries typed `vec` and `hyde` go to vector search. HyDE, the hypothetical document embeddings step, and dense sentence vectors therefore land on the same backend and never reach the lexical index.
The original query is sent to both backends regardless. What the types control is the expansion queries, not the base query, so a natural-language request always has both a lexical and a semantic path. Their result lists are then combined with Reciprocal Rank Fusion, which merges rankings rather than scores, and an LLM reranker receives the fused list and produces the final ranked output.
The reranker is a toggle rather than a fixed stage. The `rerank` parameter defaults to true, and setting it to false gives you the Reciprocal Rank Fusion result alone, which is the cheaper path and the one to measure against. Fusion output size is controlled separately by `candidateLimit`, which caps how many candidates reach the reranker and defaults to 40, while `limit` caps what the caller finally receives and defaults to 10.
Everything in that chain runs locally. BM25, vector search and LLM re-ranking are all executed through node-llama-cpp with GGUF models, which is the whole reason the tool is described as on-device rather than as a thin client over a hosted index.
A singular collection key is silently ignored, and the first sub-query counts double
The parameter table is where the tool is most likely to bite you, and two entries in it are traps rather than documentation.
The first is `collections`. It is typed as an array, filtered by collection names with OR semantics, and the note says it is array only: the singular `collection` is silently ignored. Nothing errors, nothing warns, and the query returns results from every collection instead of the one you asked for. If you are filtering agent output, that failure looks like a relevance problem rather than a parameter problem.
The second is `searches`, the typed sub-query array. It holds between 1 and 10 entries, is required, and the first one gets 2x weight. Ordering therefore matters as much as typing: the expansion you list first is weighted double against the ones after it.
The rest of the surface is more forgiving. `minScore` takes a value from 0 to 1 and defaults to 0, so no relevance floor is applied unless you set one. `intent` supplies disambiguation context and explicitly does not search on its own, which makes it a hint for expansion rather than a filter. `filter` is a metadata filter expressed as a recursive, operator-discriminated JSON AST, and invalid filters are rejected with a 400 on the HTTP endpoint.
For retrieval, `get` takes a path, a docid such as `#abc123`, or a compact range form like `#abc123:120:40`. `fromLine` is 1-indexed and overrides the `:from` suffix, `maxLines` caps the output, and `lineNumbers` prefixes lines with numbers by default, which is what makes a citation in agent output checkable.
Four MCP tools, on a CLI that was already agent-ready
The README is candid that the MCP server is not the only way in: the tool works if you simply tell your agent to use it on the command line, and MCP exists for tighter integration. That ordering matters, because the CLI output formats were designed for agentic workflows first.
Two flags carry that design. `--json` returns structured results, and `--files` lists relevant files above a threshold:
qmd search "authentication" --json -n 10
qmd query "error handling" --all --files --min-score 0.4
qmd get "docs/api-reference.md" --full
The MCP surface then exposes five tools. `query` takes the typed sub-queries and combines them through fusion and reranking. `get` retrieves a document by path or docid and offers fuzzy matching suggestions when a path does not resolve. `multi_get` retrieves in batches by glob pattern, comma-separated list, or docids, with a `maxBytes` cap so a wildcard cannot pull an entire repository into a context window. `status` reports index health and collection information, which is the first thing to call when results look wrong. The fifth tool, `metadata`, discovers metadata keys, types and value counts to filter on.
There are three ways to attach it. Claude Desktop takes a JSON block in `~/Library/Application Support/Claude/claude_desktop_config.json` naming the `qmd` command with an `mcp` argument. Claude Code has a plugin route, which the README marks as recommended:
claude plugin marketplace add tobi/qmd
claude plugin install qmd@qmd
Otherwise the same server block goes into `~/.claude/settings.json` by hand. All three end at the same place, a subprocess speaking MCP over stdio.
The HTTP transport exists so models are not reloaded once per client
By default the MCP server runs over stdio, which means each client launches its own subprocess, which means each client loads its own copy of the models. For a shared, long-lived server the transport switches:
qmd mcp --http --daemon
qmd mcp stop
qmd status
The daemon mode writes its process id to `~/.cache/qmd/mcp.pid`, `qmd mcp stop` stops the server through that file, and `qmd status` reports `MCP: running (PID ...)` when it is active. Run in the foreground it binds `localhost:8181`, with `--port` for a custom port and `--host` to change the interface, or the `QMD_HOST` environment variable.
Four endpoints sit behind it. `POST /mcp` is MCP Streamable HTTP, answering with JSON in a stateless form. `POST /query`, aliased as `/search`, gives structured search without the MCP protocol and accepts the same optional filter object as the `query` tool, returning 400 for an invalid one. `POST /metadata` is metadata discovery without the MCP protocol, with the same body as the `metadata` tool. `GET /health` is a liveness check that includes uptime, which is what a container probe needs.
The line worth reading twice is the one about the host. `--host 0.0.0.0` cannot know which `Host` values are legitimate, so it skips the host check entirely and warns at startup. Binding all interfaces is described as useful when a liveness probe connects from a non-loopback address in a container, which is a narrow need with a broad consequence. The endpoints are unauthenticated, and the instruction is to put your own auth in front of a server reachable off-host. Clients connect to `http://localhost:8181/mcp`.
Loopback binding alone does not stop DNS rebinding, so Origin and Host are screened
The security section exists because a loopback server is not automatically a private one. The reasoning is spelled out: a web page you visit could read your index through DNS rebinding, and binding to loopback alone does not prevent that, since the browser makes the request from your own machine.
So every request is screened before routing. A request carrying an `Origin` header that does not name a loopback address is rejected with 403, and a `Host` header naming something other than the address the server is bound to is rejected the same way. Requests with no `Origin` header at all are unaffected, which covers curl, MCP clients and editors, so ordinary local use does not change.
Both checks can be widened through environment variables. `QMD_ALLOWED_ORIGINS` takes comma-separated origins to accept in addition to loopback, with an example of an internal notes host, and setting it to `*` disables the check entirely. `QMD_ALLOWED_HOSTS` takes comma-separated `Host` values to accept in addition to loopback and the bind address, and it is the variable to set if you ran with `--host 0.0.0.0` and want host validation back.
Memory behaviour is the other thing to understand before you run this as a service. LLM models stay loaded in VRAM across requests, so a warm server is warm. Embedding and reranking contexts are the exception: they are disposed after five minutes idle and transparently recreated on the next request, at a cost of about a second, while the models themselves stay resident. That is a reasonable trade for a workstation and worth measuring before you point a busy service at it.
The published tarball carries bin, dist and skills, while the repo keeps two lockfiles
The package manifest is explicit about what ships. The published files are `bin/`, `dist/`, `skills/`, four named scripts, the licence and the changelog. `src/`, `docs/`, `test/` and the rest of the repository are development-only, so an installed copy gives you the binary, the compiled output and the skill definitions rather than the source tree.
The repository is broader than the package, and the root shows the shape of the project: `bin/` for the CLI entry, `src/` for the implementation, `test/`, `docs/`, `tools/`, `skills/` and `.claude-plugin/` for the agent integration, `finetune/` for model work, `example-index.yml` as a sample index, and `migrate-schema.ts`, whose presence says the index has a schema that moves between versions.
Two lockfiles are committed, `bun.lock` and `pnpm-lock.yaml`, and the test scripts confirm both runtimes are first class rather than incidental. Tests run under vitest on Node and under `bun test` with a preload, and `test:unit` invokes both against the same `test/` directory. Linting uses `oxlint`, type checking runs `tsc` against a separate build config, and there is a package smoke test and a grammar check, both of which exist because the published tarball is not the same thing as the repository.
Versioning tells a small story of its own. Tags run v2.5.2 on 2026-05-22, v2.5.3 on 2026-05-29 and then v2.8.3 on 2026-08-16, a jump that suggests work landed in batches rather than a steady stream. The last push was 2026-10-15 and the repository is not archived, so the default branch sits ahead of the newest release. The licence is MIT.
Editorial conclusion
Adopt qmd when you want hybrid retrieval over markdown that never leaves the machine, and when an agent needs one CLI rather than a service to depend on. Do not adopt it if you need authentication on the search endpoint, since the HTTP transport is documented as unauthenticated and expects you to put your own auth in front of it, and do not bind it to a reachable interface without reading the origin rules first. Three things to verify in your own setup: that your client passes `collections` as an array, because the singular `collection` key is silently ignored and your filter will appear to work while returning unfiltered results; that you understand the two-way memory behaviour, where LLM models stay loaded in VRAM across requests while embedding and reranking contexts are disposed after five idle minutes and cost about a second to recreate; and that `QMD_ALLOWED_HOSTS` is set if you run with `--host 0.0.0.0`, since that flag skips host validation with only a startup warning. Version 2.8.3 was tagged on 2026-08-16 and the last push was 2026-10-15, so the default branch is ahead of the newest release.
Frequently asked questions
What does QMD do?
It is an on-device search engine for markdown files. It indexes notes, meeting transcripts, documentation and knowledge bases, then searches them with keywords or natural language by combining BM25 full-text search, vector semantic search and LLM re-ranking, all running locally through node-llama-cpp with GGUF models.
What are QMD files?
QMD stands for Query Markup Documents, and the tool works on ordinary markdown rather than on a special file format. You register directories as named collections with qmd collection add, and each piece of context attached to a collection is returned when matching sub-documents come back, as a tree, so a model gets context alongside the match.
How do you install qmd?
Globally with npm install -g @tobilu/qmd or bun install -g @tobilu/qmd, or without installing through npx @tobilu/qmd and bunx @tobilu/qmd. After that you add collections, for example qmd collection add ~/notes --name notes, and search with qmd search or qmd query.
How does qmd combine keyword search and semantic search?
The original query goes to both backends, and the typed expansions are routed exclusively: lex sub-queries reach BM25, while vec and hyde reach vector search. The two result lists are merged with Reciprocal Rank Fusion and then passed to an LLM reranker, which can be turned off with rerank false to leave the fusion output alone.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tobi-qmd)Star history chart for your README
[](https://hysenlabs.com/projects/tobi-qmd)Was this useful?