OpenCursor: it can sign in as other coding agents, and retry on a second credential
Open-source Cursor-like AI coding agent for VS Code — agentic chat, multi-provider LLMs (OpenAI, Ollama, llama.cpp), semantic search, and MCP support
At a glance
- What is it?
- A Visual Studio Code extension that brings agentic editing to the editor under your own model keys, including local models. Two design choices in it are worth understanding before you install: it can hold credentials issued to other agent products, and a failed request may be retried against a different account before any content comes back.
- Who is it for?
- Install it if you want agentic editing with your own provider keys and a local model option, and read the permission controls before your first real task. Do not install it expecting the offline story to be complete, because the document itself says web search, online documentation fetching and remote integrations still need their services even with a local model and local embeddings.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 18 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
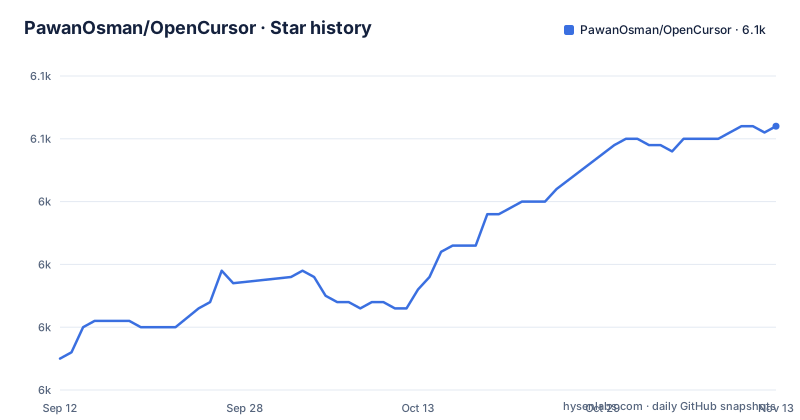
- PawanOsman/OpenCursor6,052 ★ · +37
| Repository | 2026-09-12 | 2026-11-13 |
|---|---|---|
| PawanOsman/OpenCursor | 6k | 6.1k |
37 Stars in the last 62 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
It can hold credentials issued to other agent products
The provider table has five rows and the first one is the one to read carefully. It is not a list of API vendors. It is a list of other agent products the extension can sign you in as: a Claude Code account, an OpenAI Codex account, a Gemini CLI account, GitHub Copilot, and several others, with the setup described as choosing a provider and following its browser, device code or token import flow.
So the extension does not only talk to model endpoints. It can obtain and hold credentials that were issued to a different product, using that product's own authentication dance, and then spend them from inside this extension.
That may be exactly what you want if you already pay for one of those and would rather not paste an API key. It also means the extension is a credential broker for services you did not install it for, and the browser or device code flow is where you should slow down and read what you are granting.
The rest of the table is the ordinary version of this problem: API providers where you add one or more keys, custom providers where you point at your own compatible endpoint with a base URL and credentials, local models through two runtimes, and one connection that needs no account or key at all.
Two honesty notes sit alongside the table and are worth crediting. Only providers you have configured appear in your provider list, and a catalog entry does not grant access to a model.
A failed request can move to a second credential
The paragraph about multiple accounts and keys describes more than balancing. Connections of the same provider are grouped with their own balancing settings, and you can choose first available or round robin routing. Account based providers that support it also expose quota aware choices.
Then there is one sentence that deserves to be read on its own: eligible failures can move to another credential before response content starts.
The qualifier is what makes it a sensible design rather than a surprising one. Once a response has started streaming, switching credentials mid stream would produce a spliced answer, so the failover happens before any content exists to splice. That is a clean rule, and it is stated.
The flip side is that your request may be answered by an account other than the one you selected. If you are tracking usage per account, or if one of your accounts has a different data agreement from another, that is the behaviour to know about.
Everything else in this area is model selection: the catalog and provider discovery expose what is available with reasoning, thinking and context controls, and availability and tool support depend on the provider and the account rather than on the catalog.
Fast mode needs the gateway to cooperate
There is a processing speed option in the model picker for the model families that support it, with the slower setting as the default and the faster one described as requesting priority processing without changing the reasoning setting. It can consume extra credits or a higher rate, and it requires both your account and your endpoint to support it.
The last sentence is the interesting one: custom gateways must forward the speed setting to the upstream provider.
That is an interoperability constraint stated honestly rather than a feature. If you route through your own gateway, the setting is not a client side flag you can switch on; it only takes effect if the gateway itself passes it along. So the fastest path to a confusing result is to enable the option, watch no difference, and conclude the model is slow when the request is simply being handled at the default priority.
The fact that the speed setting does not change the reasoning setting is the other thing worth knowing. Users often assume a fast mode implies reduced thinking, and here it explicitly does not, so you are trading credits and rate rather than quality.
Offline covers coding and search, and nothing else
The local inference section makes a promise and then draws the boundary, which is the right way round.
The promise: use an on device model together with local embeddings and you can work without a hosted model API. Once the required models and runtimes are installed, local coding and code search can work offline.
The boundary, in the next sentence: web search, online documentation fetching and remote integrations still require their respective services.
So an air gapped installation gets you a model, embeddings, retrieval and editing, and loses the three capabilities that need a network. That is a coherent product, not a broken one, but it means the word offline in this project's marketing covers less than a reader might assume.
The retrieval side has the same shape. Semantic search combines embeddings with lexical matching so a question can find code that uses different words from the implementation. The index updates incrementally, accounts for unsaved editor content, and checks that retrieved snippets are still current, which is the part that matters for an agent about to edit code.
Five modes, and only one of them writes to your project
The mode switch is the clearest statement of what the extension thinks an agent session is, and the split is deliberate.
Ask is read only. Plan can save a plan without editing project code. Agent carries out changes under the permissions you configured. Project and Multitask sit alongside those three.
So there is a mode where the model cannot modify your repository, a mode where it produces a plan and stops, and a mode where it acts. That separation is the difference between letting a model near a codebase and not letting it near one.
Around the modes sit the session mechanics: conversations can be forked or archived, and independent work can be delegated to subagents. The capability table adds the steering controls, which are unusually granular for this kind of tool. You can queue another request, edit or reorder the messages you have queued, steer a run that is already going, or send a new request immediately in order to interrupt it.
Change review is the other half. Changed files are listed, individual hunks can be reviewed in the editor, and there are two commands to keep everything or undo everything. That is a coarse instrument at the end of a fine grained one, which is the right way round.
One keybinding, seven commands, and one called Implement TODO
The manifest is worth reading for what it contributes rather than for what it depends on, because the contribution surface is small and specific.
The keybinding the README describes adds the editor selection to the chat, bound to a modifier plus the letter L, on Windows and Linux, the equivalent on macOS, and gated on the editor having text focus. One shortcut for the one action that needs to be reachable while you are reading code.
Then there are seven commands, and two of their titles tell you more than the documentation does. One is titled Implement TODO. The other is titled Remote Jobs.
The activation event list is empty, which is the modern correct thing to do: the editor derives activation from the contributed views and commands rather than from a declared event. It also means the extension does not load until something in it is used.
The interface itself is a webview hosted in a sidebar container, which is why the repository has a separate directory for the interface code and a second compiler configuration for it.
Two bundler files, two compiler configs, two test runners
The build layout says this is a project with two compilation targets and two kinds of test, and that somebody has thought about keeping them straight.
For the build there are two files whose names both start with the name of the bundler: one that appears to hold the options and one that appears to hold the logic. That split is not required by the tool and is usually a sign of a build that grew a second entry point, most likely the webview.
For types there are two compiler configurations, one for the extension and one for the webview, which is the minimum needed if the interface is a separate application with its own module resolution and its own dependencies.
For tests there are two runners. One configuration runs unit tests. The other file at the repository root runs tests against an actual editor instance, which is how you test the parts that only exist when the extension is loaded: commands firing, views rendering, a keybinding resolving.
Two smaller details round it out. The package manager is a workspace one, with a workspace definition file and a lock file in that format rather than the more common single lock file, which matters if you are contributing and want to reproduce an install. And the extension declares a marketplace publisher that differs from the account that owns the repository, which is normal for published extensions and is one more identifier to keep straight when filing an issue.
Three releases in two weeks, and the last commit lands after the newest tag
The three most recent releases are 0.1.5 on 2026-09-22, 0.2.0 three days later on 2026-09-25, and 0.2.1 on 2026-10-26. The default branch was last pushed on 2026-10-26 at 23:18 UTC, and the newest tag went out the same evening at 23:14.
So the last push came four minutes after the newest release, and the release numbers show a project that is still finding its shape, with the version still below one.
That cadence has a consequence for anyone pinning. A minor version three days after a patch suggests the versioning is following intent rather than stability, so the sensible approach is to pin an exact version and read the change log file at the repository root before upgrading, rather than tracking the branch.
The readme itself carries a small oddity in the same area. It opens with a copyright header inside a comment block, naming the author, the year, the project and the licence. That is a source file header convention, applied to a documentation file where nobody will see it once the page renders.
Editorial conclusion
Install it if you want agentic editing with your own provider keys and a local model option, and read the permission controls before your first real task. Do not install it expecting the offline story to be complete, because the document itself says web search, online documentation fetching and remote integrations still need their services even with a local model and local embeddings. Three things to check. It can hold credentials issued to other agent products through a browser or device code flow, so know what you are authorizing when you add one of those accounts. A request that fails can move to a different credential of the same provider before response content starts, which is useful and also means your traffic can land on an account you were not thinking about. And the priority processing setting only works if a custom gateway forwards it. Licence is MIT, the manifest asks for a recent editor version, the newest release is 0.2.1, and the default branch was pushed on 2026-10-26.
Frequently asked questions
what is open cursor
OpenCursor is an open-source AI coding agent that runs inside Visual Studio Code as an extension. It brings conversation, code exploration, file edits, terminal commands and change review into the editor, works with your own API keys or with a local model through Ollama or llama.cpp, and adds semantic search over the workspace plus support for the Model Context Protocol. It requires Visual Studio Code 1.96 or newer and is MIT licensed.
open cursor vscode
It is a Visual Studio Code extension, distributed through the marketplace under one item name and also as a downloadable package you can install with the editor's install from package command. The manifest declares a minimum editor version of 1.96, and the interface lives in a sidebar as a webview rather than in a separate application window.
Can OpenCursor use a model running on my own machine?
Yes. You can point it at an Ollama endpoint, browse installed models, pull new ones and load or unload them, or manage a llama.cpp runtime with downloaded model files, choosing a quantization and configuring context size, GPU layers and cache. With an on device model and local embeddings, local coding and code search work offline, though web search, online documentation fetching and remote integrations still need their services.
What is the difference between Ask, Plan and Agent in OpenCursor?
Ask is read only. Plan can save a plan without editing project code. Agent carries out changes under whatever permissions you have configured. Two further modes, Project and Multitask, sit alongside them. Conversations can also be forked or archived, and independent work delegated to subagents.
Does OpenCursor compare itself with other coding agents?
Only in passing: the repository description calls it an open-source Cursor-like AI coding agent for VS Code. What it does document is its own surface: five modes, a provider table that includes logins to other agent products, local inference through two runtimes, and hunk level change review with keep all and undo all commands.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pawanosman-opencursor)Star history chart for your README
[](https://hysenlabs.com/projects/pawanosman-opencursor)Was this useful?