Aden Hive: queen agents, worker clones and a SQLite tracker on your disk
Multi-Agent Harness for Production AI
At a glance
- What is it?
- aden-hive/hive is an Apache-2.0 Python runtime where a long-lived queen agent pilots one unit of work, saves the method as a skill, then fans the rest out to worker clones that write into a shared SQLite table. The design is easy to audit, but it assumes one machine's disk and a repository install path that is easy to get wrong.
- Who is it for?
- Hive suits teams who want agent work they can inspect row by row, with state in a SQLite file they can query and resume from, and who are fine running Python 3.11+, Node.js 20+ and a local dashboard. It is a weaker fit if you want a predrawn workflow graph or a pip install from a cloned checkout.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 8 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
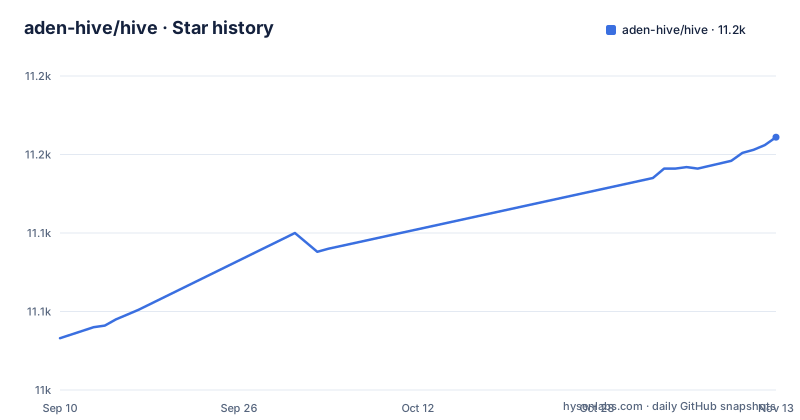
- aden-hive/hive11,161 ★ · +128
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| aden-hive/hive | 11k | 11.2k |
128 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The queen does one unit herself before any worker starts
Hive's central idea is a pilot run. You hand a task to a queen, a long-lived agent with a role such as Head of Growth, plus its own memory and tools. The queen can ask a clarifying question, then proposes a colony that you approve. Before fanning out, she completes one unit herself to learn what the job takes and saves that method as a reusable skill.
The demo in the README shows why this matters. A growth team asks how five developer tools' launches did on Hacker News. The queen takes PostHog first, decides what counts as a genuine launch post, checks numbers against the Hacker News API, and saves the method. Workers then follow that skill. When Cal.com's worker counted a post under its old name Calendso that was not a Show HN, Launch HN or YC launch, the queen cleared the row, and the chart showed Cal.com as not found rather than zero.
run_worker returns immediately and caps concurrency at four
Hive has one execution primitive, the agent loop. The queen is one loop, and every worker is a clone of it with its own task, a narrower tool set and a strict budget. Orchestration happens through tool calls rather than a compiled graph.
The run_worker call fans tasks out and returns at once, so the queen keeps talking to you while workers run. Four workers run at a time by default and the rest wait their turn. Each worker's report arrives in the queen's conversation as a new turn. The practical effect is that a colony of fifty units does not start fifty agents together; it drains in batches of four unless you change the default, so wall-clock time grows with the number of units even though the conversation stays responsive.
Colony state is one SQLite file under ~/.hive
The tracker is the colony's shared state. The queen defines the table and which columns workers may write, workers upsert one row per unit of work through tracker_upsert, and the queen checks progress with SQL. The table lives at ~/.hive/colonies/<name>/tracker/tracker.db.
This is the project's strongest property and also a boundary. Because progress is a file on disk rather than a context window, you can open it, audit it, export it and resume from it after a crash. The flip side is that it lives in one user's home directory on one machine. Nothing on the README's front page describes sharing a tracker between hosts, so a colony is tied to wherever ~/.hive sits. Back that directory up if a run matters, and do not expect a second machine to see the same colony.
run_playbook re-derives what is left from the tracker
Once a method is proven, run_playbook applies it over every row. It adds retries with backoff, rate-limited lanes and a dead-letter list for rows that keep failing. The key design choice is that "what's left" is always a fresh query of the tracker, so re-running a playbook picks up where it stopped instead of starting over.
That makes interruption cheap, but it also means the tracker is the single source of truth. If a worker writes a wrong value into a row, the playbook treats that row as done. In the demo it was the queen's final row check that caught the Calendso mistake, not the playbook. Rows in the dead-letter list still need a person or the queen to look at them; retries alone do not resolve a unit that fails for the same reason every time.
pip install -e . at the repository root installs a placeholder
The repository is a uv workspace whose members are core and tools, and that layout breaks the usual habit. Running pip install -e . at the root installs a placeholder that will not run. From a checkout, use the quickstart:
git clone https://github.com/aden-hive/hive.git
cd hive
./quickstart.sh          # macOS / Linux
.\quickstart.ps1         # Windows (PowerShell 5.1+)
Without cloning, install from PyPI and then run hive open:
pip install "aden-hive[tools]"To build your own project on Hive's agent loop and models, depend on aden-hive. Optional pieces such as a chat-app channel are separate packages. Anyone scripting a CI or container install from the cloned repository should call the quickstart or the PyPI package rather than an editable pip install, or they will get an install that looks successful and does nothing.
The quickstart needs Python 3.11, Node.js 20 and a model
Requirements are Python 3.11 or later, Node.js 20 or later and git. The quickstart installs uv and ripgrep if they are missing and offers to install Node. It creates a single Python environment for the workspace, stores your API key encrypted under ~/.hive, asks which model to use, builds the dashboard and opens it at http://127.0.0.1:8787. Later sessions start with hive open from the repository.
Model access can come from an API key for Anthropic, OpenAI, Google Gemini, Groq, Cerebras or OpenRouter; from an existing coding subscription to Claude Code, OpenAI Codex, Kimi Code, MiniMax, Z.AI or Antigravity; from Hive LLM; or from a local model through Ollama with no key. Hive ships thirteen persona queens, six of them active out of the box, including Growth, RevOps, Content, Lead Generation and Outbound.
package.json still says 0.1.0 and adenhq while releases reach v1.0.14
The release line is moving quickly: v1.0.12 on 2026-10-24, v1.0.13 on 2026-10-26 and v1.0.14 on 2026-11-02, with the last push the same day. The root package.json has not kept pace. It declares version 0.1.0, describes the project as "Hive - Aden Agent Framework - Build goal-driven, self-improving AI agents" and points its repository URL at github.com/adenhq/hive rather than aden-hive/hive. That file is private and only drives frontend scripts in core/frontend, so the mismatch does not break installs, but it means you should read versions from the release tags and CHANGELOG.md, not from package.json.
For contributors, the Makefile separates make test-tools, which uses mocked tools and needs no credentials, from make test-live, which runs live integration tests and requires real API credentials.
Editorial conclusion
Hive suits teams who want agent work they can inspect row by row, with state in a SQLite file they can query and resume from, and who are fine running Python 3.11+, Node.js 20+ and a local dashboard. It is a weaker fit if you want a predrawn workflow graph or a pip install from a cloned checkout. Before committing, decide which model access you will use, run the quickstart rather than pip install -e ., and confirm where ~/.hive will live on the machine that runs your colonies.
Frequently asked questions
Is Aden Hive free?
The aden-hive/hive code is open source under the Apache-2.0 license. It still needs a model: an API key, an existing coding subscription, Hive LLM, or a local model through Ollama with no key.
What is Hive in AI, as built by Aden?
Aden Hive is an open-source runtime for colonies of AI agents. A queen agent pilots one unit of work, then hands the rest to parallel worker clones that write results to a shared SQLite tracker.
Is Aden, the company behind Hive, a real company?
The Hive README links to a Y Combinator company page for Aden and to Aden's X and LinkedIn accounts. The project itself is published on GitHub as aden-hive/hive under Apache-2.0.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/aden-hive-hive)Star history chart for your README
[](https://hysenlabs.com/projects/aden-hive-hive)Was this useful?