aws/context-ontology-accelerator: what the Scan, Model, Serve pipeline actually gives an agent
An open-source, ontology-based semantic context accelerator that enables AI agents to make more accurate, consistent, and explainable decisions.
At a glance
- What is it?
- An AWS-published, Apache-2.0 semantic context layer that wires ontology induction, SPARQL federation and MCP tooling into one Python monorepo. It is a build-it-yourself foundation for teams already committed to AWS CDK, not a drop-in context store.
- Who is it for?
- The accelerator is a starting point for AWS teams exploring ontology-based context for agents, with CDK infrastructure and a substantial development toolchain. An ontology and reasoning layer can support structured context and validation, but do not guarantee that every retrieved fact or agent action is correct or traceable.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
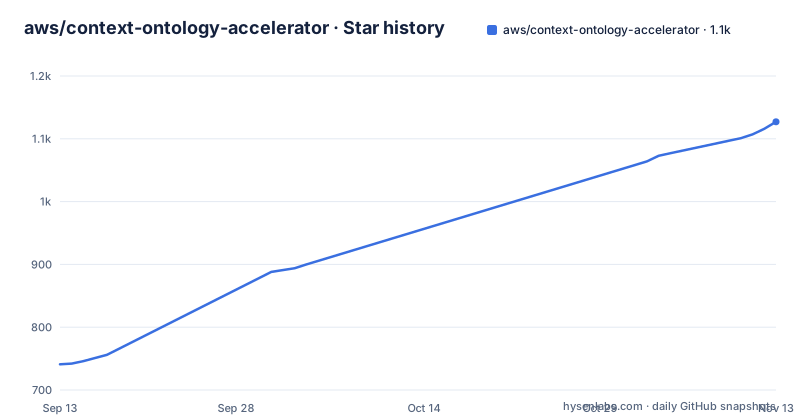
- aws/context-ontology-accelerator1,127 ★ · +386
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| aws/context-ontology-accelerator | 741 | 1.1k |
386 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem is context that cannot be checked after the fact
Retrieval-augmented agents return passages. A passage can be relevant and still be wrong for the decision at hand, and nothing in a vector store tells you which business rule the answer violated. This project combines ontologies and rules with data access, aiming to help agents retrieve context and validate it against business logic. Whether a particular fact or action is validated depends on the implemented workflow and rules; the architecture alone is not a correctness guarantee. The README describes the goal as enabling agents to "retrieve context, validate it against business logic, and determine correct actions." The audience is narrow. It is for platform teams inside AWS shops who have heterogeneous sources (databases plus unstructured documents), a compliance or consistency requirement, and the appetite to run a knowledge graph. It is not for a single-team prototype that needs a context window filled by Friday.
Scan, Model, Serve is three workloads wearing one repository
The README states the workflow as Scan, then Model, then Serve. Scan covers connecting data sources, discovering schemas, enriching metadata and ingesting unstructured documents. Model covers inducing and managing ontologies, defining metrics, and building a unified semantic graph. Serve covers querying through SPARQL federation in the Virtual Knowledge Graph, traversing the graph, and handing context to agents over MCP. The repository layout shows these are separate Python packages rather than one service: packages/sources for ingestion, packages/ontology-engine for induction and reasoning, packages/metric-service for metric authoring, packages/vkg for the Ontop-backed virtual graph, packages/context-manager for query orchestration and upstream clients, and packages/mcp-server for the agent-facing tools. Reasoning is delegated to HermiT and ELK, which the README lists under ontology-engine. Reasoner capabilities and resource needs differ; check the deployed version's configuration and benchmark the relevant ontology before choosing a reasoning workflow. The API surface is not hand-written. models/ holds Smithy definitions as the source of truth, and smithy-generated/ is produced from them into OpenAPI, Python interfaces and a TypeScript client.
Getting it running means a full toolchain, not a pip install
The prerequisites list is the honest signal of scope: Python 3.12, Node.js 22 or later, Docker, pnpm, Java 17 with Gradle for Smithy codegen, and uv for Python packages. The README's setup block is four commands after cloning. Clone at a release tag rather than main, because the README says main tracks ongoing development and recommends starting from a tagged release. Then make setup, make format, make lint, make test. The full developer guide lives at external-docs/content/getting-started.md, which is the file to read before anything else. Deployment is not in the quick start at all. It sits in infra/, an AWS CDK project in TypeScript with foundation and per-service stacks, and in scripts/, described as CI-agnostic build, test and deploy scripts. So the realistic first day is: install Java and Gradle, run the Smithy codegen, confirm the generated OpenAPI matches what you expect, then read the CDK stacks to see which AWS resources get created on your account before you run a deploy.
Authorization is namespace-scoped, and that shapes your team topology
Access is governed by namespace isolation plus role-based access control. There are namespace-scoped roles (owner, maintainer, data-steward, data-analyst) and platform-level roles (platform-admin, platform-viewer) that apply across all namespaces. The control-plane README is cited for the grants and authorization model, and that is where the real detail lives. The design choice worth noting is that platform roles cut across namespaces while the rest do not. In practice that means the person who can see everything is a distinct, small set, and day-to-day ontology edits happen inside a namespace boundary. If your organisation has one central data team and several consuming teams, the mapping is not automatic: you have to decide whether the central team holds platform-admin or whether each consuming team owns a namespace with its own maintainer. The README does not resolve that for you.
The repository is a read-only mirror, which caps your options
This is the constraint that should decide the evaluation. The README states plainly that the repository is published as a read-only mirror and that pull requests are not being accepted at this time. Bugs and feedback go through GitHub Issues. There is a note pointing Amazon employees to CONTRIBUTING.md for direction. A locally maintained fork is one option for a fix that has not landed upstream; another is to report the issue and track the project's response. A fork adds maintenance across the codebase and its generated interfaces. The release cadence is roughly weekly across v0.2.1, v0.2.2 and v0.3.0, all within about three weeks. Frequent releases are good for picking up fixes and bad for fork maintenance, because rebasing your patch onto each tag is recurring work. Budget for that before you build a critical path on top of it.
Where it is the wrong tool, and what to use instead
If your problem is document question answering over a corpus that changes daily, this is heavy machinery. You would be running ontology induction, a reasoning engine and a virtual knowledge graph to answer questions a chunk-and-embed pipeline handles adequately. The alternative that fits that case is a plain retrieval stack: chunk documents, embed them, store vectors, retrieve top-k. The difference in approach is the direction of validation. A vector store alone typically ranks by similarity; a retrieval application can also add filters and rule checks. This project aims to make ontology-based context available to agents, but verify which validation steps actually run in your configuration instead of assuming every result is checked before delivery. A second case: if you cannot deploy into an AWS account with CDK, review the current deployment and development documentation to determine which components can be run locally and which require AWS services.
Licence, dependencies and the maintenance bill
The project is Apache-2.0. The README includes an external dependencies section that names owlready2 under LGPL-3.0 as the listed dependency, with the usual Amazon disclaimer that the list is provided for convenience and is not guaranteed complete or current. That is a real consideration rather than boilerplate: LGPL-3.0 and Apache-2.0 are not the same terms, and the README itself says to consult your company's open source approval policy before proceeding. This is not legal advice; treat it as a prompt to route the dependency list through whoever handles that at your organisation. On maintenance: the moving parts are Python, TypeScript, Java and Gradle, plus pnpm and uv as package managers and Nx for monorepo orchestration. Each of those has its own upgrade treadmill, and mypy is configured strict, so static checks can catch some incompatible type changes, but they do not eliminate runtime failures. That is a good property, and it is also work.
Who should adopt it, and the two checks to run first
Adopt it if you are on AWS, you already run CDK, and you want to evaluate structured ontology-based context alongside your existing retrieval and validation controls. The MCP server package is the piece that makes the graph reachable from an agent, and the Smithy models mean the API contracts are versioned in the repository rather than in prose. Do not adopt it if you need a hosted service, if you cannot accept a read-only mirror with issue-only feedback, or if the team that would own it does not have Java and Gradle in its build environment. Two checks before you commit. First, clone the release tag and run its documented Smithy generation and validation workflow, checking for unexpected changes in generated artefacts. Second, read packages/control-plane/README.md and map its namespace-scoped and platform-level roles onto real people, because the authorization model is the part that determines whether the thing is usable by more than one team.
Editorial conclusion
The accelerator is a starting point for AWS teams exploring ontology-based context for agents, with CDK infrastructure and a substantial development toolchain. An ontology and reasoning layer can support structured context and validation, but do not guarantee that every retrieved fact or agent action is correct or traceable. Before deploying, review the chosen release, generated interfaces, authorization roles, cost and data handling, and test the actual workflow against your requirements.
Frequently asked questions
What is the AWS Context Ontology Accelerator?
An open-source semantic context layer for AWS that combines knowledge graphs, formal ontologies and rule-based systems with AI. It follows a Scan, Model, Serve workflow: connecting data sources and discovering schemas, inducing ontologies and building a unified semantic graph, then serving context to agents through federated query and the Model Context Protocol.
Can I contribute to context-ontology-accelerator with a pull request?
Not at the moment. The repository is published as a read-only mirror and is not accepting pull requests. Bugs and feedback go through GitHub Issues, and the contributing document includes direction for Amazon employees.
How is access control handled in context-ontology-accelerator?
By namespace isolation plus role-based access control, with namespace-scoped roles for owner, maintainer, data-steward and data-analyst, and platform-level roles for platform-admin and platform-viewer that apply across all namespaces. The grants and authorization model are documented in the control-plane package.
What do I need to build context-ontology-accelerator?
Python 3.12, Node.js 22 or newer, Docker, the pnpm and uv package managers, and Java 17 with Gradle for the interface code generation step. The setup instructions recommend cloning a tagged release rather than the main branch, then running the setup, format, lint and test targets.
What external dependencies does context-ontology-accelerator declare?
The table lists one package, an LGPL-3.0 ontology library for Python, alongside a notice that the list is provided for convenience and is not promised complete or current. The build and test toolchains are pinned separately in the manifests, including the type checker and the monorepo tool at exact versions.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/aws-context-ontology-accelerator)Star history chart for your README
[](https://hysenlabs.com/projects/aws-context-ontology-accelerator)Was this useful?