HikariCP: a JDBC connection pool in 165Kb
HikariCP: a solid, high-performance JDBC connection pool, at last.
At a glance
- What is it?
- HikariCP is a small, fast JDBC connection pool for Java 11 and later. It is the default pool in Spring Boot, and the README's configuration list is where most of the real work happens.
- Who is it for?
- Adopt HikariCP if you run a JVM application that talks to one relational database over JDBC and want a pool that stays out of the way; the Maven artifact is one dependency and the configuration surface is short. Do not adopt it if you need a pool that spans process boundaries, because HikariCP lives inside your JVM and cannot be shared between applications the way PgBouncer can.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 153 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
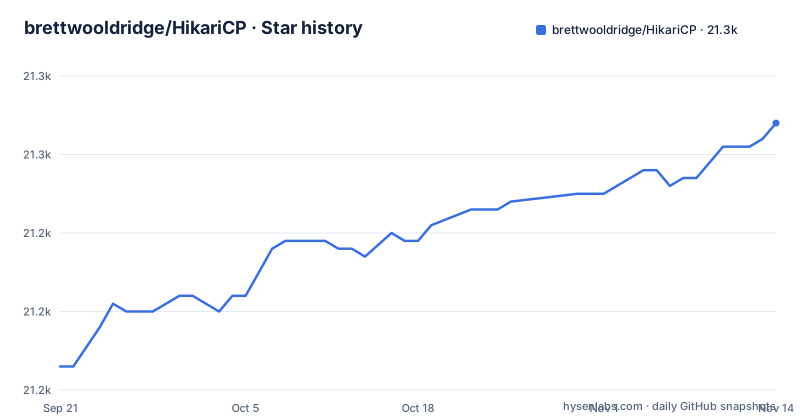
- brettwooldridge/HikariCP21,254 ★ · +31
| Repository | 2026-09-21 | 2026-11-14 |
|---|---|---|
| brettwooldridge/HikariCP | 21.2k | 21.3k |
31 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What HikariCP actually replaces
Opening a JDBC connection is expensive, and most server applications open and close them constantly. HikariCP sits between your code and the driver as a DataSource, handing out connections that are already open and taking them back on close(). The README calls it a "zero-overhead" production ready JDBC connection pool and puts the library at roughly 165Kb, which matters if you are shipping a fat jar or a container image and every dependency counts.
The audience is narrow and specific: JVM applications that reach a relational database through JDBC. If you use Spring Boot, you may already have it without asking for it, since HikariCP is the pool Spring Boot picks by default. If you use a non-JDBC data path, or you want pooling that sits outside the application process, this is not the tool for that job.
The design bet: fewer moving parts, fewer threads
The README's own framing is a Dijkstra quote about simplicity being a prerequisite for reliability, and the wiki page it links to is titled "Down the Rabbit Hole." That is the whole thesis: rather than adding background machinery, HikariCP keeps the pool small and the code paths short.
What you can confirm from the repository is the shape of the project. There is a single Maven module described by pom.xml, a src/ tree, a CHANGES file that carries release history, and a documents/ directory holding the longer analyses such as Welcome-To-The-Jungle.md. The README points to a separate repository, HikariCP-benchmark, for the JMH microbenchmarks, so the benchmark harness is deliberately kept out of the library artifact. That separation is a design choice worth noting: the pool you depend on does not drag the benchmark code with it.
The README defines its two benchmark units precisely. One connection cycle is a single DataSource.getConnection() followed by Connection.close(). One statement cycle is a single Connection.prepareStatement(), Statement.execute(), Statement.close(). If you want to reproduce anything, those are the operations being measured, and the benchmark project is where you would run them.
Installing HikariCP from Maven Central
The README gives the Maven coordinates directly. For Java 11 and later, the current artifact is version 7.1.0 under the com.zaxxer group. Add this to your pom.xml:
<dependency>
   <groupId>com.zaxxer</groupId>
   <artifactId>HikariCP</artifactId>
   <version>7.1.0</version>
</dependency>
There are older artifacts for older runtimes, and the README marks all of them deprecated: 4.0.3 for Java 8, HikariCP-java7 2.4.13 for Java 7, and HikariCP-java6 2.3.13 for Java 6. If you are on a modern JDK, use the plain HikariCP artifact and ignore the rest. The README also links to a Maven Central search for com.zaxxer.hikaricp as an alternative to copying coordinates.
Once the dependency resolves, the first real use is constructing a HikariConfig, pointing it at a JDBC URL, and building a HikariDataSource from it. The README's configuration section is organised into Essentials, Frequently used, and Infrequently used groups, which is the order to read them in. Start with the essentials, set the JDBC URL and credentials, and leave the rest at their defaults until you have a reason.
One configuration item is not optional in spirit. The README carries an important note that to avoid a rare condition where the pool goes to zero and does not recover, you must configure TCP keepalive. Some drivers expose it as a property, and the README gives tcpKeepAlive=true on PostgreSQL as an example. Otherwise it can be set at the operating system level, and the README links to its own wiki page on driver or OS TCP keepalive plus a PostgreSQL-focused article. Treat this as part of installation, not as tuning.
Where HikariCP is the wrong choice
The pool lives inside your JVM. If you run ten application instances, you get ten pools and ten sets of connections against the database. There is no shared pool process, so HikariCP cannot reduce the total connection count across a fleet. That is the boundary that decides between HikariCP and PgBouncer, and the two are not substitutes: PgBouncer is a separate server that multiplexes client connections before they reach PostgreSQL, while HikariCP manages connections within a single process.
The README's own analysis cuts against the instinct to raise the pool size. The section on pool sizing, subtitled "What you probably didn't know about connection pool sizing," cites an Oracle Real-world Performance demonstration where too many connections had a clear negative impact, described as a 50x difference in that demonstration. The README also documents a failure mode in other pools in a page titled "Bad Behavior: Handling Database Down," and notes that Apache Tomcat and Apache DBCP failed to complete the statement benchmark due to excessive garbage collection times. Those are claims about other projects, made by this project, and you should read them as such.
The limitation to internalise is that HikariCP is a library, not a service. It has no cross-process coordination. If your problem is "the database is overwhelmed by too many connections from many hosts," a pool inside each host does not solve it.
How it compares with c3p0 and Hibernate's pool
Both c3p0 and HikariCP are in-process JDBC pools, so the difference is not architectural placement but implementation weight and maintenance. The README's benchmark chart lists HikariCP 2.6.0 against commons-dbcp2 2.1.1, Tomcat 8.0.24, Vibur 16.1, and c3p0 0.9.5.2 on Java 8u111, with a note that Tomcat and DBCP both failed to finish the statement benchmark because of garbage collection times. Those numbers are from the project itself and from an older release line, so treat them as the project's argument rather than a neutral measurement.
The Hibernate comparison is a different kind of question, because Hibernate is an ORM, not a pool. Hibernate needs a connection provider, and HikariCP can serve as one. Asking "HikariCP vs Hibernate" is really asking whether to replace the ORM's built-in pooling with HikariCP, and that is a configuration change inside Hibernate rather than a choice of one library over another.
For c3p0 specifically, the practical difference is the configuration surface. c3p0 exposes a large set of tuning knobs; HikariCP's README organises its knobs into three tiers: Essentials, Frequently used and Infrequently used. If you have a c3p0 configuration that works and you have no performance problem, migrating buys you little. If you are starting fresh on Java 11 or later, the deprecated Java 6 and Java 7 artifacts are a signal about where the project's attention goes.
Maintenance, licensing and upgrade cost
The repository is not archived, and the last push was on 2026-06-14. The default branch is dev, so the README you read on GitHub may describe code that is ahead of the released artifact; if you want the version you actually depend on, read the CHANGES file and the Maven Central listing rather than the branch head.
The licence is Apache-2.0, which is a permissive licence that generally allows commercial use and modification, but this is not legal advice and your organisation's own review decides what that means for you.
Upgrade cost is low by design. The library is one Maven dependency with no transitive framework to align, and the README's configuration tiers mean the settings you touch are few. The real upgrade risk is version alignment with your JDK: the README maintains separate artifacts for Java 6, 7, and 8, all marked deprecated, so a project pinned to one of those is on a branch of the project that the README itself discourages. The other recurring cost is the TCP keepalive requirement. It is an operating system or driver setting, not a HikariCP setting, so it lives outside your dependency file and can be missed when you move between environments.
Editorial conclusion
Adopt HikariCP if you run a JVM application that talks to one relational database over JDBC and want a pool that stays out of the way; the Maven artifact is one dependency and the configuration surface is short. Do not adopt it if you need a pool that spans process boundaries, because HikariCP lives inside your JVM and cannot be shared between applications the way PgBouncer can. Before you commit, verify two things in your own setup: that your JDBC driver or operating system has TCP keepalive enabled, since the README warns about a rare condition where the pool goes to zero and does not recover, and that your pool size is not larger than the database can usefully serve, because the README's own analysis argues that too many connections hurt throughput.
Frequently asked questions
What is HikariCP used for?
It is a JDBC connection pool: it hands out already-open database connections to a JVM application and takes them back when the application closes them. The README describes it as a zero-overhead production ready JDBC connection pool of roughly 165Kb.
How do I configure the HikariCP connection pool?
The README organises its configuration options into Essentials, Frequently used, and Infrequently used groups, and you start by setting the JDBC URL and credentials on a HikariConfig before building a HikariDataSource. One setting the README calls out as necessary is TCP keepalive, which may be a driver property such as tcpKeepAlive=true on PostgreSQL or an operating system setting.
What are the differences between HikariCP and C3P0 connection pools?
Both are in-process JDBC pools, so the difference is implementation weight and tuning surface rather than where the pool runs. The README's benchmark chart lists HikariCP 2.6.0 against c3p0 0.9.5.2 among others, and those figures come from the project itself rather than an independent measurement.
What is HikariCP in Spring Boot?
It is the JDBC connection pool that Spring Boot uses by default, so a Spring Boot application talking to a relational database through JDBC is already running it. The README documents the pool and its configuration options.
What is a Hikari pool?
It is HikariCP's pool of open JDBC connections, held inside your application process and handed out through a DataSource. The README's warning about the pool going to zero and not recovering is why TCP keepalive has to be configured.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/brettwooldridge-hikaricp)Star history chart for your README
[](https://hysenlabs.com/projects/brettwooldridge-hikaricp)Was this useful?