Celery: a distributed task queue for Python, and what its docs actually commit to
Distributed Task Queue (development branch)
At a glance
- What is it?
- Celery is a Python library that moves work out of the request path and onto dedicated worker processes, using a message broker to carry tasks between them. This review covers what the 5.6.x line supports, how a first app is wired up, and where the project's own documentation stops short.
- Who is it for?
- Celery is the right choice if you have Python work that must leave the request path and you are willing to run a broker, usually RabbitMQ or Redis, alongside it. It is the wrong choice if you need Windows support the maintainers stand behind, or if your workload is a single scheduled job that a cron entry would cover.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
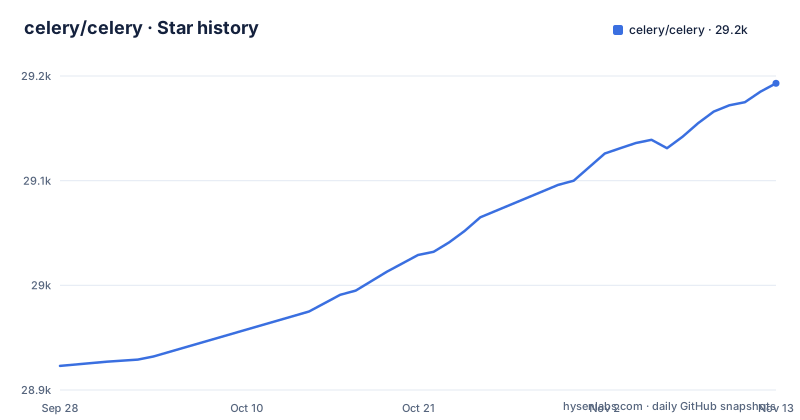
- celery/celery29,193 ★ · +270
| Repository | 2026-09-28 | 2026-11-13 |
|---|---|---|
| celery/celery | 28.9k | 29.2k |
270 Stars in the last 46 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem Celery solves, and who ends up using it
A web request has a budget measured in milliseconds. Some work does not fit in it: sending mail, resizing an image, calling a slow third party, running a nightly aggregation. Celery exists to move that work out of the request and onto separate processes that pull from a queue. The README states the model plainly: a client puts a message on a queue, a broker delivers it to a worker, and the worker runs the task. Nothing in that sentence requires the client and the worker to be on the same machine, which is the point. The same design scales from one process on a laptop to workers spread across datacenters, and the project says so.
The audience is Python teams that already run a broker or are willing to. Celery is not a scheduler you drop into a single process, and it is not a general job runner for shell scripts. It is a library plus a worker binary, and the worker is the thing you deploy. If your application is a Django or Flask service with a handful of slow endpoints, that is the shape Celery was built for. The repository even ships an examples/django/ directory, which tells you the maintainers expect that pairing.
One detail worth noticing early: the README calls the protocol language-agnostic and points at clients for Node.js, PHP, Go and Rust. Treat cross-language use as a direction the project supports through those third-party clients.
Broker, worker, result backend: the three moving parts
Celery's architecture is best understood as three roles. The broker carries messages. The worker consumes them and executes task functions. The result backend, optional, stores return values and task states for later retrieval. The README says RabbitMQ and Redis transports are feature complete, and that there is experimental support for other solutions, including SQLite for local development. That word experimental is the maintainers' own, and it is the single most useful sentence in the README for anyone choosing a transport. If your broker is not RabbitMQ or Redis, you are on a path the project itself labels experimental.
Configuration is code, not files. The README makes a point of this: Celery does not need configuration files. You construct an app object with a broker URL and decorate functions as tasks. The worker then discovers those tasks by importing your module. That inversion surprises people coming from cron or from a config-driven queue.
Scaling is horizontal by construction. Multiple workers, multiple brokers, and the README's claim of high availability follow from that. The helm-chart/ directory exists in the repository, so Kubernetes users have something to read.
Installing Celery and running a first task
Celery is published on PyPI, which the README lists as the download location. The project's own getting started tutorial, First steps with Celery, is where the README sends new users. Install into a virtual environment with pip:
pip install celeryYou also need a broker. If you are following the tutorial with Redis, that is a separate service you install and start yourself; Celery does not bundle one. The README's simplest application example is a single Python file that constructs an app against an AMQP broker URL:
from celery import Celery

app = Celery('hello', broker='amqp://guest@localhost//')
The README then shows how that app is used to define a task, and the getting started tutorial covers starting a worker against the module that defines your tasks and enqueuing work with the task's delay() method. That is the full loop, and it is genuinely short. The repository carries examples/django/ if you prefer reading code to prose.
Windows is not supported, and the README says so directly
Most projects hedge about platform support. Celery does the opposite. The README states that Celery is a project with minimal funding, that the maintainers do not support Microsoft Windows, that it should be working, and that you should not open issues related to that platform. That is an unusual thing to put in a README, and it is worth taking literally. If your deployment target is Windows, you are outside the support contract the maintainers describe, whatever the code happens to do.
There is a second boundary in the same section: Python version support. Celery 5.6.x runs on Python 3.9 through 3.13, plus PyPy3.9+ (v7.3.12+). The README adds that 5.6 is the last line to support Python 3.9, and that 5.7.x will require 3.10 or newer. It also maps older Pythons to older Celery series, down to Python 2.4. That table is the most concrete maintenance commitment in the README. If you are pinned to Python 3.8, the README tells you to run Celery 5.5 or earlier, which means you are also outside the current release line.
Neither of these is a defect. They are stated limits, and stated limits are easier to plan around than silent ones. The failure mode is adopting Celery on Windows anyway, hitting something odd, and discovering the README already told you not to file it.
Where Celery is the wrong tool
If your entire need is one job that runs at 3am, Celery is a large amount of machinery. You would be running a broker, a worker process, and a supervision layer to replace a cron entry. The repository covers periodic tasks in the examples/periodic-tasks/ directory and the beat scheduler appears in the repository's mypy file list, but nothing in the README argues for Celery over cron at that scale, and it should not.
A second case: work that must complete within the request, or work whose result the user is waiting on synchronously. Celery's value is that it decouples the enqueue from the execution. If you cannot tolerate that decoupling, you are paying for a broker and a worker to get nothing. The README's own framing, that a task queue distributes work across threads or machines, presupposes the work can be deferred.
A third: teams without operational capacity for a broker. Celery delegates delivery guarantees, persistence and failover to RabbitMQ or Redis. The README is explicit that these two are feature complete and that alternatives are experimental. That means the reliability story is largely the broker's story. If nobody on the team wants to run and monitor a broker, Celery's distributed claims do not apply to you, because you will not have the component that makes them true.
How Celery differs from a framework-native queue
The closest alternative for many teams is not another task queue library but the queue that already ships with their web framework or platform. Django has its own background task options, and cloud platforms offer managed queues with a worker runtime attached. The difference in approach is where the abstraction sits. Celery defines tasks as decorated Python functions and lets any broker carry them; a framework-native queue typically binds tasks to that framework's own process model, and a managed queue binds them to the provider's runtime.
That difference cuts both ways. Celery's task abstraction is portable: the README notes clients exist for Node.js, PHP, Go and Rust, and that language interoperability can also be done by enqueuing a URL for a worker to request. A framework-native queue gives you nothing comparable. On the other side, Celery asks you to own the broker and the worker lifecycle, while a managed queue asks you to own neither. Teams that pick Celery usually do so because they want the task definitions in their own codebase and the broker under their own control, and they are prepared to run it.
There is a third option worth naming: a full workflow engine. Celery has primitives for composing tasks, and the repository's examples/ directory includes next-steps and resultgraph material, but the README does not present Celery as a workflow orchestrator. If your problem is a multi-step pipeline with retries and dependencies across services, evaluate a workflow engine before assuming Celery's task graph covers it.
Maintenance, licensing and upgrade cost
The repository is not archived, and the last push was on 2026-11-02. Recent releases are v5.7.0a1 on 2026-09-22, v5.7.0b1 on 2026-10-06, and v5.7.0rc1 on 2026-10-18. The README labels the current version 5.7.0rc1 (Collider), and the description on the repository calls the default branch the development branch. That is a normal shape for a library with a stable line and a development line, and the 5.7 pre-releases across September and October 2026 are visible in the tags.
Upgrade cost is concentrated in the Python version boundary. The README states that 5.6 is the last version supporting Python 3.9 and that 5.7.x will require Python 3.10 or newer. Any team still on 3.9 has a known deadline baked into the project's own documentation, and the README's older-version table gives the fallback line for every Python back to 2.4. That table is the thing to check before upgrading, not the changelog.
On licensing, the repository's LICENSE file is the authoritative source and the GitHub metadata reports NOASSERTION, meaning the licence could not be identified automatically. Read LICENSE directly before distributing Celery inside a product. The README also mentions a Tidelift subscription for commercial support and maintenance, and Open Collective and named sponsors, which tells you the funding model is sponsorship plus paid support rather than a dual-licence scheme. None of that changes your obligations; only the LICENSE file does.
Editorial conclusion
Celery is the right choice if you have Python work that must leave the request path and you are willing to run a broker, usually RabbitMQ or Redis, alongside it. It is the wrong choice if you need Windows support the maintainers stand behind, or if your workload is a single scheduled job that a cron entry would cover. Before adopting, verify the broker transport you plan to use is listed as feature complete rather than experimental, confirm your Python version against the 5.6.x support list, and read the getting started tutorial for the release you install.
Frequently asked questions
How do I install Celery?
Install it from PyPI with pip, for example pip install celery. The README lists https://pypi.org/project/celery/ as the download location and points new users at the First steps with Celery tutorial. You will also need a broker such as RabbitMQ or Redis, which Celery does not include.
How do I install Celery in Django?
The README sends Django users to the getting started tutorials rather than giving inline steps, and the repository ships an examples/django/ directory. The tutorial linked from the README is the documented path.
How do I use Celery?
You construct a Celery app with a broker URL, decorate functions with @app.task, start a worker against the module that defines your tasks, and call the task with .delay() from another process. The README gives a minimal app example using an amqp:// broker URL. The full walkthrough lives in the First steps with Celery tutorial.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/celery-celery)Star history chart for your README
[](https://hysenlabs.com/projects/celery-celery)Was this useful?