coleifer/peewee: a small Python ORM with asyncio and diff-based migrations
a small, expressive orm -- supports postgresql, mysql, sqlite, now with asyncio
At a glance
- What is it?
- Peewee is a single-module ORM for SQLite, MySQL, MariaDB and PostgreSQL, with asyncio support built on the standard async drivers. It suits small teams that want SQL-shaped queries without a large dependency tree.
- Who is it for?
- Adopt Peewee when you want an ORM that fits in one module, exposes SQL directly, and does not pull in a dependency tree: the README states it has no required dependencies and has been running production workloads since 2010. Do not adopt it if you need a large ecosystem of contributed backends or a migration tool that generates a full history of numbered files; the README documents pwmigrate as diff-based generation.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
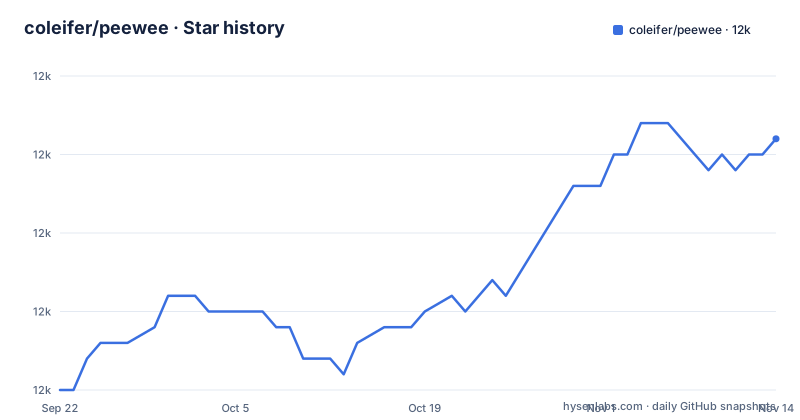
Star history
- coleifer/peewee12,006 ★ · +16
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| coleifer/peewee | 12k | 12k |
16 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Peewee solves, and who it is written for
Peewee targets the gap between writing raw SQL strings and adopting a full ORM framework. The README describes it as "a simple and small ORM" with "few (but expressive) concepts", and states that it is a single module with no required dependencies. That single sentence carries most of the adoption argument: there is no plugin registry, no separate migration package, and no compilation step required for the core library.
The intended audience is visible in the repository layout. The top level holds peewee.py, pwiz.py, a playhouse/ directory of extensions, and an examples/ directory containing a diary app, a blog, a twitter clone, an analytics folder, a FastAPI example and a graph example. Someone building a small service, a CLI tool or a data script would recognize that shape. So would a team that already knows SQL and wants the ORM to stay out of the way: the README promises a "flexible query-builder that exposes full power of SQL", which is a claim about not hiding the database behind an abstraction.
The backends named in the README are sqlite, mysql, mariadb and postgresql. SQLite is the default path because it comes from the standard library sqlite3 module, so a first project needs no extra packages at all.
Models, fields and the query builder's actual mechanism
A Peewee model is a Python class whose fields map to columns, and the database binding lives in an inner Meta class. The README example defines a BaseModel with Meta.database set to a SqliteDatabase instance, then subclasses it for User and Tweet. Tweet.user is a ForeignKeyField(User, backref='tweets'), which creates the reverse accessor, and Tweet.created_date is a DateTimeField with a Python callable as its default.
Query construction is lazy. Expressions are combined with Python operators: User.username == 'charlie' becomes a WHERE clause, and conditions are joined with & and | rather than a separate query DSL. The README shows Tweet.user.in_(users) accepting a subquery, and shows the same result achieved either by in_ or by an explicit .join(User). That equivalence is the point of the design: the query builder does not force one formulation.
Aggregation uses SQL functions exposed as Python callables. The README example builds fn.Count(Tweet.id), aliases it as 'ct', groups by User and orders by the alias descending. Pagination is a method rather than manual LIMIT and OFFSET arithmetic: User.select().order_by(User.username).paginate(3, 20) returns users 41 through 60 according to the README comment.
Atomic updates are expressed as UPDATE statements with expressions on the right-hand side. The README shows Counter.update(count=Counter.count + 1).where(Counter.url == request.url).execute(), with the comment that doing the read and the write in two steps would be prone to race conditions.
Installing Peewee and running a first query
The README's installation section gives one base command and a set of extras. SQLite needs nothing beyond the base install, because it is provided by the standard library sqlite3 module. Other backends are selected through extras defined in pyproject.toml.
pip install peewee

# Backend extras, from the README:
pip install peewee[mysql]      # Install peewee with pymysql.
pip install peewee[postgres]   # Install peewee with psycopg2.
pip install peewee[psycopg3]   # Install peewee with psycopg3.
For asyncio, the README lists separate extras. Each one pairs a driver with greenlet, which is visible in pyproject.toml under the optional-dependencies table.
pip install peewee[aiosqlite]  # Install peewee with aiosqlite.
pip install peewee[aiomysql]   # Install peewee with aiomysql.
pip install peewee[asyncpg]    # Install peewee with asyncpg.
A first real use is to define a model, connect, create the table and insert a row. The README's own example, trimmed to the essentials, looks like this:
from peewee import *
import datetime

db = SqliteDatabase('my_database.db')

class BaseModel(Model):
    class Meta:
        database = db

class User(BaseModel):
    username = CharField(unique=True)

class Tweet(BaseModel):
    user = ForeignKeyField(User, backref='tweets')
    message = TextField()
    created_date = DateTimeField(default=datetime.datetime.now)
    is_published = BooleanField(default=True)

db.connect()
db.create_tables([User, Tweet])
After that, the reader should have a my_database.db file containing two tables, and no rows yet. Inserts use either the classmethod or the constructor plus save. The README shows both forms side by side: User.create(username='charlie') and a User(username='huey') followed by huey.save(). Tweet.create(user=charlie, message='My first tweet') omits created_date and is_published, and the README notes that the defaults specified on the fields are used instead.
Asyncio support and what changes in the async path
Async Peewee is not a separate library. The README imports AsyncPostgresqlDatabase from playhouse.pwasyncio and uses it exactly where a synchronous database object would go. The mechanism is that queries are awaited on the event loop using the underlying driver, which the README names as asyncpg in the example.
Several method names gain an a prefix. acreate_tables replaces create_tables, acreate replaces create, asave replaces save, and aexecute replaces execute. The database object itself is used as an async context manager, and the README closes with await db.close_pool(), which implies a connection pool that outlives an individual request and must be shut down explicitly.
Two result-fetching styles are documented. Awaiting query.aexecute(), or equivalently await db.list(query), buffers all rows in memory and returns them as a list. Iterating with async for tweet in db.iterate(query) streams results through a server-side cursor. That distinction matters for memory on large result sets, and the README presents both without recommending one.
One structural detail worth noting: the async extras each include greenlet alongside the driver. Nothing in the README explains why, but the dependency is declared in pyproject.toml, so an async install is never as thin as the base install.
Migrations, pwiz and the console scripts
Peewee ships two console scripts, declared in pyproject.toml. pwiz maps to pwiz:main and pwmigrate maps to playhouse.migrations:main. The README describes the migration tool as "schema migrations with diff-based generation (pwmigrate)".
Diff-based generation is a different contract from migration frameworks that expect you to write and number each migration file by hand. The README links the migration runner docs for details; rollback and how generated changes are reviewed are the things to resolve there before depending on it in a shared environment.
pwiz is the model generator: it reads an existing database and emits Peewee model classes. The visible README does not cover its flags, but the pwiz.py file and the pyproject entry point are enough to confirm it exists as a first-class tool rather than a side example.
Where Peewee is the wrong choice
The repository is not archived and the most recent release listed is 4.5.3, published on 2026-10-07, with the last push to master on 2026-11-02. The project is maintained. That is separate from fit.
The first mismatch is schema management in a team. If your process requires every schema change to exist as a reviewable, ordered file with a documented down path, the README's description of pwmigrate as diff-based generation does not promise that. A team that needs that guarantee should confirm the behaviour directly rather than infer it.
The second mismatch is typing. A peewee-stubs/ directory exists at the top level and setup.py lists it as a package with package_data {'peewee-stubs': ['*.pyi']}, so stub files ship with the distribution. A typecheck/ directory also exists at the top level. If static typing is a hard requirement, verify the stubs against your checker before adopting.
The third is backend breadth. The README names sqlite, mysql, mariadb and postgresql. A project that needs an embedded analytical engine, an Oracle connection or a document store is outside the stated scope, and no amount of query-builder flexibility changes that.
How it differs from SQLAlchemy and Django ORM
The comparison that matters is architectural, not feature-count. SQLAlchemy separates a Core expression layer from the ORM session layer, and its migration tool, Alembic, produces ordered revision files. Peewee's README presents one module, peewee.py, plus a playhouse/ directory of extensions, and pairs that with diff-based migration generation. The practical difference: SQLAlchemy gives you a larger surface and a more explicit separation of concerns, while Peewee gives you fewer concepts and a shorter path from model to query.
Django ORM is not separable from Django. Peewee has no framework requirement, and the README lists integration pages for Flask, FastAPI and pydantic rather than a single blessed stack. If you are already inside Django, its ORM is the lower-friction choice. If you are writing a FastAPI service or a script, Peewee's examples/ directory includes a FastAPI example and a diary example, which is a reasonable signal of the intended range.
The honest framing is that Peewee trades breadth for a small dependency footprint. The README's claim that it is a single module with no required dependencies is the trade, stated plainly.
Licence, build and upgrade cost
The repository carries an MIT licence, per the LICENSE file at the top level. MIT permits commercial use and modification; it also means no contributor licence agreement or copyleft obligation attaches to your own code. That is a factual property of the licence text, not legal advice, and anyone with specific compliance questions should read LICENSE directly.
The build is mostly plain Python, with one wrinkle. pyproject.toml declares cython>=3 as a build requirement when platform_python_implementation == 'CPython', and setup.py builds a single extension, playhouse._sqlite_udf, from a .pyx or .c source depending on whether Cython is importable. On PyPy, extension_support is set to False. Setting the NO_SQLITE environment variable also disables the extension, which setup.py retains "for backward-compat for not building C extensions". If your environment cannot compile C, that variable is the documented escape hatch.
Upgrade cost is bounded by the version cadence visible in the release list: 4.5.1 on 2026-09-08, 4.5.2 on 2026-09-27, 4.5.3 on 2026-10-07. Three releases in about a month means you should pin a version and read CHANGELOG.md before moving. The changelog is linked from the Repository and Changelog URLs in pyproject.toml.
Editorial conclusion
Adopt Peewee when you want an ORM that fits in one module, exposes SQL directly, and does not pull in a dependency tree: the README states it has no required dependencies and has been running production workloads since 2010. Do not adopt it if you need a large ecosystem of contributed backends or a migration tool that generates a full history of numbered files; the README documents pwmigrate as diff-based generation. Before committing, run python runtests.py against your target backend and confirm your Python version, since pyproject.toml sets requires-python to >=3.8.
Frequently asked questions
How do I install peewee?
The README gives pip install peewee for the base install, which covers SQLite through the standard library sqlite3 module. Other backends use extras such as pip install peewee[postgres] or pip install peewee[mysql], and asyncio uses extras such as peewee[asyncpg].
What is peewee in Python?
Peewee is an ORM described in its README as a simple and small ORM with few but expressive concepts, distributed as a single module with no required dependencies. It supports sqlite, mysql, mariadb and postgresql, and includes asyncio support built on aiosqlite, asyncpg and aiomysql.
Does peewee support asyncio?
Yes. The README documents asyncio support built on the standard async drivers aiosqlite, asyncpg and aiomysql, and shows AsyncPostgresqlDatabase from playhouse.pwasyncio with awaited methods such as acreate, asave and aexecute.
How does peewee handle schema migrations?
The README describes schema migrations with diff-based generation through pwmigrate, which pyproject.toml declares as the console script playhouse.migrations:main. Rollback behaviour should be confirmed in the migration documentation linked from the README.
Which databases does peewee support?
The README names sqlite, mysql, mariadb and postgresql. SQLite is built in via the standard library sqlite3 module, while the other backends are installed through extras such as peewee[mysql], peewee[postgres] and peewee[psycopg3].
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/coleifer-peewee)Star history chart for your README
[](https://hysenlabs.com/projects/coleifer-peewee)Was this useful?