OpenFace: Face Embeddings From a Torch Checkpoint, and Who Should Still Run It
Face recognition with deep neural networks.
At a glance
- What is it?
- OpenFace is a CMU research codebase that turns aligned face crops into embeddings with a Torch neural network, wrapped in a thin Python API. It is a good fit for offline embedding extraction and classifier experiments, and a poor fit for anyone expecting a maintained, dependency-light face recognition service.
- Who is it for?
- Adopt OpenFace if you need to reproduce a published face embedding pipeline or train a custom classifier on top of fixed embeddings, and you accept a Torch dependency and a 2016-era model. Do not adopt it if you need a maintained service, or detection and tracking in the same package.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 15 days ago.
- What is it written in?
- Mainly Lua, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
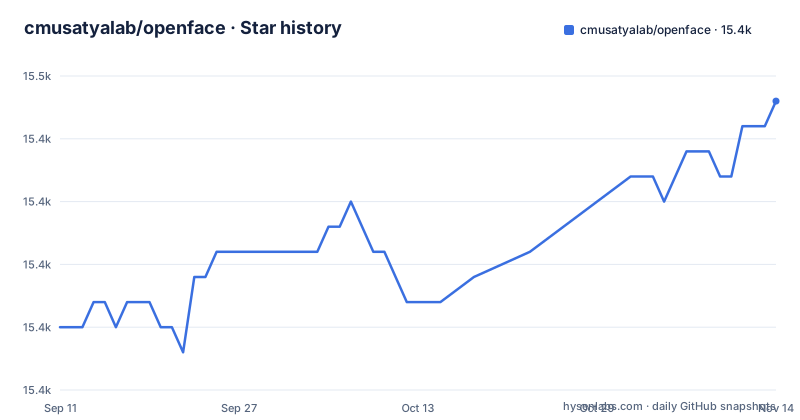
- cmusatyalab/openface15,449 ★ · +9
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| cmusatyalab/openface | 15.4k | 15.4k |
9 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What OpenFace Is Actually For
OpenFace solves one narrow problem: given a photograph that already contains a face, produce a numeric vector such that vectors from the same person sit close together and vectors from different people sit far apart. The README describes it as free and open source face recognition with deep neural networks, and the repository is organized around that single task. The batch-represent directory generates representations from a batch of images. The openface directory holds the Python library code. The training directory holds scripts to train new neural network models, and evaluation holds LFW accuracy evaluation scripts. The third-party 68 face landmark detector from dlib-models appears in the licensing table. The intended user is a researcher or engineer who wants embeddings as a feature extractor and will build the surrounding product themselves.
The Torch Model Behind the Python API
The repository's primary language is Lua, and the README states that the trained Torch and Python model files are copyright Carnegie Mellon University under Apache 2.0. That split explains the repository layout: the neural network itself is written and trained in Torch, the training scripts live under training, and the openface directory holds the Python library code. The demos confirm the same architecture from the user side. demos/compare.py compares two images, demos/classifier.py trains and uses classifiers, demos/classifier_webcam.py applies a trained classifier to a webcam stream, and demos/vis-outputs.lua visualizes the network's outputs directly in Lua. So the practical data flow is: the library produces representations that a downstream classifier consumes. This is the design that makes the project useful as a feature extractor and awkward as an application. Embeddings are cheap to reuse, so batch-represent exists to precompute them once for a whole image set rather than recomputing per training run.
Installation Is a Torch Problem, Not a Python Problem
The README points installation questions at the cmu-openface Google group and the Gitter chat, which is a signal about how the setup tends to go. The dependency chain runs through Torch before Python is involved, and the models directory, which the README describes as the model directory for openface and third party libraries, has a get-models.sh script that the Dockerfile runs to fetch them. The practical sequence implied by the repository is: install Torch, install the Python dependencies for the openface package, then run one of the demos to confirm the model loads. demos/compare.py is the smallest end-to-end check because it needs only two images. demos/classifier.py is the next step, since it covers training and applying a classifier in one script. For a larger corpus, batch-represent is the entry point, and the README links to an example directory structure that the batch script expects, so the input layout is not free-form. The repository does ship a Dockerfile, which starts from nvidia/cuda:11.8.0-cudnn8-devel-ubuntu22.04, runs ./models/get-models.sh and installs requirements.txt and the package, though requirements.txt pins nothing except numpy<2.
Where OpenFace Breaks Down
The most obvious limitation is that the model lineage is old. The releases listed are 0.2.0 from January 2016, 0.2.1 from February 2016, and 0.2.2 tagged lua_final in October 2024. A tag named lua_final suggests the Lua side of the project has been declared finished rather than actively developed, and the README still advertises the 0.2.1 badge. Second, the alignment dependency is real work that the library does not do for you. If your images are not already cropped and landmark-aligned in the way the model expects, embedding quality degrades and the failure is silent: you get a vector, just a bad one. Third, the Torch requirement is a genuine constraint. Environments where Torch cannot be installed, or where only a Python wheel is acceptable, are environments where OpenFace is the wrong tool regardless of its accuracy. Fifth, the README offers no throughput or latency figures, and none should be assumed.
The Alternative: dlib and Modern Embedding Libraries
The clearest contrast is with dlib, which appears in this repository as a requirement in requirements.txt and through the 68 face landmark detector from dlib-models, included under CC0. dlib itself takes the opposite approach. It is a C++ library with Python bindings, it includes its own face detector and landmark predictor, and it produces embeddings without a Torch runtime. The difference in practice is packaging and scope. With dlib you install one library and get detection, alignment, and embedding in the same process. With OpenFace you get a Python wrapper around a Torch model plus a separate landmark model for alignment, and you own the glue. Newer embedding libraries follow the dlib pattern rather than the OpenFace pattern: a single Python package that handles the whole path from image to vector. That matters most for deployment, where a Python-only dependency graph is far easier to containerize than one that requires Torch. The trade-off is that OpenFace's training scripts and evaluation scripts are in the repository, so if you want to retrain the embedding model rather than just consume it, OpenFace gives you a starting point that a pure inference library does not.
Licence: Apache 2.0 With Three Carve-Outs
The README is unusually explicit here. Source code and trained Torch and Python model files are Apache 2.0, copyright Carnegie Mellon University. Three third-party portions are called out in a table: Atcold/torch-TripletEmbedding, unmodified, MIT; facebook/fbnn, modified, BSD; and the dlib-models 68 face landmark detector, unmodified, CC0. The README also states that these portions are noted in the source files. That is a reasonable arrangement for commercial use, since Apache 2.0, MIT, BSD, and CC0 all permit it, but the modified fbnn portion is the one to look at closely if you redistribute the code, because the modification is not described in the README. The research funding note is separate from the licence: NSF grant CNS-1518865 and support from Intel, Google, Vodafone, NVIDIA, and the Conklin Kistler family fund, with the standard disclaimer that findings and conclusions are the authors' own. Funding acknowledgements do not restrict your use of the code. This is a description of what the repository states, not legal advice, and anyone embedding OpenFace in a product should read the LICENSE file and the source file headers directly.
Maintenance Cost and the lua_final Tag
Maintenance is the deciding factor for most teams. The repository is not archived, and the last push is recent, but the release history tells a different story: two releases in early 2016, then a gap until the 0.2.2 lua_final tag in October 2024. If the Lua side is final, then future work is likely to be Python-side fixes and dependency updates rather than model improvements. Upgrading is therefore not a routine activity. There is no migration path described from the 0.2.x models to anything newer, because nothing newer is published. The cost you are accepting is the cost of pinning an old Torch environment and keeping it alive, plus the cost of owning alignment yourself. For a research replication or a fixed internal pipeline where the embeddings are computed once and stored, that cost is bounded and paid up front. For a live service that must absorb operating system upgrades and Python version bumps, the same cost recurs every time the base image moves.
Who Should Download This
OpenFace is worth adopting in three situations. You are reproducing the CMU tech report by Amos, Ludwiczuk, and Satyanarayanan, and you need the same embedding pipeline the paper used. You want to train a classifier on top of fixed embeddings, in which case demos/classifier.py and batch-represent are the two files to read first. Or you need the training scripts under training to experiment with retraining the embedding model itself, which pure inference libraries do not offer. It is the wrong choice if you need a maintained service, if your deployment target cannot run Torch, if you need detection or tracking in the same package, or if you are comparing against current face recognition models on hard imagery. The first thing to verify is not accuracy. It is whether the Torch environment installs cleanly on your target platform and whether the dlib landmark model loads, because those two steps gate everything else. After that, run demos/compare.py on a handful of your own aligned and unaligned images to see how much the alignment step matters for your data before you commit to a batch run.
Editorial conclusion
Adopt OpenFace if you need to reproduce a published face embedding pipeline or train a custom classifier on top of fixed embeddings, and you accept a Torch dependency and a 2016-era model. Do not adopt it if you need a maintained service, or detection and tracking in the same package. Before committing, verify that the Torch install works on your platform, that the dlib 68-landmark model downloads, and that the exact model revision you benchmark is the one you will ship.
Frequently asked questions
What is OpenFace?
A free and open source face recognition library built on deep neural networks, developed at Carnegie Mellon and licensed under Apache 2.0. Its packaging metadata describes it as face recognition with Google's FaceNet deep neural network, and the research was supported by an NSF grant number CNS-1518865 with additional support from Intel, Google, Vodafone and NVIDIA.
How to use OpenFace?
The repository ships a batch-represent tool to generate representations from a batch of images, plus demos for comparing two images, training and using classifiers, applying a trained classifier to a webcam stream, a real-time web demo, and a Lua script for visualising the network's outputs. The library itself is the Python package named openface.
How do I use OpenFace in Python?
Import the openface Python package, which the setup metadata declares as packages=['openface'] with Lua files shipped as package data. The demos folder contains Python scripts for comparing images, training classifiers and applying one to a webcam stream, and the tests directory covers the library code including neural network training.
How do I install OpenFace?
The Docker build is the documented container route: it starts from a CUDA 11.8 development image on Ubuntu 22.04, runs models/get-models.sh to fetch models, then installs requirements.txt and the package itself. For a manual install, requirements.txt lists numpy below 2 plus scipy, pandas, scikit-learn, opencv-python, dlib, torch, torchvision and torchfile.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/cmusatyalab-openface)Star history chart for your README
[](https://hysenlabs.com/projects/cmusatyalab-openface)Was this useful?