Gemini Fullstack LangGraph Quickstart: a working research agent you can read end to end
Get started with building Fullstack Agents using Gemini 2.5 and LangGraph
At a glance
- What is it?
- A React and LangGraph example project that turns a question into iterative Google Search queries, reflects on the gaps, and returns a cited answer. It is a reference implementation, not a product, and the deployment path asks for Redis, Postgres and a LangSmith key.
- Who is it for?
- Adopt it if you want a readable, runnable reference for a reflection loop over Google Search, and you are comfortable reading backend/src/agent/graph.py to change the loop bound yourself. Do not adopt it if you need a supported library, a single-binary deploy, or a system where you cannot supply a Gemini API key and, for the compose path, a LangSmith key.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 153 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
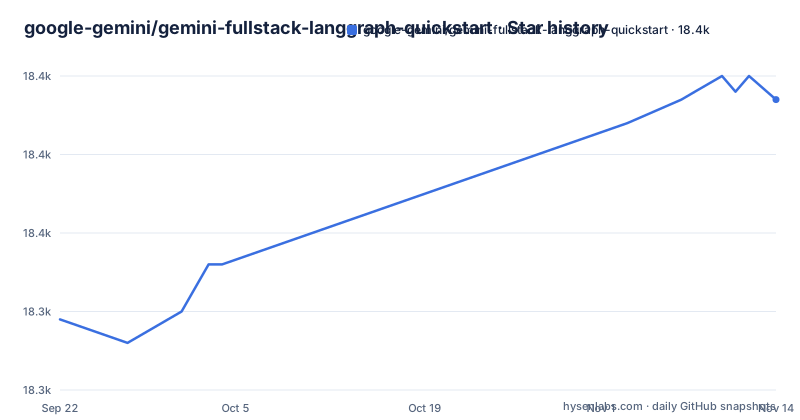
- google-gemini/gemini-fullstack-langgraph-quickstart18,367 ★ · +28
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| google-gemini/gemini-fullstack-langgraph-quickstart | 18.3k | 18.4k |
28 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What the quickstart actually gives you, and who it is written for
This repository is a demonstration, and the README says so in its first line: a fullstack application with a React frontend and a LangGraph-powered backend agent. The agent takes a user query, generates search terms, queries the web through Google Search, reflects on the results to find knowledge gaps, and refines its searches until it can produce an answer with citations.
The audience is narrower than the title suggests. If you already know LangGraph and want to see a full loop wired to a real search tool, the value is the graph itself, sitting in backend/src/agent/graph.py. If you are evaluating whether to put a research agent into production, this repository is a starting point rather than an answer: it ships no releases, the README documents no versioning scheme, and the deployment section points you at the LangGraph documentation rather than describing a supported operating mode.
There is a second audience that gets less out of it. Anyone expecting a drop-in research API will find that the interesting decisions (how many refinement loops, what counts as a knowledge gap, how citations are attached) live in code the README does not reproduce. You are meant to open the file.
The reflection loop: query generation, web research, gap analysis, refinement
The README describes five steps, and the shape of the loop is the point of the project. First, a Gemini model generates a set of initial search queries from your input. Second, for each query the model is used together with the Google Search API to find relevant pages. Third, the agent analyzes those results and decides whether the information is sufficient or whether gaps remain, again with a Gemini model doing the reflection. Fourth, if gaps exist, it generates follow-up queries and repeats the research and reflection steps, up to a configured maximum number of loops. Fifth, once the research is judged sufficient, the agent synthesizes a cited answer.
Two things are worth flagging. The loop bound is described as configured but the README never states the value or the key that sets it, so the only way to know how many refinement passes you are buying per question is to read the graph definition. And the reflection step is itself an LLM call, which means every question costs at least one generation call, one or more search calls, one reflection call, and one synthesis call. The README does not discuss token cost or latency anywhere, and that omission is the largest gap in the documentation for anyone planning to run this at volume.
The architecture is otherwise conventional for LangGraph: a FastAPI application in backend/, a React application in frontend/, and a graph that the LangGraph dev server exposes. The frontend does not contain research logic. It talks to the backend, and the backend owns the loop.
Installing it locally and asking the CLI one real question
The prerequisites are Node.js with npm, Python 3.11 or newer, and a GEMINI_API_KEY. The README tells you to create backend/.env by copying backend/.env.example and then setting the key inside it.
cd backend
cp .env.example .env
# then edit .env: GEMINI_API_KEY="YOUR_ACTUAL_API_KEY"
Install the backend as a Python package and the frontend with npm. Both commands are run from their own directories.
cd backend
pip install .cd frontend
npm installFrom the project root, make dev starts both development servers through the Makefile, which runs the Vite server and langgraph dev concurrently. The README gives http://localhost:5173/app as the frontend URL, and notes that the backend API is available at http://127.0.0.1:2024 when you run langgraph dev on its own.
make devIf you want to skip the browser entirely, the repository includes a CLI script that runs the agent and prints the final answer. This is the fastest way to see whether the reflection loop behaves the way you expect before you touch the frontend.
cd backend
python examples/cli_research.py "What are the latest trends in renewable energy?"
What you should see is a printed final answer with citations drawn from the pages the agent found. The README does not document the script's flags, so treat the question string as the only argument it is known to accept.
Deployment asks for more infrastructure than the quickstart implies
In production the backend server serves the optimized static frontend build, and the README is explicit that LangGraph requires a Redis instance and a Postgres database. Redis acts as a pub-sub broker so background runs can stream output in real time. Postgres stores assistants, threads, runs, thread state, long term memory, and manages the background task queue with exactly-once semantics.
The bundled docker-compose.yml matches that description. It defines a redis:6 container with a redis-cli ping healthcheck, a postgres:16 container exposing 5433 on the host with POSTGRES_DB, POSTGRES_USER and POSTGRES_PASSWORD all set to postgres, and the langgraph-api image mapping container port 8000 to host 8123. The API service waits on both healthchecks before starting and reads GEMINI_API_KEY, LANGSMITH_API_KEY, REDIS_URI and POSTGRES_URI from the environment.
docker build -t gemini-fullstack-langgraph -f Dockerfile .
GEMINI_API_KEY=<your_gemini_api_key> LANGSMITH_API_KEY=<your_langsmith_api_key> docker-compose up
The README notes that the compose example needs a LangSmith API key, which you obtain from LangSmith settings. That is a second external dependency beyond Gemini, and it is the kind of detail that decides whether a team can run this in an air-gapped environment. It cannot, at least not through this path. The README also warns that if you are not using the compose example, or you expose the backend publicly, you should update apiUrl in frontend/src/App.tsx, currently http://localhost:8123 for compose and http://localhost:2024 for development. Forget that edit and the frontend will silently point at the wrong host.
Where this is the wrong tool: cost, loop bounds and provider lock-in
The most concrete limitation is that the research loop is open-ended by design and the README does not publish its ceiling. A question that keeps producing perceived gaps will keep generating queries until the configured maximum is reached, and each pass is a paid model call plus search calls. For a demo this is fine. For a user-facing feature where someone can paste a long ambiguous prompt, it is a cost surface the documentation does not help you reason about.
The second limitation is coupling. Query generation, reflection, and answer synthesis all run through Gemini models, and web research runs through Google Search. Neither is abstracted behind a provider interface in anything the README shows. If your requirement is to run against a self-hosted model or a different search backend, this repository is a reference for the loop shape, not a base you can swap underneath.
The third is operational weight. A quickstart that needs Redis, Postgres, a Gemini key and a LangSmith key before it runs in production is not a small thing to put behind a side project. The docker-compose file is a convenience for local evaluation, and the README itself defers to the LangGraph deployment documentation for anything beyond that.
Finally, this is a sample. The README does not describe a test suite, a compatibility policy, or a migration path between versions, and the repository has no published GitHub releases. Treat upgrades as re-reading the code.
How it differs from building the same agent directly on the Gemini API
The homepage for this project points at the Gemini API's Google Search documentation, and that is the honest alternative: call the Gemini API with the search tool enabled and write your own loop. The difference is not capability, it is where the state lives.
With a direct API integration you manage the conversation and the iteration yourself. You decide what to keep, you decide when to stop, and you deploy a single service with no Redis and no Postgres unless you add them for your own reasons. What you give up is the graph: LangGraph's contribution here is the explicit, inspectable state machine in backend/src/agent/graph.py, plus the dev server and the deployment tooling that come with it. If you want streaming background runs with persisted thread state and exactly-once queue semantics, that is the part you would otherwise have to build.
A second alternative is to read this repository as documentation rather than as a dependency. The README's five-step description of the loop is short enough to reimplement against any model that supports tool calls, and the docker-compose file is a useful reference for what a LangGraph deployment expects. That path avoids inheriting a sample project's structure while keeping its design.
Licence and the cost of keeping up with it
The project is licensed under the Apache License 2.0, with the full text in the LICENSE file at the repository root. Apache-2.0 is a permissive licence that includes an explicit patent grant, which matters if you are vendoring the graph into a commercial product. It also means you carry the notice obligations that come with redistribution. This is a description of the licence text, not legal advice; if the distinction affects your product, have counsel read the LICENSE file rather than this paragraph.
Maintenance is the harder question. The last push to the default branch was on 2026-06-14, which is roughly three months before the date of this article, so the repository is not archived and not stale on that measure. But there are no published GitHub releases, and the README documents no versioning or changelog. The practical upgrade cost is therefore not a version bump. It is the diff between the graph you copied and the graph in the repository, plus whatever LangGraph and Gemini API changes landed underneath it. Budget for reading backend/src/agent/graph.py after any dependency upgrade, because the README will not tell you what moved.
Editorial conclusion
Adopt it if you want a readable, runnable reference for a reflection loop over Google Search, and you are comfortable reading backend/src/agent/graph.py to change the loop bound yourself. Do not adopt it if you need a supported library, a single-binary deploy, or a system where you cannot supply a Gemini API key and, for the compose path, a LangSmith key. Before you build on it, verify three things: the maximum loop count the graph actually enforces, whether the apiUrl in frontend/src/App.tsx points at your host, and whether your deployment can run Redis and Postgres alongside the API container.
Frequently asked questions
Can you provide a quick start guide for LangGraph using this project?
The README's local path is: copy backend/.env.example to backend/.env and set GEMINI_API_KEY, run pip install . in backend/ and npm install in frontend/, then run make dev from the project root. The frontend is served at http://localhost:5173/app, and running langgraph dev directly in backend/ exposes the API at http://127.0.0.1:2024.
Does gemini-fullstack-langgraph-quickstart need a LangSmith API key?
For local development the README only requires a GEMINI_API_KEY. The docker-compose deployment example additionally needs a LANGSMITH_API_KEY, which the README says you can get from LangSmith settings.
What infrastructure does gemini-fullstack-langgraph-quickstart require in production?
The README states that LangGraph requires a Redis instance and a Postgres database. Redis is used as a pub-sub broker for streaming output from background runs, and Postgres stores assistants, threads, runs, thread state, long term memory and the background task queue.
How many search refinement loops does the agent run?
The README says the agent repeats web research and reflection up to a configured maximum number of loops, but it does not state the value or the configuration key. The limit has to be read from backend/src/agent/graph.py.
Which port does gemini-fullstack-langgraph-quickstart serve on?
In development the frontend runs at http://localhost:5173 and the backend API at http://127.0.0.1:2024. Under the docker-compose example the API container port 8000 is mapped to host 8123, and the app is at http://localhost:8123/app/.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/google-gemini-gemini-fullstack-langgraph-quickstart)Star history chart for your README
[](https://hysenlabs.com/projects/google-gemini-gemini-fullstack-langgraph-quickstart)Was this useful?