CocoIndex: An Incremental Sync Engine for Keeping Agent Context Fresh
Incremental engine for long horizon agents 🌟 Star if you like it!
At a glance
- What is it?
- CocoIndex is a Rust-core, Python-declarative framework that reprocesses only the delta in your data sources so AI agents always retrieve current context. This review covers its mechanism, setup, limits, and alternatives.
- Who is it for?
- Adopt CocoIndex if you run long-horizon agents that suffer from stale retrieval context and you can express your pipeline in Python with its declarative API. Skip it if your data sources are static or your team avoids Rust-based infrastructure, since the core is Rust and you must trust its incremental logic.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
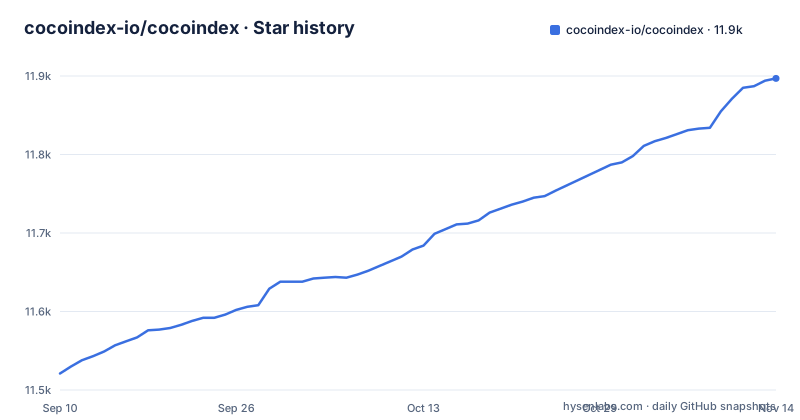
- cocoindex-io/cocoindex11,897 ★ · +376
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| cocoindex-io/cocoindex | 11.5k | 11.9k |
376 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Stale Context Problem for Long-Horizon Agents
Long-horizon agents, ones that reason over many steps or across extended tasks, depend on retrieval context that reflects the current state of their world. If that context comes from batch jobs that run nightly, the agent reasons over yesterday's codebase, last week's Slack threads, or an outdated meeting summary. CocoIndex targets exactly that gap. The README positions it as turning codebases, meeting notes, inboxes, Slack, PDFs, and videos into live, continuously fresh context, and it stresses minimal incremental processing. The intended user is a developer building a production AI agent or LLM application that needs retrieval over enterprise data that changes frequently. This is not a general-purpose ETL tool; it is an ETL shaped specifically for feeding retrieval indexes and agent memory.
Incremental by Design: Only the Delta Is Reprocessed
The core claim is that CocoIndex reprocesses only the delta on every change. That is a meaningful departure from naive pipelines that re-embed or re-index entire corpora on a schedule. In the README example, the per-file function is marked @coco.fn(memo=True) with the comment that it is cached by hash(input) + hash(code), and the README says to run once to backfill and re-run anytime so only the changed files re-embed. The README also lists "parallel by default" as its scale property. For how the delta is computed per connector, check the documentation or the connector implementations.
Declarative Python, Rust Core: The Architecture Split
CocoIndex presents a two-layer architecture. The user-facing API is declarative Python, which the README says can get a production agent ready in 10 minutes with 5 minutes of setup. The engine core is written in Rust, as the primary language field and the rust-core badge indicate. This split is common: Python for ergonomics, Rust for performance and safe concurrency. The declarative nature means you describe what data to ingest and how to transform it, rather than writing imperative loops. The trade-off is that debugging or extending the engine requires Rust knowledge, even though pipeline definition stays in Python. For a team that only writes Python, the Rust core is an opaque dependency.
Getting Started: Commands and Configuration from the README
The README gives the install command pip install -U cocoindex and a short Python example using @coco.fn(memo=True), postgres.mount_table_target and table.declare_vector_index. The PyPI package is cocoindex, and pyproject.toml requires Python 3.11 or newer. The documentation link points to cocoindex.io/docs, which presumably contains the quickstart. The README's tagline claims a 10-minute setup to a production-ready agent, and the declarative Python API is the primary interface. What is clear is that the project ships as a Python package with a Rust core, and the configuration is expressed in Python code, not YAML or JSON. The latest release is v1.1.0 (2026-11-01), after v1.0.26 and v1.0.25 in October. For a concrete setup, you would need to consult the official docs, which are linked from the repository.
Connectors and Targets: What the Material Shows
The README lists source types: codebases, meeting notes, inboxes, Slack, PDFs, and videos. Those are the connectors it advertises. The target side is less explicit, but the README example declares rows and a vector index on a Postgres table target, and the examples folder includes graph and vector store examples such as meeting_notes_graph_neo4j and code_embedding_lancedb. The flagship example, CocoIndex-code, is described as an MCP server for AI coding agents, AST-aware and incremental, giving Claude Code and Cursor instant access to a whole repository. That example shows a specific use case: semantic code index for coding agents. The breadth of source types suggests the project aims at enterprise corpora, but connector coverage and maturity are best confirmed in the documentation. Before adopting, you should verify that the connector for your specific source, such as a particular Slack export format or a video transcript service, exists and is stable.
Limitations and Failure Modes: When It Is the Wrong Tool
The most obvious limitation is that CocoIndex is not for static datasets. If your source changes rarely, the incremental machinery adds complexity without benefit; a simple batch indexer would do. Another failure mode is the dependency on change detection. If the source system does not expose reliable change events, the delta computation may miss updates or require full rescans, defeating the purpose. How each connector detects changes is a point to investigate in the documentation. Also, the project is young, with releases in the 1.x range and a frequent release cadence. As a Rust core, deployment requires a compiled binary or a wheel that supports your platform; if you are on an unusual architecture, you may need to build from source. Finally, if your pipeline involves complex transformations that are not easily expressed declaratively, you might hit a wall. Check the documentation for the full set of transformation primitives.
Alternatives: Batch ETL vs. Event Streaming
The closest alternative is a traditional batch ETL pipeline built with tools like Airflow or dbt, where you schedule periodic re-indexing of your entire corpus. Those tools are mature, have broad connector ecosystems, and are language-agnostic, but they reprocess everything on each run, leading to stale context between runs and wasted compute. Another alternative is a streaming platform like Kafka with a custom consumer that updates an index on each event. That approach offers real-time freshness but requires you to build and maintain the change data capture logic yourself, including handling out-of-order events and exactly-once semantics. CocoIndex sits in between: it provides the incremental logic out of the box but requires you to adopt its Python DSL and Rust runtime. The difference in approach is that CocoIndex abstracts the delta computation, whereas a streaming setup gives you full control but more operational burden. For teams already using Airflow for other data tasks, adding CocoIndex might introduce a second orchestration paradigm.
Maintenance and Upgrade Cost
The repository is active, with the last push on November 2, 2026, and three releases in the past month. That activity cuts both ways: bugs get fixed, but the API may shift between minor versions. The Python package is on PyPI, so dependency management is standard, but the Rust core means each release ships compiled wheels. You will need to track releases and test your pipelines on upgrades. The license is Apache-2.0, which is permissive for commercial use, but you should review the license text for any patent clauses. The repository root contains CONTRIBUTING.md and CODE_OF_CONDUCT.md. Before adopting, check the repository's issue tracker and commit history to gauge how responsive maintainers are to bug reports.
Editorial conclusion
Adopt CocoIndex if you run long-horizon agents that suffer from stale retrieval context and you can express your pipeline in Python with its declarative API. Skip it if your data sources are static or your team avoids Rust-based infrastructure, since the core is Rust and you must trust its incremental logic. Before committing, verify the connector coverage for your exact sources, test the delta reprocessing behavior on a representative workload, and confirm the Apache-2.0 terms fit your distribution plans. The project is actively released, so check the changelog for API stability.
Frequently asked questions
what is cocoindex
CocoIndex is an incremental indexing engine written in Rust and exposed to Python, used to keep derived indexes in sync with sources such as codebases, meeting notes, inboxes, Slack, PDFs and videos. You declare what belongs in the target and the engine recomputes only the delta.
how to use cocoindex
Install it with pip install -U cocoindex, then declare sources and targets in Python using constructs such as mount_table_target, declare_row and declare_vector_index. The first run backfills the index and later runs re-embed only the changed files.
cocoindex-code alternative
The README presents CocoIndex-code as a flagship project built with CocoIndex: an MCP server for AI coding agents, described as AST-aware, incremental and semantic, with Claude Code and Cursor able to see the whole repository. It is a separate project rather than a mode of the pip package, and the README links to cocoindex.io/cocoindex-code for it.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/cocoindex-io-cocoindex)Star history chart for your README
[](https://hysenlabs.com/projects/cocoindex-io-cocoindex)Was this useful?