HelixDB: a graph-vector database that ships its own query DSL
HelixDB is an OLTP graph database with native vector and full-text search built in Rust on Object Storage.
At a glance
- What is it?
- HelixDB combines graph traversal, vector search and full-text search behind one HTTP endpoint, with SDKs in Rust, TypeScript, Python and Go. The interesting part is not the storage claim but the query model: queries are built as an AST in your application language and posted to a running instance with no compile or deploy step.
- Who is it for?
- Adopt HelixDB if you are building retrieval over connected data and want graph traversal and vector search in one process rather than a graph store plus a separate vector index. Do not adopt it if you need a stable wire format you can hand-write, or if your team is unwilling to track four SDKs whose published versions are not aligned.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
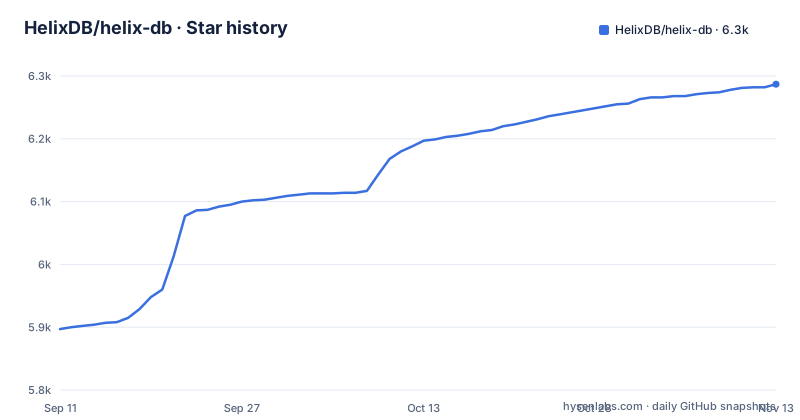
- HelixDB/helix-db6,287 ★ · +390
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| HelixDB/helix-db | 5.9k | 6.3k |
390 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem is retrieval over connected data, not storage
The README opens by describing one transactional engine that stores entities, relationships, embeddings, and text and queries them together. That is the actual pitch. If you are building retrieval over documents that reference each other, the usual shape is a vector index for similarity and a relational or graph store for the relationships, with your application code joining the two result sets. HelixDB's claim is that one engine answers both. The README describes it as a graph database with native vector search and BM25 full-text search, in that order. This is a graph database that grew vector search, not a vector database with a graph bolted on.
Queries are built as an AST in your language and posted as JSON
The mechanism is worth understanding before the install steps, because it shapes everything else. You do not write a query string. In Rust you annotate a function with #[query] and return a WriteBatch or ReadBatch built from a g() traversal object. In TypeScript you call writeBatch(), varAs(), addN(), project(), and the example imports Predicate, PropertyProjection, defineParams, g, param, readBatch and writeBatch. The README states plainly that every SDK produces the same JSON request and that it is sent to a running instance through POST /v2/query with no build or deploy step. So the SDK is a client-side query builder, not an ORM and not a server-side function registry. A consequence the README does not spell out: the server is a query executor over a wire format, and the DSL surface lives in four separate packages. The Rust example uses .value_map(None::<Vec<String>>) while the TypeScript example uses .project([PropertyProjection.new("name")]), which are close but not identical shapes. Reading the two side by side is the fastest way to see how much of the builder API is genuinely shared and how much is per-language ergonomics.
Getting a local instance running: two paths, one of them interactive
Installation is a shell script on macOS and Linux: curl -sSL "https://install.helix-db.com" | bash. Windows uses a PowerShell one-liner that pulls install.ps1 from the main branch of the repository. helix update moves an existing install forward. From there the README offers a fast path and a manual path. The fast path is helix chef, described as an interactive one-shot bootstrapper that installs query skills and a docs MCP, scaffolds a project, starts a local instance, seeds example data, and hands off to the first coding agent it finds, in a fixed order: Claude Code, then OpenAI Codex, then OpenCode, then Cursor Agent. The manual path is in the README itself: mkdir a project, run helix init local (which writes helix.toml and examples/request.json), helix start dev, and helix query dev --file examples/request.json; a local instance requires Docker or Podman, and the full walkthrough is in the docs quickstart. helix start dev serves on http://localhost:6969, and the SDK examples target that address. If you are evaluating HelixDB without an agent installed, helix chef will scaffold and seed but has nothing to hand off to, so plan on the manual quickstart instead.
Four SDKs, four version numbers, and that is the real cost
The README's own table is the most useful part of the document for anyone doing due diligence. Rust is published as helix-db 3.0.0. TypeScript is @helix-db/helix-db 3.1.0 on npm and requires Node.js 20+. Python is helix-db 0.3.4 on PyPI. Go is github.com/helixdb/helix-db/sdks/go at v0.3.1. The latest server release is v3.5.1. Those numbers do not move together; the README notes only that /v2/ is the wire endpoint version and that the current HelixDB and SDK generation is v3. The Rust crate is imported as helix_db while published as helix-db, a small detail that will cost someone ten minutes. The practical reading is that the Rust SDK is the reference implementation and the others trail it. If your stack is Python or Go, the question to answer before you write code is whether the builder catalog in your language matches the one in the Querying Guide, because the README shows install commands and short examples for all four SDKs, with the full setup in each language's setup guide.
Where the model creates friction
The no-build-step design is genuinely convenient for iteration and genuinely awkward for operations. Because queries are constructed in application code and serialized to JSON, the query logic lives in your service, not in the database. That is fine until you want to inspect what was actually executed, pin a query's behaviour across a client upgrade, or reuse the same traversal from a service in a different language. You can read the JSON AST, but you are reading generated output, not source you maintain. A second limitation follows from the version spread: a server upgrade to v3.5.1 alongside a Python SDK pinned at 0.3.4 is a combination whose compatibility you would have to confirm yourself. Third, the project description says the database is built on Object Storage. For an OLTP system, latency characteristics, local caching, and read-path behaviour when the object store is slow or unavailable are the first things to confirm in the documentation.
Compared with assembling a graph store and a vector index
The obvious alternative is running a general graph database for traversal and a dedicated vector index for similarity, then joining results in your application. That approach has a real advantage HelixDB is arguing against: each component is independently replaceable and independently documented, and you can swap the vector index without touching the graph. The cost is the join. You retrieve candidate node ids from the vector index, then re-query the graph for each one, and you own the consistency question when a node is deleted from one store and not the other. HelixDB collapses that into a single query, which is the whole reason someone would accept a younger project. The trade is that you now depend on one engine for both access patterns, and the escape hatch is not a drop-in replacement for either half. If your retrieval workload is pure nearest-neighbour search over flat documents with no relationships, the graph half is dead weight and a dedicated vector index is the simpler choice. HelixDB earns its place when the traversal is load-bearing.
Licence and maintenance posture
HelixDB is Apache-2.0, which permits commercial use, modification and redistribution with the usual attribution and notice requirements. Nothing here is legal advice; if you are embedding it in a product, read the licence text and your own obligations. On maintenance, the repository is not archived, the last push is dated 2026-11-02, and the recent releases are v3.4.4 on 2026-10-07 and v3.5.0 and v3.5.1 on 2026-10-08. That is a project shipping frequently, which cuts both ways: fixes arrive, and so do breaking changes. The jump from v3.4.4 to v3.5.1 within two days, combined with SDK versions that already disagree by major number across languages, suggests you should pin both client and server versions and read the changelog before upgrading either. The README links release notes at docs.helix-db.com/database/helix-db/start-here/release-notes; treat that as required reading, not optional.
Editorial conclusion
Adopt HelixDB if you are building retrieval over connected data and want graph traversal and vector search in one process rather than a graph store plus a separate vector index. Do not adopt it if you need a stable wire format you can hand-write, or if your team is unwilling to track four SDKs whose published versions are not aligned. Before committing, verify two things yourself: whether the Python SDK at 0.3.4 and the Go SDK at v0.3.1 expose the same builder surface as the Rust crate at 3.0.0, and whether your deployment can tolerate the Object Storage dependency implied by the project description.
Frequently asked questions
What is HelixDB?
HelixDB is an open source graph database under the Apache 2.0 license, written in Rust, with native vector search and BM25 full-text search on top of object storage. It keeps entities, relationships, embeddings and text in one transactional engine and is queried from Rust, TypeScript, Go or Python.
What kind of software is HelixDB?
It is server software. A local instance serves queries on http://localhost:6969, the container image is labelled as a single-process database server and runs as user 65532, and the query logic is a set of Rust crates under crates/.
How do I install HelixDB and run a first query?
On macOS and Linux run the piped installer, then create a directory, run `helix init local` to write helix.toml and examples/request.json, run `helix start dev` to serve http://localhost:6969, and send the generated request with `helix query dev --file examples/request.json`. The local instance needs Docker or Podman.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/helixdb-helix-db)Star history chart for your README
[](https://hysenlabs.com/projects/helixdb-helix-db)Was this useful?