Feynman: a Pi-based research agent with ten slash workflows, scholarly search and telemetry on by default
The open source AI research agent.
At a glance
- What is it?
- Companion-Inc/feynman is an MIT-licensed TypeScript command line agent that runs literature reviews, deep research, paper audits and replication plans across arXiv, OpenAlex, PubMed and other sources. It is capable and shipping almost daily, but it needs Node 22.22, leans on your own model keys, and sends usage data to PostHog unless you turn it off.
- Who is it for?
- Feynman suits researchers and ML engineers who want literature reviews, paper audits and replication plans run from a terminal against real scholarly indexes, with provenance files for the workflows that produce them. It is a poor fit for anyone who cannot send usage data to a third party without first changing defaults, or who needs a version that stays put, since releases land almost daily on a 0.5.x line.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
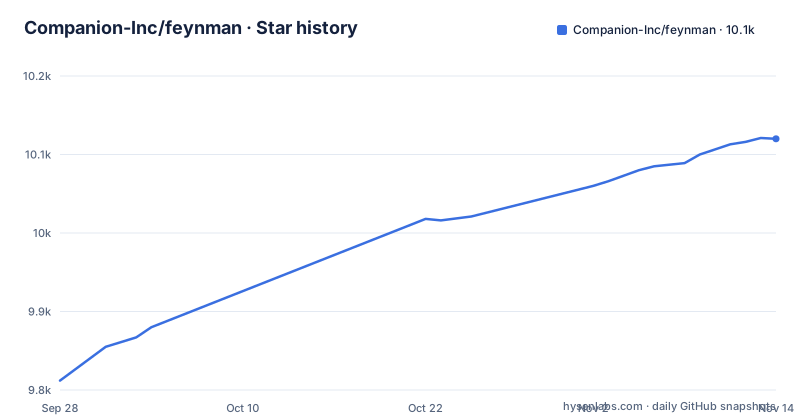
- Companion-Inc/feynman10,120 ★ · +308
| Repository | 2026-09-28 | 2026-11-14 |
|---|---|---|
| Companion-Inc/feynman | 9.8k | 10.1k |
308 Stars in the last 47 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Ten slash workflows run by four Pi agents
Feynman runs on stock Pi with four research agents: researcher, verifier, reviewer and writer. You drive it with a plain question or with named workflows, each of which has a slash form inside the agent:
feynman "what do we know about scaling laws"
feynman lit "RLHF alternatives"
feynman deepresearch "mechanistic interpretability"
The workflows cover distinct jobs. /deepresearch runs a planned investigation with parallel researchers and citation checks. /lit produces a literature review organised around consensus, disagreements and open questions. /review critiques a paper or draft with severity levels and a revision plan. /audit compares a paper's claims with its public code. /recipe returns ranked ML training recipes with datasets and code, /compare builds a source comparison matrix, /draft writes a paper-style draft from findings, and /summarize condenses a paper, repository or PDF. Because these are separate workflows, choose the one matching the output you need; a /lit run and a /deepresearch run on the same topic are not the same job.
The npm route refuses to install below Node 22.22
There are three ways in. On macOS and Linux:
curl -fsSL https://feynman.is/install | bashOn Windows PowerShell:
irm https://feynman.is/install.ps1 | iexOr through npm with `npm install -g @companion-ai/feynman`. Then connect a model provider:
feynman setuppackage.json sets engines to node >=22.22.0 and runs scripts/check-node-version.mjs as a preinstall hook, so the npm route stops on older Node releases instead of installing something that breaks later. Teams standardised on an older LTS line should use the install scripts or upgrade Node first. The installation guide on feynman.is covers pinned versions, uninstalling, and a skills-only bundle for Codex and OpenCode for people who want the research skills inside another agent instead of the Feynman CLI.
Model keys are read by Pi, not by Feynman
Feynman does not ship a model. .env.example states that provider credentials are read by pi-coding-agent in the usual ways, and it lists slots for OPENAI_API_KEY, ANTHROPIC_API_KEY, GEMINI_API_KEY, OPENROUTER_API_KEY, MISTRAL_API_KEY, GROQ_API_KEY, XAI_API_KEY, CEREBRAS_API_KEY, AZURE_OPENAI_API_KEY, HF_TOKEN and several others. Feynman's own knobs are FEYNMAN_MODEL, which is empty by default, and FEYNMAN_THINKING, which defaults to medium. The setup guide covers local models and editors such as Zed.
The consequence is that cost and quality depend on the provider and model you pick, and a research run with parallel researchers spends tokens accordingly. Add your own tools, such as a Zotero library, with `feynman mcp add`; anything you connect this way becomes part of what the agents can read.
Shared rate limits on the scholarly APIs slow keyless runs
Feynman searches alphaXiv, Semantic Scholar, OpenAlex, arXiv, PubMed, Europe PMC, bioRxiv, medRxiv, Crossref, the web and Hugging Face, and reads local PDFs and documents. Without your own keys, it shares rate limits with other users. Free OPENALEX_API_KEY and SEMANTIC_SCHOLAR_API_KEY keys avoid those shared limits, and an OpenAlex key also unlocks usage stats.
PubMed access goes through NCBI E-utilities, where NCBI_API_KEY raises the limit from 3 to 10 requests per second. NCBI_MIN_REQUEST_GAP_MS sets a minimum delay between request starts, 500 ms when anonymous and 125 ms with a key. For a biomedical literature review that touches hundreds of records, those gaps add up, so get the keys before running /lit or /deepresearch on a large topic. PDF text pulled by fetch_content is cached as Markdown in <project>/.feynman/cache/fetch-content unless FEYNMAN_FETCH_CACHE_DIR points elsewhere.
Only three workflows write a provenance file
Results are saved to outputs/, with drafts going to papers/. /lit, /deepresearch and /recipe also write a provenance file listing the sources used and what was verified. That file is the reason to trust a Feynman report over a chat answer, because it lets you check what was actually read.
The other workflows, including /review, /audit, /compare, /draft and /summarize, are not listed as writing one. Treat their output as an argument to check, not a record of verification. In particular, /draft produces a paper-style document from findings; before any text from it leaves your machine, trace each claim back to the provenance file of the research run that fed it, or to the source itself. A verifier agent in the pipeline reduces errors but does not replace reading the cited paper.
Telemetry is on by default and includes error stack traces
Feynman sends anonymous usage data to PostHog: commands, workflows, tools, models, token counts, and errors with their messages and stack traces, with your home folder shown as ~. It never sends prompts, model output, paper content or tool arguments. In .env.example the default is FEYNMAN_TELEMETRY=1, pointing at https://us.i.posthog.com and project 623906. A bundled pi-otel extension also sends gen_ai.* spans to PostHog AI Observability, with PI_OTEL_CAPTURE_CONTENT=metadata_only.
The gap to notice is error messages. Your home directory is masked, but an error message can still carry a file name or a fragment of input. Anyone working on unpublished or sensitive research should set FEYNMAN_TELEMETRY=off before the first run, not after, and confirm it is set in every shell and CI job that calls feynman.
/replicate and /autoresearch act, and releases land almost daily
Two workflows go beyond reading. /replicate builds a replication plan and runs only after you choose an environment, and /autoresearch runs a bounded experiment loop against a benchmark. .env.example carries slots for RUNPOD_API_KEY, MODAL_TOKEN_ID and MODAL_TOKEN_SECRET. Choose the environment deliberately, since compute you connect is compute it can spend.
The project moves fast: v0.5.59, v0.5.60 and v0.5.61 came out on 2026-10-28, 10-29 and 10-30, and the last push was on 2026-10-31. Still on 0.5.x, behaviour can change between releases, so use the pinned-version install for anything you need to reproduce. package.json enforces a release budget of 2,097,152 bytes per tarball, 8,388,608 bytes unpacked and 1,000 files, which keeps the npm package itself small.
Editorial conclusion
Feynman suits researchers and ML engineers who want literature reviews, paper audits and replication plans run from a terminal against real scholarly indexes, with provenance files for the workflows that produce them. It is a poor fit for anyone who cannot send usage data to a third party without first changing defaults, or who needs a version that stays put, since releases land almost daily on a 0.5.x line. Before using it on real work, set FEYNMAN_TELEMETRY=off if required, add free OpenAlex and Semantic Scholar keys, confirm Node 22.22 or newer for the npm route, and check the provenance file rather than trusting a summary on sight.
Frequently asked questions
How do I install Feynman AI?
On macOS or Linux run curl -fsSL https://feynman.is/install | bash; on Windows run irm https://feynman.is/install.ps1 | iex in PowerShell. With Node.js 22.22 or newer you can use npm install -g @companion-ai/feynman, then run feynman setup to sign in to a model provider.
How do I use Feynman AI for research?
Run feynman with a question, or use a workflow such as feynman lit "RLHF alternatives" or feynman deepresearch "mechanistic interpretability". Results go to outputs/, and /lit, /deepresearch and /recipe also write a provenance file.
How do I install Feynman on Windows?
Feynman provides a PowerShell installer: irm https://feynman.is/install.ps1 | iex. After installing, run feynman setup to connect a model provider.
How do I use Feynman without sending telemetry?
Feynman sends anonymous usage data to PostHog by default. Set FEYNMAN_TELEMETRY=off to disable it; prompts, model output, paper content and tool arguments are never sent.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/companion-inc-feynman)Star history chart for your README
[](https://hysenlabs.com/projects/companion-inc-feynman)Was this useful?