Stable Diffusion v1: The Reference Implementation Behind the Text-to-Image Wave
A latent text-to-image diffusion model
At a glance
- What is it?
- CompVis/stable-diffusion is the original research code for the latent text-to-image model. It offers a minimal sampling script and checkpoints, but it is not a polished product.
- Who is it for?
- Adopt this repository if you are a researcher who needs the exact v1 weights, the PLMS sampler, and the original watermarking and safety checker, and you can work with conda and command-line scripts. Do not choose it if you want a maintained API, CPU support, or a production-ready pipeline; the diffusers integration is the better path.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Probably not. The repository last received commits 29 months ago, on June 18, 2024.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
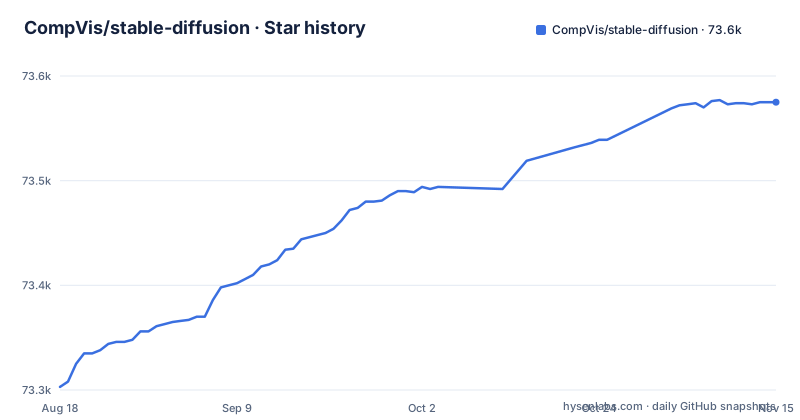
- CompVis/stable-diffusion73,575 ★ · +272
| Repository | 2026-08-18 | 2026-11-15 |
|---|---|---|
| CompVis/stable-diffusion | 73.3k | 73.6k |
272 Stars in the last 89 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What This Repository Actually Is
CompVis/stable-diffusion is the research code release for Stable Diffusion v1, a latent text-to-image diffusion model. It is not a product and not a library. The README lists four checkpoints, sd-v1-1 to sd-v1-4. The README explicitly calls the weights research artifacts and warns against deploying them without additional safety mechanisms. If you are an engineer evaluating this for a service, that warning is the first thing to read. The value here is historical and reference-grade: you see the original training configuration, the sampling script, and the exact model architecture that later tools wrapped in friendlier interfaces.
The Latent Diffusion Mechanism
The core idea is that diffusion happens in a latent space, not in pixel space. A downsampling-factor 8 autoencoder compresses images to a smaller latent representation, and the diffusion model operates on that. The text conditioning comes from a frozen CLIP ViT-L/14 text encoder, using the non-pooled embeddings. The UNet has 860M parameters, and the text encoder adds 123M. The model was pretrained at 256x256 and then finetuned at 512x512. The README describes the model as relatively lightweight, saying it runs on a GPU with at least 10GB VRAM. The mechanism is not novel in isolation, but the combination of a frozen text encoder, a latent autoencoder, and a diffusion UNet is the specific architecture that defined the v1 line. The repository gives you the reference sampling script that ties these pieces together.
Getting It Running: Conda, Checkpoints, and a Symlink
The setup is straightforward but assumes a GPU. You create a conda environment named ldm from environment.yaml, then activate it. The README also gives an update path for an existing latent diffusion environment: conda install pytorch torchvision -c pytorch, then pip install transformers==4.19.2 diffusers invisible-watermark, and finally pip install -e . for the local package. After that, you need to download the weights from Hugging Face and link them into the expected path: mkdir -p models/ldm/stable-diffusion-v1/ and ln -s /path/to/model.ckpt models/ldm/stable-diffusion-v1/model.ckpt (replace the source path with the actual checkpoint path). Then you run python scripts/txt2img.py --prompt "a photograph of an astronaut riding a horse" --plms. The example selects PLMS with --plms; without that flag, the script defaults to DDIM. The default guidance scale is 7.5 and the output size is 512x512 in 50 steps.
The Checkpoint Lineage: What Each Version Changes
The README lists four checkpoints, each with a distinct training history. sd-v1-1 starts with 237k steps at 256x256 on laion2B-en, then 194k steps at 512x512 on laion-high-resolution. sd-v1-2 resumes from v1-1 and adds 515k steps on laion-aesthetics v2 5+, with filtering for original size and watermark probability. sd-v1-3 resumes from v1-2 and adds 195k steps with 10% text-conditioning dropout to improve classifier-free guidance. sd-v1-4 also resumes from v1-2, adding 225k steps with the same dropout. The README includes evaluations with guidance scales from 1.5 to 8.0 and 50 PLMS steps, showing relative improvements. For a practitioner, this lineage matters because the differences are not cosmetic. The v1-3 and v1-4 checkpoints incorporate a training trick that changes sampling behavior. If you are comparing outputs across versions, you need to know which checkpoint produced them.
Built-In Safety and Watermarking, and Their Limits
The reference sampling script includes two protective measures. A Safety Checker Module reduces the probability of explicit outputs, and an invisible watermark is applied to help identify images as machine-generated. These are genuine features, not afterthoughts. However, the safety checker is probabilistic, not a guarantee. The README warns that the model mirrors biases and misconceptions in its training data, and the model card is the place to find the full list of limitations. The watermark is invisible, which means it is not a visible label and may be removable by cropping or compression. For a production service, these built-ins are a starting point, not a complete solution. The README explicitly says the weights are research artifacts and should be treated as such.
The License: OpenRAIL and Its Use-Based Restrictions
The repository license is listed as NOASSERTION, but the README describes it as the CreativeML OpenRAIL M license. This is an Open RAIL M license, adapted from the work of BigScience and the RAIL Initiative. The key point is that it permits commercial use but includes specific use-based restrictions to prevent misuse and harm. The README says the license is otherwise permissive, but it does not list the restrictions. That means you must read the LICENSE file and the model card before using the weights. The license is not a standard MIT or Apache-2.0; it has conditions that may affect how you deploy the model. The README also says the authors do not recommend using the weights for services or products without additional safety mechanisms. This is a legal and ethical boundary that you need to verify for your own use case.
Where This Repository Falls Short
The most obvious limitation is that this is a research codebase, not a maintained library. The README points to a diffusers integration for more active community development. The repository includes a model card, Stable_Diffusion_v1_Model_Card.md. The setup requires conda and a GPU with at least 10GB VRAM, which excludes many practitioners. The repository has no recent releases and no indication of ongoing maintenance. If you encounter a bug, you are on your own. For an engineer who wants to integrate text-to-image into an application, this repository is the wrong starting point. The diffusers integration is the better path, because it offers a stable API and more active development.
The Real Alternative: diffusers Integration
The README explicitly mentions a diffusers integration, which is the same model but accessed through the Hugging Face diffusers library. The difference in approach is significant. In this repository, you clone the code, create a conda environment, download a .ckpt file, and run a script. With diffusers, you install a Python package and load the model with a few lines of code, using a pipeline that handles the text encoder, UNet, and safety checker. The diffusers integration is designed for programmatic use and has a broader community, which means more examples and more frequent updates. The trade-off is that you lose the exact reference implementation and the original training scripts. If your goal is to reproduce the paper's results or study the architecture, this repository is the source of truth. If your goal is to generate images in an application, diffusers is the practical choice.
Editorial conclusion
Adopt this repository if you are a researcher who needs the exact v1 weights, the PLMS sampler, and the original watermarking and safety checker, and you can work with conda and command-line scripts. Do not choose it if you want a maintained API, CPU support, or a production-ready pipeline; the diffusers integration is the better path. Before using the weights, verify the license terms, especially the use-based restrictions, and review the model card for known biases and limitations.
Frequently asked questions
What are stable diffusions?
Stable Diffusion v1 is a latent text-to-image diffusion model built from a downsampling-factor 8 autoencoder with an 860M UNet and a frozen CLIP ViT-L/14 text encoder. It was pretrained on 256x256 images and then finetuned on 512x512, on a subset of the LAION-5B database.
How safe is Stable Diffusion?
The reference sampling script includes a Safety Checker Module to reduce the probability of explicit outputs, and it watermarks outputs so viewers can identify them as machine-generated. The project also states that the weights mirror biases and misconceptions present in their training data, and that they are research artifacts which should be treated as such.
how to install stable diffusion
The README's path is a conda environment created from environment.yaml and named ldm, followed by an editable install of the package. It also gives a separate update route for an existing latent diffusion environment, which pins transformers to 4.19.2 and adds diffusers and invisible-watermark.
how to use stable diffusion locally
Download the checkpoint and place or link it at models/ldm/stable-diffusion-v1/model.ckpt, then run scripts/txt2img.py with a prompt. The reference setup recommends a GPU with at least 10 GB VRAM. The script defaults to DDIM, 50 steps, guidance scale 7.5 and 512×512 output; add --plms to select PLMS.
Can I use Stable Diffusion for free?
The weights are published through the CompVis organization on Hugging Face under the CreativeML OpenRAIL M license, which permits commercial use while carrying use-based restrictions. The project states that the weights are research artifacts and does not recommend using them for services or products without additional safety mechanisms and considerations.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/compvis-stable-diffusion)Star history chart for your README
[](https://hysenlabs.com/projects/compvis-stable-diffusion)Was this useful?