memory-lancedb-pro takes the OpenClaw memory slot, with an AVX floor and a beta tag
Enhanced LanceDB memory plugin for OpenClaw — Hybrid Retrieval (Vector + BM25), Cross-Encoder Rerank, Multi-Scope Isolation, Management CLI
At a glance
- What is it?
- This plugin replaces OpenClaw's memory capability with a LanceDB index over your own markdown files, fuses vector and BM25 retrieval with a cross-encoder rerank, and needs an AVX capable CPU before any of that runs.
- Who is it for?
- Pick memory-lancedb-pro if you want OpenClaw to remember across sessions and you control the host, because the two stores and the citation returning index are the reason to use it, and you need a CPU with AVX plus an OpenAI-compatible endpoint for embeddings. Skip it if your agent runs somewhere you cannot patch and crash on, or if a prerelease dist tag moving under you is a problem, since every install command pulls from the beta tag and the manifest sits at 1.1.0-beta.11.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 8 days ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
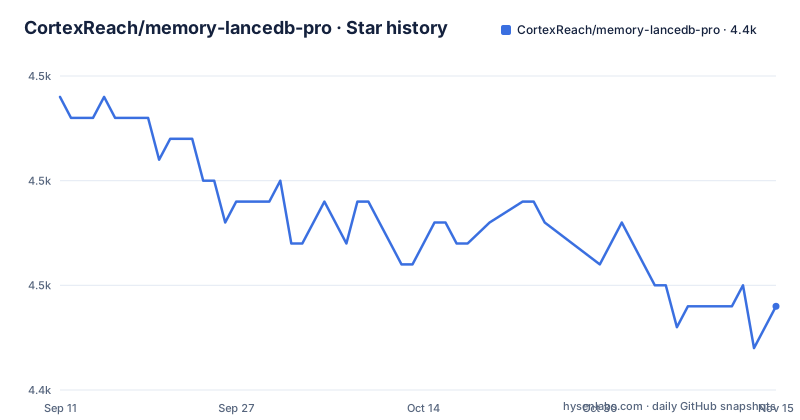
Star history
- CortexReach/memory-lancedb-pro4,449 ★ · -10
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| CortexReach/memory-lancedb-pro | 4.5k | 4.4k |
-10 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The first edit is a slot takeover in openclaw.json
memory-lancedb-pro does not bolt a sidecar feature onto OpenClaw. It claims the memory slot itself, and the first lines you write are the claim and the embedding settings:
{
  "plugins": {
    "slots": { "memory": "memory-lancedb-pro" },
    "entries": {
      "memory-lancedb-pro": {
        "enabled": true,
        "config": {
          "embedding": {
            "provider": "openai-compatible",
            "apiKey": "${OPENAI_API_KEY}",
            "model": "text-embedding-3-small"
          },
          "autoCapture": true,
          "autoRecall": true,
          "smartExtraction": true,
Two lines in there decide your running costs. The embedding block points at an OpenAI-compatible endpoint with the key read from the environment as ${OPENAI_API_KEY}, so both capture and recall depend on that call succeeding. smartExtraction adds model work on top, because extraction is the step that sorts a conversation into six categories: profiles, preferences, entities, events, cases, and patterns. The fragment that follows in the same block turns on the file index:
"canonicalCorpus": {
  "enabled": true,
  "syncOnSearch": true
},
"dreaming": {
  "enabled": false
autoRecall injects the hits before each reply, and the page defends two defaults in prose instead of in the snippet: extractMinMessages: 2 so extraction fires in ordinary two-turn chats, and sessionMemory.enabled: false so session summaries do not pollute retrieval on the first day.
Three ways in, and only one of them needs no follow-up edit
The recommended route is a script that does not live in this repository:
curl -fsSL https://raw.githubusercontent.com/CortexReach/toolbox/main/memory-lancedb-pro-setup/setup-memory.sh -o setup-memory.sh
bash setup-memory.sh
That file sits in the CortexReach/toolbox repository and is described as community maintained, and the page gives no checksum or signature for it, so the first thing your server runs is a shell file fetched over the network at install time. The two manual routes are one line each:
openclaw plugins install memory-lancedb-pro@betanpm i memory-lancedb-pro@betaThe CLI route knows where plugins belong. The npm route leaves a directory on disk that OpenClaw will not look at until you add that install directory to `plugins.load.paths` in `openclaw.json` as an absolute path, and the page calls that the most common setup issue. So the same package gives you a loaded plugin or a silently ignored one depending on which command you ran. Both commands also track the beta dist tag rather than a fixed version.
AVX is a hard floor, and SIGILL is how you discover it
The hardware requirement sits above the install steps, and no setting removes it. Your CPU must support AVX instructions. LanceDB native vector search may require AVX2 on some Linux x64 builds, and on an AVX only machine the process dies with SIGILL instead of falling back. The page gives you a check and two ways out. The check:
grep -o 'avx[^ ]*' /proc/cpuinfo | head -1No output means the instruction set is absent. The escapes are a config key and an environment variable, `retrieval.disableNativeCosine: true` or `MEMORY_LANCEDB_DISABLE_NATIVE_COSINE=1`, and both replace native cosine with a scoped row scan plus cosine ranking done in JavaScript. That moves the work off the native library, and the CPU note gives no latency or recall figure for that path. Issue threads 419 and 644 are cited for the details. A crash that takes the process down rather than logging a warning is worth reproducing on the target host before you schedule this plugin for anything.
The beta line exists because the host renamed its hook
v1.1.0-beta.10 is labelled OpenClaw 2026.3+ Hook Adaptation, and the adaptation is mechanical: the plugin now runs on before_prompt_build hooks, replacing the deprecated before_agent_start. Any host configuration or customisation keyed to the old hook name has to move with it, and the repair is offered as a command rather than a paragraph:
openclaw doctor --fixThe page says to run that after upgrading, which places the cleanup at the moment stale host state would show up. Both CHANGELOG.md and CHANGELOG-v1.1.0.md sit at the repository root, so the migration detail lives outside the landing page and you have to go read it yourself.
Two stores sit behind one memory capability
Once loaded, there are two coordinated stores, and mixing them up is where the surprises live. Plugin memory lives in LanceDB and is what `memory_recall` and auto-recall read. The canonical corpus is your own files: `MEMORY.md`, `memory/**/*.md`, recent session transcripts, and `memory/dreaming/**/*.md`.
| Memory Layer | Storage | What it's for | Recallable? | |---|---|---|---| | Plugin Memory | LanceDB (vector store) | Semantic recall via `memory_recall` / auto-recall | Yes | | Canonical Corpus | `MEMORY.md`, `memory/**/*.md`, recent session transcripts, `memory/dreaming/**/*.md` | Source-of-truth files and public artifacts | Via LanceDB semantic index when `canonicalCorpus.enabled` is true |
The stated principle is that canonical files remain the source of truth and LanceDB is the semantic index used to retrieve them with grounded paths, line spans, snippets, and citations. A recalled answer can therefore point back at a file you can open, which is the practical difference from a bare vector store. The roles are split as follows: `MEMORY.md` is a curated human readable reference, `memory/YYYY-MM-DD.md` is a daily journal that also gets indexed, and `memory/dreaming/**/*.md` holds dream reports exposed as public artifacts and indexed as reflection context.
The manifest is a version ahead of the newest release
The version numbers do not agree, which matters if you pin anything. The manifest in the repository declares 1.1.0-beta.11:
{
  "name": "memory-lancedb-pro",
  "version": "1.1.0-beta.11",
  "type": "module",
  "main": "dist/index.js",
  "author": "win4r",
  "license": "MIT",
  "files": [
    "dist/**/*",
    "openclaw.plugin.json",
The newest published release is v1.1.0-beta.10 from 2026-03-23, followed by v1.1.0-beta.9 from 2026-03-15 and v1.1.0-beta.8 from 2026-03-12, while the last push to the repository is dated 2026-10-21. Every install command pulls the beta dist tag, so what lands on your host is whatever that tag points at on the day you run it. The files array is the other half of the story: the npm package carries `dist/**/*`, the plugin manifest, the READMEs, the changelogs, and `docs/**/*.md` with `skills/**/*.md`, while the git tree additionally holds `src/`, `types/`, `tsconfig.json`, `index.ts`, and `cli.ts`. In short, npm hands you compiled output, so changing behaviour means working from a clone.
The retrieval stack is described, never measured
The README's feature table gives no numbers. Hybrid retrieval is described as vector plus BM25 full text search fused with cross-encoder reranking, multi scope isolation as per agent, per user, per project boundaries, and intelligent forgetting as a Weibull decay model that lets noise fade. The table gives no latency figure, recall rate or comparison against a plain vector store, so you cannot tell from it whether the rerank pays for itself on your corpus. The tooling is promised at the same altitude: a full toolkit of CLI, backup, migration, upgrade, and export or import, with no subcommand named in that table, so look for the CLI surface in `cli.ts` or the `docs/` and `skills/` directories. The test script is the closest thing to an edge map, chaining at least twenty suites, among them embedder error hints, embedder max input chars, a CJK recursion regression, scope access undefined, smart extractor scope filter, recall text cleanup, cli smoke, functional e2e, and per-agent auto-recall. Measure it on your own data, CPU flags first.
Editorial conclusion
Pick memory-lancedb-pro if you want OpenClaw to remember across sessions and you control the host, because the two stores and the citation returning index are the reason to use it, and you need a CPU with AVX plus an OpenAI-compatible endpoint for embeddings. Skip it if your agent runs somewhere you cannot patch and crash on, or if a prerelease dist tag moving under you is a problem, since every install command pulls from the beta tag and the manifest sits at 1.1.0-beta.11. Before deploying, check AVX flags on the target machine, read CHANGELOG.md and CHANGELOG-v1.1.0.md for the hook rename from before_agent_start to before_prompt_build, and confirm that the canonical files you care about sit where the corpus expects them.
Frequently asked questions
Which OpenClaw memory is the best, and where does memory-lancedb-pro fit?
What the plugin does is claim the memory slot in openclaw.json and fuse vector search with BM25 full text search plus a cross-encoder rerank, so the choice turns on whether you want that retrieval stack and can supply a CPU with AVX.
Does memory-lancedb-pro need an OpenAI API key?
The printed configuration uses provider openai-compatible, model text-embedding-3-small, and an apiKey read from the environment as ${OPENAI_API_KEY}. The page also names OpenAI, Jina, Gemini, Ollama, or any OpenAI-compatible API among the providers you can point it at.
What happens to MEMORY.md and my other markdown files?
Canonical files remain the source of truth and LanceDB works as the semantic index over them, returning grounded paths, line spans, snippets, and citations. MEMORY.md is treated as a curated human readable reference, memory/YYYY-MM-DD.md as a daily journal that is also indexed, and memory/dreaming/**/*.md as dream reports indexed as reflection context.
Is memory-lancedb-pro ready for production use?
The page calls it production grade and production ready, yet the manifest declares 1.1.0-beta.11, both install commands pull from the beta dist tag, and the newest published release is v1.1.0-beta.10 from 2026-03-23. The license is MIT, the repository is not archived, and the last push was on 2026-10-21.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/cortexreach-memory-lancedb-pro)Star history chart for your README
[](https://hysenlabs.com/projects/cortexreach-memory-lancedb-pro)Was this useful?