Dinky: a Flink SQL development platform for real-time jobs
Dinky is a real-time data development platform based on Apache Flink, enabling agile data development, deployment and operation.
At a glance
- What is it?
- Dinky is an Apache-2.0 real-time computing platform built around Apache Flink, with a browser-based SQL studio, multi-mode job submission and runtime monitoring. It fits teams already running Flink who want a shared development and operations surface, not teams looking for a lightweight embedded tool.
- Who is it for?
- Adopt Dinky if you already run Flink and want one browser surface for SQL authoring, submission and job operations, and you are willing to compile it from source or follow the installation guide rather than expect a one-line installer. Do not adopt it as a general batch scheduler, and do not expect the README to tell you how to run it: it points to the docs instead.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
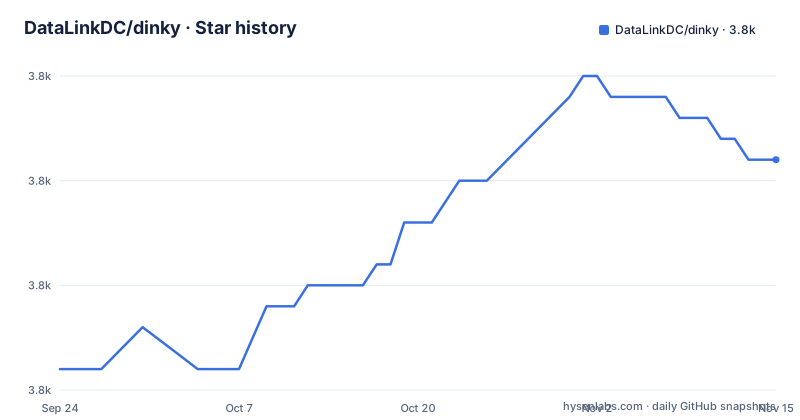
- DataLinkDC/dinky3,776 ★ · +10
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| DataLinkDC/dinky | 3.8k | 3.8k |
10 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Dinky is for, and who ends up using it
Dinky targets the gap between writing Flink SQL in an editor and operating the resulting job on a cluster. The README describes it as "an open-source real-time computing platform built with Apache Flink as its core, capable of real-time application job development, data debugging, and runtime monitoring". The people this is aimed at are data engineers and platform teams who already have Flink clusters and now need a shared place to write, submit and watch jobs.
The feature list is broad on purpose. It covers prompt completion, statement beautification, online debugging, syntax verification, logic plan, catalog, lineage and version comparison in the editor itself, and then job lifecycle concerns on the other side: online and offline, job information, job log, version info, job snapshot, monitor, SQL lineage and alarm records. Multi-tenant, user, role and token management are listed as well, which tells you the intended deployment is a shared internal service rather than a laptop tool.
If your team is one person running a single Flink job, the surface area here is larger than the problem. Dinky pays off when several people submit jobs to the same clusters and someone has to answer questions about which version is running and why it failed.
How Dinky sits between Flink SQL and the cluster
The repository layout is the clearest description of the architecture. dinky-core, dinky-flink, dinky-client and dinky-function handle the Flink-facing layer. dinky-admin and dinky-web are the server and the browser UI. dinky-catalog and dinky-metadata deal with catalog and metadata access, dinky-alert with notifications, dinky-scheduler with scheduling, dinky-gateway with the submission path, and dinky-cdc with FlinkCDC work. dinky-assembly builds the distributable.
The README states that Dinky supports multi-version FlinkSQL development and execution across Local, Standalone, Yarn/Kubernetes Session, Yarn Per-Job and Yarn/Kubernetes Application modes. That is the core mechanism: the platform is not a Flink replacement, it is a front end and control plane that hands work to an existing cluster in whichever mode you configure. The same page lists Flink ecosystem support for Connector, FlinkCEP, FlinkCDC, Paimon and PyFlink.
Dinky also extends Flink SQL syntax rather than only passing it through. The README names database synchronization, execution environments, global variables, table-valued aggregate functions, load dependency, row-level permissions and execute jar as enhancements. Each of these is a Dinky-level construct that has to be understood before the SQL you write in the studio matches what runs on the cluster. Debugging is handled separately through Preview Table, ChangeLog and UDF, which is where you would look first when a statement behaves differently than expected.
Installing Dinky and submitting a first job
The README does not list install commands. It says to see "source code compilation" and "installation and deployment" for details, pointing at docs/docs/deploy_guide/compile_deploy.md and docs/docs/deploy_guide/normal_deploy.mdx in the repository. Those two documents are the authoritative source for the steps below, so treat the commands here as the build entry points the repository provides rather than a complete procedure.
The repository ships Maven wrapper scripts at the top level, build.sh and build.cmd, plus mvnw and mvnw.cmd. On a Unix-like system the shell entry point is:
./build.shOn Windows the equivalent is build.cmd. These drive the Maven build across the modules listed above, including dinky-assembly, which produces the distributable. The exact Java and Maven requirements are stated in compile_deploy.md, not in the README, so check that page before running the build.
Once a build exists, deployment follows normal_deploy.mdx. That document covers the admin service and the web UI; the README does not state a default port, so do not assume one. After the service is up, the workflow the feature list implies is: register a cluster instance and data source under resource management, write a Flink SQL statement in the data studio, verify syntax and inspect the logic plan, then run it through online debugging with Preview Table or ChangeLog before submitting it as a job. Job state, logs, snapshots and metrics then appear under task monitoring, and alarms route through the configured channel.
Configuration keys, ports and environment variables for the deployment are defined in the deployment docs and in the deploy/ directory. This article does not reproduce them because the README does not specify them.
Where Dinky is the wrong choice
Dinky is a Flink platform. The README's acknowledgements and feature list are Flink-centric throughout: FlinkSQL, FlinkCDC, FlinkCEP, Paimon, PyFlink, Flink Catalog. If your real-time work runs on Spark Structured Streaming, Kafka Streams or a managed cloud service, none of this transfers, and you would be adopting a UI whose entire value is tied to a runtime you are not using.
The second limitation is operational weight. Dinky is a multi-module Java application with an admin service, a web front end, its own metadata store, alerting, scheduling and gateway components, and enterprise features such as multi-tenant, user, role and token management. That is a service you run and upgrade, not a library you add. A team that only needs to submit a handful of Flink SQL jobs from CI would find a plain Flink client and a scheduler simpler, and would avoid owning another stateful component.
The third is documentation depth. The README is a feature catalogue with screenshots and links; it does not document rollback, version compatibility matrices or failure recovery for the platform itself. The release notes for v1.2.3, v1.2.4 and v1.2.5 are the place to look for behaviour changes between versions, and the README does not summarise them. Treat the linked docs as required reading rather than optional detail.
Dinky compared with Apache DolphinScheduler
DolphinScheduler appears in Dinky's own acknowledgements, and the two are often considered together, but they solve different problems. DolphinScheduler is a workflow scheduler: it orchestrates tasks across many engines and systems, with dependencies, retries and calendars as the primary abstraction. Dinky's scheduler module exists, but the README frames the product around FlinkSQL development, debugging and job operations, with the cluster submission modes as the central mechanism.
The practical difference is where the SQL lives. In Dinky, you author Flink SQL in the studio, get completion, syntax verification and a logic plan, debug with Preview Table and ChangeLog, then submit and monitor the job, all inside one application that understands Flink catalogs and connectors. With a general scheduler, the SQL is a string handed to a Flink client, and the tool has no opinion about the statement itself.
That also means Dinky is narrower. A DolphinScheduler deployment can run Dinky jobs as one task type among many; Dinky on its own does not try to be the orchestrator for your whole data platform. Teams that already standardised on a scheduler should check whether they want Dinky as a Flink-specific authoring and operations layer underneath it, rather than as a replacement.
Maintenance, licensing and upgrade cost
The repository is not archived, and the last push was on 2026-08-25, which is recent enough that the project is still receiving changes. Releases are less frequent: v1.2.5 on 2025-11-05, v1.2.4 on 2025-07-29 and v1.2.3 on 2025-03-30. The README states that the dev branch is Dinky 1.3.0 and the 1.2 branch is Dinky 1.2.5, so the development line and the released line are separate and you should decide which one you track before you deploy anything.
Upgrade cost is driven by that split. Moving between 1.2.x releases means reading the corresponding release notes; moving to 1.3.0 means following a branch that the README describes as the dev branch rather than a tagged release. Because Dinky supports several Flink versions and several submission modes, the compatibility question is not only Dinky's version but the Flink version and mode you run, and the README does not publish a compatibility matrix.
Dinky is licensed under Apache-2.0, and the README points to the LICENSE file for the terms. That is a permissive licence with the usual patent grant and attribution conditions. Whether those conditions fit a specific commercial distribution is a question for your own counsel; nothing here should be read as legal advice.
Editorial conclusion
Adopt Dinky if you already run Flink and want one browser surface for SQL authoring, submission and job operations, and you are willing to compile it from source or follow the installation guide rather than expect a one-line installer. Do not adopt it as a general batch scheduler, and do not expect the README to tell you how to run it: it points to the docs instead. Before committing, check the Flink version you run against the documented multi-version execution modes, confirm which of the supported submission modes (Local, Standalone, Yarn/Kubernetes Session, Yarn Per-Job, Yarn/Kubernetes Application) matches your cluster, and read the deployment docs at docs/docs/deploy_guide/normal_deploy.mdx to see what the install actually requires.
Frequently asked questions
Does Dinky replace Apache Flink?
No. Dinky is described as a real-time computing platform built with Apache Flink as its core, and it submits jobs to Flink clusters in Local, Standalone, Yarn/Kubernetes Session, Yarn Per-Job or Yarn/Kubernetes Application mode. You still need a Flink runtime.
How do I install Dinky?
The README does not give install commands. It points to the source code compilation document at docs/docs/deploy_guide/compile_deploy.md and the installation and deployment document at docs/docs/deploy_guide/normal_deploy.mdx, and the repository provides build.sh, build.cmd, mvnw and mvnw.cmd as build entry points.
Which Flink versions and execution modes does Dinky support?
The README states that Dinky supports multi-version FlinkSQL development and execution across Local, Standalone, Yarn/Kubernetes Session, Yarn Per-Job and Yarn/Kubernetes Application modes. It does not publish a version compatibility matrix, so the linked deployment documentation is the place to confirm your specific combination.
What is Dinky licensed under?
Dinky is licensed under Apache-2.0, and the README refers readers to the LICENSE file in the repository for the terms.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/datalinkdc-dinky)Star history chart for your README
[](https://hysenlabs.com/projects/datalinkdc-dinky)Was this useful?