fun-rec: a Chinese-language recommender systems textbook that runs from item CF to OneRec
An introductory tutorial on recommender systems; read online at https://datawhalechina.github.io/fun-rec/.
At a glance
- What is it?
- Datawhale's fun-rec (the wheat book) is an open, still-in-development curriculum that walks from cascaded recall and ranking through generative recommendation architectures. The material is a book, not a library, and it says so: no pull requests are being accepted while chapters are still moving.
- Who is it for?
- Adopt fun-rec if you read Chinese and want a single structured path from item-based collaborative filtering to HSTU and OneRec, with a production-system chapter at the end. Do not adopt it if you need an importable Python package, English-only material, or a stable API to build on: the README states the project is under active development, updates are frequent, and pull requests are not being accepted.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 141 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
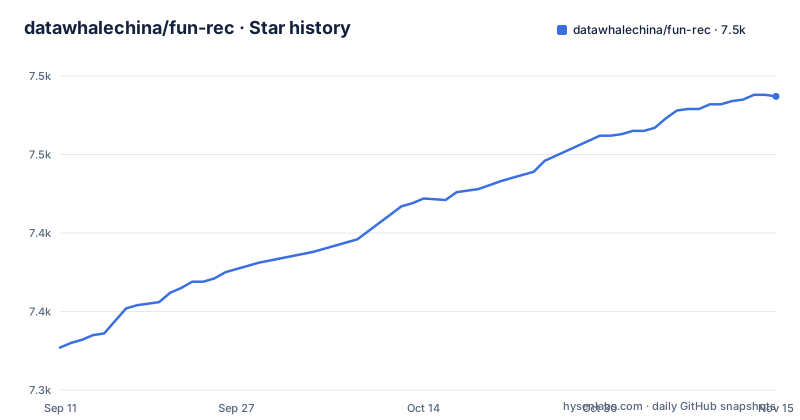
- datawhalechina/fun-rec7,487 ★ · +160
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| datawhalechina/fun-rec | 7.3k | 7.5k |
160 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The gap fun-rec is trying to fill: a Chinese-language path from recall to generative recommendation
Most recommender systems material available in Chinese is either a translated survey paper or a competition write-up that assumes you already know the pipeline. fun-rec (subtitled 深度推荐算法实践, the wheat book) is positioned as the missing middle: a systematic textbook that starts at collaborative filtering and ends at Scaling Law architectures and diffusion-based recommendation. The README frames the scope as 从级联架构到生成式范式, the evolution from cascaded architectures to the generative paradigm, and splits the book into two halves accordingly.
The intended reader is stated plainly: someone with a machine learning foundation who wants to master both the core principles and the engineering practice of recommendation algorithms. That is a narrower audience than a general Python tutorial. If you have never trained a model or read a paper on matrix factorization, chapter 2 will move faster than you can follow. If you have shipped a ranking model and want to understand why HSTU exists, the second half is the part that is hard to find elsewhere in Chinese.
What the two halves actually contain, chapter by chapter
The first half, 上篇:级联架构, is the classical pipeline. Chapter 1 is an overview. Chapter 2 covers candidate recall in three families: collaborative filtering (item CF, user CF, matrix factorization), vector recall (I2I and U2I), and sequence recall (user interest representation, full-interest modeling with streaming indexes). Chapter 3 is preference prediction: memorization versus generalization, second-order and higher-order feature crossing, sequence modeling with local activation attention and interest evolution, multi-objective modeling, and multi-scenario modeling with multi-tower structures and dynamic weighting. Chapter 4 is re-ranking for diversity: greedy methods (maximal marginal relevance, determinantal point processes) and personalized re-ranking (Transformer-based and permutation-based models).
The second half, 下篇:生成式范式, is where the book departs from most tutorials. Chapter 5 covers generative foundations: the shift from discriminative to generative modeling, Transformer and Diffusion as architectural bases, the three-stage LLM pipeline, and tokenization for recommendation including end-to-end discretization and industrial schemes. Chapter 6 is Scaling Law exploration through HSTU and hardware-aware unified architectures. Chapter 7 is end-to-end generative modeling: OneRec V1 and V2, OneSug query completion, OneSearch item retrieval, EGA unified bidding, GPR pretraining for ad generation. Chapter 8 is reasoning models: PLUM, OneRec-Think, RecZero and RecOne. Chapter 9 is diffusion: DiffuASR, Diff-MSR, AsymDiffRec, DMSG. Chapter 10 is a production system build covering offline pipeline, online flow, front end and deployment.
The mechanism is a book plus a code repository, not an installable package
The README describes the project as a book (本书) with an online reading address at datawhalechina.github.io/fun-rec, and the repository is organized around chapters rather than around a single importable module. The repository's pyproject.toml defines a funrec package under src/ and pins tensorflow==2.13.0, and requirements.txt adds seaborn, faiss-cpu and lightgbm for news recommendation, but the README does not document an entry point. The README does not give the exact run command for any chapter, or say whether each chapter ships runnable code at all.
That matters for how you use it. Treat fun-rec as a reading-first resource where code is illustrative and tied to a specific chapter's narrative, not as a framework you wire into a service. The production chapter (chapter 10) is described as covering system architecture, offline pipeline, online flow, front end and deployment, which reads like a walkthrough of a reference design rather than a deployable artifact. The README gives no installation instructions; the only configuration hint is .env.example, which sets FUNREC_RAW_DATA_PATH and FUNREC_PROCESSED_DATA_PATH.
The constraint the README states up front: no pull requests while the book is in flux
The most operationally important line in the README is a blockquote: the project is still under development, code and content update frequently, and pull requests are not currently accepted. Feedback goes through GitHub Issues instead. For a reader this is fine. For anyone planning to fork and extend it, or to build a course on top of a frozen snapshot, it is a real constraint: the ground under chapter 5 through 9 is explicitly moving.
The repository metadata supports that reading. The last push recorded is 2026-06-27, and the repository has no published GitHub releases. There is no versioned tag to pin against. If you cite a chapter in internal training material, cite it with a commit hash rather than a URL, because the online book at datawhalechina.github.io/fun-rec will change. The README also notes that the WeChat group QR code expires after seven days and directs readers to add a contact with the note Fun-Rec, which tells you the community channel is chat-based rather than a forum with searchable threads. The knowledge planet (知识星球) is described as the place where content is archived, and there are older videos on Bilibili linked from the README.
Licence: CC BY-NC-SA 4.0, which rules out commercial reuse
The README ends with a Creative Commons licence badge and a link: CC BY-NC-SA 4.0, attribution, non-commercial, share-alike. The licence is stated explicitly in the README and in pyproject.toml, while GitHub's licence field is unknown.
The practical consequences, stated as facts rather than legal advice: the NonCommercial clause means you cannot fold the text into a paid course or a commercial product without separate permission. The ShareAlike clause means derivatives must carry the same licence. Attribution is required. If you are an engineer reading this on your own time to learn, none of that interferes. If you are a company considering adapting chapters into internal onboarding material, the NC clause is the one to have a lawyer look at, because internal corporate training sits in a grey area that this review cannot resolve. I am not giving legal advice, and the README does not address corporate use.
Where fun-rec is the wrong tool
Three cases stand out. First, if you need a working recommender this week, fun-rec will not give it to you. The README documents no install path and does not promise a runnable baseline. A library such as Microsoft's recommenders package or a framework like RecBole is designed for that job: you install it, configure a model by name, and train on your own data. fun-rec is the opposite shape, a narrative that explains why the models exist.
Second, if you do not read Chinese, the value collapses. The README links to a README_en.md, but the chapter list and the book itself are presented in Chinese, and the README does not state that an English edition of the full text exists.
Third, if you want stable, citable, versioned reference material, the no-PR, in-development status is a poor fit. A published textbook with an ISBN has a fixed edition. fun-rec has a master branch and a moving online book. That is a reasonable trade for currency in a fast-moving subfield like generative recommendation, and a bad trade for a syllabus that must not change mid-semester.
How it compares to RecBole in approach
RecBole is the obvious reference point because it occupies the same subject area with the opposite delivery model. RecBole is a Python library: you install it, select a model from a registry of implemented algorithms, point it at a dataset in a supported format, and run training and evaluation through a configuration file. Its output is metrics and checkpoints. fun-rec's output is understanding: prose that explains item CF, local activation attention and interest evolution modeling, and OneRec-V2.
The difference in maintenance shape follows from that. A library carries an API compatibility burden and must keep its model implementations correct against a test suite. A book carries a correctness burden on its explanations and a currency burden on its coverage. fun-rec's decision to stop accepting PRs while chapters are in flux is a book-shaped decision: it avoids merge conflicts across chapters that reference each other. RecBole could not make the same call without freezing its API. Neither approach is better in the abstract. If you are choosing, the question is whether you need to run something or understand something, and fun-rec answers only the second.
Maintenance cost and what to verify before you invest time
The cost of following fun-rec is reading time plus the risk of churn. The README states that code and content update frequently, so a chapter you read in March may be rewritten by June. The repository has no published GitHub releases, and the README describes no changelog, release notes or versioned snapshot, so you cannot diff what changed between two readings except by watching the repository. The community channels are a WeChat group and a knowledge planet, both of which are chat-shaped and not indexed by search engines, which makes it harder to check whether a question has already been answered.
Before committing, verify three things against the live repository rather than this description. Open the online book and check that the ten chapters listed in the README are actually present and not stubs. Look at whether the code directories contain runnable scripts or only notebooks, since the README does not say. And note that there is no LICENSE file at the repository root: GitHub lists the licence as unknown, while the README and pyproject.toml state CC BY-NC-SA 4.0. If the code directories turn out to be sparse, fun-rec is still worth reading as a survey of the generative recommendation literature in Chinese, but it is not a practice environment.
Editorial conclusion
Adopt fun-rec if you read Chinese and want a single structured path from item-based collaborative filtering to HSTU and OneRec, with a production-system chapter at the end. Do not adopt it if you need an importable Python package, English-only material, or a stable API to build on: the README states the project is under active development, updates are frequent, and pull requests are not being accepted. Before committing study time, open the online book at datawhalechina.github.io/fun-rec, check the chapter list against the README, and confirm that the code directories under the repository match the chapters you care about, because the README itself carries no installation or run instructions.
Frequently asked questions
What is fun-rec?
A recommender systems textbook published by a community learning group, split into two halves. The first covers the cascade pipeline from collaborative filtering and matrix factorization through feature crossing, multi-objective and multi-scenario modelling to re-ranking for diversity. The second covers generative recommendation, from large model foundations and scaling law architectures through end-to-end generative modelling, reasoning recommenders and diffusion models, closing with a production system build. An online reading edition is published alongside the repository.
How do I run the fun-rec code?
The manifest describes a package whose source lives under a src directory, with configuration files in YAML and Python shipped as package data, and the project expects two data paths supplied through environment variables with an example file provided. The pinned dependencies include a specific TensorFlow release, gensim and networkx. Note that the requirements file lists three further packages beyond the manifest, marked as needed for news recommendation, so the two files do not describe the same set.
Can I contribute to fun-rec?
Not with a pull request at the moment. The project states that it is still in development, that code and content change frequently, and that pull requests are not being accepted, and asks for suggestions and questions through the issue tracker instead. Two core contributors are credited by name alongside a long list of people who helped earlier in the project's life, and the surrounding community runs a chat group and a knowledge space.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/datawhalechina-fun-rec)Star history chart for your README
[](https://hysenlabs.com/projects/datawhalechina-fun-rec)Was this useful?