ScrapeGraphAI turns a prompt and a URL into a LangChain graph
Python scraper based on AI
At a glance
- What is it?
- A Python library that describes a scrape as a graph instead of a script, on top of LangChain, Playwright and a language model you choose. The README lists six pipeline classes covering single page, multi page, search, script generation and audio, and says each graph also has a multi version that makes LLM calls in parallel.
- Who is it for?
- ScrapeGraphAI suits a team that would rather describe the fields it wants than hand-write selectors, and it does not suit a pipeline where the extraction rules have to be reproducible to the character, because the extraction is done by an LLM. Before adopting it, confirm your Python is 3.12 or newer, since pyproject.toml requires `>=3.12,<4.0` while the Dockerfile still builds on 3.11, and decide which model pays for the run.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 38 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
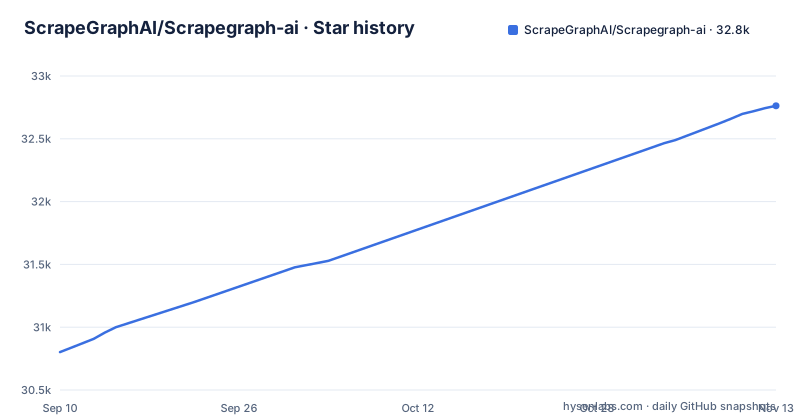
- ScrapeGraphAI/Scrapegraph-ai32,763 ★ · +1,961
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| ScrapeGraphAI/Scrapegraph-ai | 30.8k | 32.8k |
1,961 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
You describe the fields, LangChain decides the steps
ScrapeGraphAI does not give you a selector API. You hand it a prompt and a source, and it builds the extraction pipeline. Its own metadata describes it as a web scraping library based on LangChain which uses LLM and direct graph logic to create scraping pipelines.
The graph is the point. In a hand-written scraper you own the sequence: fetch, parse, select, normalise, retry. Here the prompt is the interface instead of the code.
The input is not limited to web pages. The library handles websites and local documents, with XML, HTML, JSON and Markdown named as the formats it reads. That is the difference between this and a browser automation tool: the source can be a file you already have on disk, and the output shape is decided by the same prompt.
The licence is MIT and the package installs from PyPI under the name `scrapegraphai`.
Six graph classes, and every one has a Multi twin
The pipeline classes are the API surface. The README table lists six of them, and the examples directory shows further graphs such as csv_scraper_graph, json_scraper_graph, xml_scraper_graph, document_scraper_graph, depth_search_graph and omni_scraper_graph.
`SmartScraperGraph` is the common case, extracting from a single page given a user prompt and a source URL. `SearchGraph` works across the top n results of a search engine. `SpeechGraph` scrapes one page and generates an audio file from what it found, and `ScriptCreatorGraph` scrapes one page and generates a Python script instead of returning data. `SmartScraperMultiGraph` takes a single prompt with a list of sources, and `ScriptCreatorMultiGraph` is the multi-page version that writes the script.
The README says each of these graphs also has a multi version, and the documented difference is parallel model calls. `SmartScraperMultiGraph` against a list of sources is the one you will reach for first, since the serial version of the same job is the obvious waste.
pip install scrapegraphai, then a separate playwright install
Installation is two commands, and the second one is not optional:
pip install scrapegraphai

# IMPORTANT (for fetching websites content)
playwright install
The browser binaries Playwright drives are not pulled in by pip, so without that second step the graph builds fine and then fails when it tries to open a page. The project recommends installing into a virtual environment to avoid conflicts with other libraries, which is the ordinary advice for a package that depends on LangChain, Playwright and Beautiful Soup at once.
The smallest useful program is a config dictionary and one graph:
from scrapegraphai.graphs import SmartScraperGraph

graph_config = {
    "llm": {
        "model": "ollama/llama3.2",
        "model_tokens": 8192,
        "format": "json",
    },
    "verbose": True,
    "headless": False,
}
The prompt and the source go into the constructor, and the pipeline runs from there. The result is a plain Python dictionary keyed by whatever you asked for, so nothing about the return type depends on the model you picked. That matters more than it sounds: a hosted model and a local Ollama model can be swapped behind the same prompt without the calling code changing at all.
The model is a config string, not an import
Swapping which model does the work means editing one dictionary, not rewriting the pipeline. For a hosted model you set `api_key` alongside `model`, for example `openai/gpt-4o-mini`; for a local one you set `model` to `ollama/llama3.2` with `model_tokens` and `format`.
The documented providers are OpenAI, Groq, Azure, Gemini and MiniMax, plus local models through Ollama. Using Ollama means installing it and pulling the model weights yourself with the `ollama pull` command before the library can reach it.
Three config keys deserve attention. `model_tokens` is set to 8192 and `format` to `json` in the README's Ollama example. `headless` decides whether a browser window appears, which is the setting to flip when you need to watch what the graph is actually visiting.
Dependencies follow the same pattern: separate `langchain-openai`, `langchain-mistralai`, `langchain-aws` and `langchain-ollama` packages are all listed, and all of them are in the main dependency list, so they install together with the library.
Playwright, undetected-playwright and a proxy helper do the fetching
The dependency list is longer than a scraper usually needs, and each entry hints at a failure mode. `playwright>=1.57.0` and `undetected-playwright>=0.3.0` sit side by side, so there is a plain browser driver and a second one aimed at sites that notice automation. `free-proxy` is bundled, presumably for routing requests through proxies.
Around those sit the pieces a pipeline needs to survive real pages: `tiktoken` for counting tokens against the context window, `minify-html` for shrinking markup before the model sees it, `semchunk` for splitting long documents, `beautifulsoup4` and `html2text` for turning a page into something a model can read, `tqdm` for progress, and `jsonschema` with `pydantic` for validating what comes back. `async-timeout` and `simpleeval` are also listed.
`ddgs>=9.0.0` is there for `SearchGraph`, and `scrapegraph-py>=2.0.0` means the client for the hosted API is a dependency of the library you run yourself.
The Dockerfile builds on 3.11 while pyproject demands 3.12
The container recipe starts from `python:3.11-slim`, `pip install --no-cache-dir scrapegraphai`, install the same package again with the `[burr]` extra, then `playwright install-deps` followed by `playwright install`.
One thing in there will bite. The base image is Python 3.11 while the project metadata sets `requires-python = ">=3.12,<4.0"`, so the image and the manifest disagree.
The compose file is a different matter and is plainly for local models rather than for the library. It runs the `ollama/ollama` image, publishes port 11434, and keeps the model store in a named volume mounted at `/root/.ollama`, with `restart: unless-stopped`. That is the pairing to copy if you want `ollama/llama3.2` in the config dictionary above to resolve.
So the container story is: compose for Ollama, Dockerfile for the library, and check the Python version yourself.
uv, ruff, black, isort and mypy behind one make target
Development runs through `uv` rather than pip. The Makefile's `install` target runs `uv sync` and installs the pre-commit hooks, and the repository carries a `uv.lock`, so the dependency graph is pinned for anyone working on the code.
The default target chains the three checks: `lint` runs `ruff check`, `black --check` and `isort --check-only`, `type-check` runs `mypy`, and `test` runs `pytest` with coverage reported to XML.
The rest of the tree documents itself. `examples/` holds one directory per pipeline class, including `csv_scraper_graph`, `document_scraper_graph`, `json_scraper_graph`, `xml_scraper_graph`, `markdownify` and `omni_scraper_graph`, plus a `ScrapegraphAI_cookbook.ipynb`. `docs/` carries the README in ten languages. `SEMANTIC_COMMITS.md` and `.releaserc.yml` sit next to `CHANGELOG.md`, which is how the release tags are cut.
MIT for the library, a hosted API beside it
There are two products under one name, and the distinction is about who runs the browser. The open-source library is the one you install from PyPI and run yourself, which means the fetching, the model calls and the failures are all on your side of the wall. The managed cloud API is reached through separate Python and JavaScript SDKs and is a different thing with its own terms.
For the library itself, `pyproject.toml` names Marco Vinciguerra and Lorenzo Padoan as authors and the repository is MIT licensed, with a `LICENSE` at the root.
The latest release is v2.3.1, published 2026-10-06, after v2.3.0 and v2.3.0-beta.1 on 2026-09-25; the last push to the repository is dated 2026-09-25.
Editorial conclusion
ScrapeGraphAI suits a team that would rather describe the fields it wants than hand-write selectors, and it does not suit a pipeline where the extraction rules have to be reproducible to the character, because the extraction is done by an LLM. Before adopting it, confirm your Python is 3.12 or newer, since pyproject.toml requires `>=3.12,<4.0` while the Dockerfile still builds on 3.11, and decide which model pays for the run.
Frequently asked questions
What is ScrapeGraphAI used for?
It is a Python scraping library that builds an extraction pipeline from a natural language prompt and a source, using LLM calls and direct graph logic on top of LangChain. Sources can be web pages or local documents in XML, HTML, JSON and Markdown, and the pipelines cover single page, multi page, search results, script generation and audio output.
Is ScrapeGraphAI free?
The library is MIT licensed and installed from PyPI with `pip install scrapegraphai`, so running it yourself costs no licence fee. Its cost is the model you configure, since the graph makes LLM calls, and a separate playwright install is needed before it can fetch pages.
How much does ScrapeGraphAI cost?
The library itself is MIT licensed, so the software costs nothing to run and the expense sits with whichever model you point it at. The project also operates a managed cloud API reached through separate Python and JavaScript SDKs, which is a hosted product distinct from the library you install.
How do I use ScrapeGraphAI to scrape a page?
Install it with `pip install scrapegraphai` and then run `playwright install` so the browser binaries exist. Build a config dictionary with an `llm` block, `verbose` and `headless`, then create `SmartScraperGraph` with your prompt and a `source`, which returns a dictionary shaped by what you asked for.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/scrapegraphai-scrapegraph-ai)Star history chart for your README
[](https://hysenlabs.com/projects/scrapegraphai-scrapegraph-ai)Was this useful?