Debezium: change data capture that runs on Kafka Connect
Change data capture for a variety of databases. Please log issues at https://github.com/debezium/dbz/issues.
At a glance
- What is it?
- Debezium turns row-level database changes into ordered event streams. It is built for teams already running Kafka Connect, and the repository also ships an embedded engine and a standalone server for those who are not.
- Who is it for?
- Adopt Debezium if you already operate Kafka Connect and need committed, ordered row-level change events from MySQL, PostgreSQL, MongoDB, Oracle or SQL Server without writing per-database trigger code. Do not adopt it if you want a single binary that tails a database with no Kafka, no Connect cluster and no topic management; the embedded engine and debezium-server exist, but the README frames them as the reduced-fault-tolerance path.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
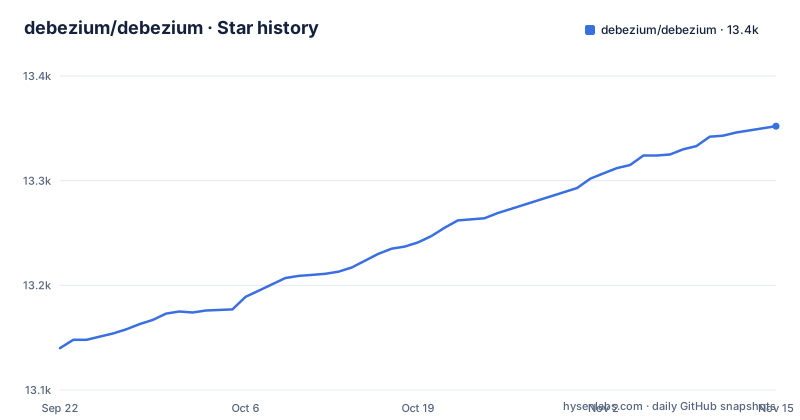
Star history
- debezium/debezium13,352 ★ · +212
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| debezium/debezium | 13.1k | 13.4k |
212 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem Debezium solves: committed row changes as ordered events
Database triggers are the traditional answer to "tell me when a row changed", and the README is blunt about why that answer is weak. Triggers are specific to each database and are often limited to updating state inside the same database, so they cannot talk to external processes. Some databases expose their own change-monitoring APIs, but there is no standard across them, so each integration needs specialized code and knowledge. Even then, keeping every change in the original order while barely touching the source database is hard.
Debezium's answer is a single event model. You configure it to monitor a database, and applications consume one event per row-level change. Only committed changes are visible, so consumers never see a transaction that later rolled back. Because changes are recorded in durable, replicated logs, a consumer can stop and restart and still read everything it missed.
The audience is narrow and specific: teams that already run Kafka, or are willing to, and want derived systems (caches, search indexes, read models, other applications) to follow the primary database instead of being written to twice. The CQRS case in the README is the same idea, one write model and one or more read models fed from the change stream.
How Debezium works: connectors, Kafka Connect and the embedded engine
The architecture is stated plainly in the README: Debezium reuses Kafka and Kafka Connect for durability, reliability and fault tolerance. Each connector deployed to the Kafka Connect distributed service monitors a single upstream database server, captures changes and writes them into one or more Kafka topics, typically one topic per table. Kafka then handles replication, total ordering and fan-out to many independent consumers with little impact on the source database.
Ordering guarantees are per table: all change events for a given database and table arrive in the order they occurred upstream. Consumers choose exactly-once or at-least-once delivery. That choice is a consumer-side setting, not a connector-side one, and it is worth knowing which one your pipeline actually needs before you build on top of it.
The repository layout shows the second path. debezium-embedded holds the embedded connector engine, which runs a connector inside the application and sends events directly to the application rather than persisting them in Kafka. debezium-server is the standalone server. The README is explicit that applications choosing the embedded route are giving up the fault tolerance, performance, scalability and reliability that Kafka Connect provides. That is a real trade, not a footnote.
The connector modules are also split by design philosophy. Some modules are generic and work across multiple database systems but are more limited in functionality and performance. Others are tailored to one system and use its specific features, so they are more capable. debezium-connector-mysql, debezium-connector-postgres, debezium-connector-mongodb, debezium-connector-oracle, debezium-connector-sqlserver and debezium-connector-mariadb are the per-database modules visible at the top level.
Installing Debezium and running a first connector
The project homepage is debezium.io, and the artifacts are published to Maven Central under the io.debezium group, which is what the Maven Central badge links to. So the practical route is: get the connector archive for your database from the Debezium documentation site, drop the connector plugin into your Kafka Connect plugin path, and configure it as a Connect connector.
The repository also contains debezium-assembly-descriptors and debezium-connect-plugins, which are the modules that produce the deployable connector archives. If you are building from source rather than downloading, that is where the packaging lives.
Where Debezium is the wrong tool
The strongest limitation is stated by the project itself: the embedded connector engine gives up the fault tolerance, performance, scalability and reliability that come from Kafka Connect. If your application cannot tolerate losing events during a crash, the embedded path is the wrong one, and you should run connectors on Kafka Connect instead.
The second constraint is operational weight. Debezium reuses Kafka and Kafka Connect, which means adopting it means operating a Connect cluster, managing topics, and understanding Connect's own failure and rebalance behaviour. A team that wants a single process reading a database will find that heavy. The README acknowledges this by offering the embedded engine and the standalone server, but it does not pretend those are equivalent.
The third is the snapshot question. Debezium captures changes, but a database that already has rows needs an initial read. The snapshot.mode setting is the one most likely to surprise a first-time operator. Read it before your first start against a production database, not after.
Finally, the connector split matters. Generic modules trade capability and performance for portability. If your workload needs the database-specific features, the generic module may not be the right choice even though it technically connects.
Debezium compared with a plain Kafka producer or a database trigger
The obvious alternative is having the application write to Kafka itself after committing to the database. The README calls this dual-writes and explains the failure mode: if the application crashes after the database commit but before the Kafka write, data is lost or the systems diverge. Debezium removes that window because the change event is derived from the committed database change rather than written alongside it.
The second alternative is database triggers plus a custom publisher. That keeps everything inside the database, which is simpler to reason about for a single system, but triggers are database-specific and often limited to updating state within the same database. You end up writing and maintaining specialized code per database, and you still have to solve ordering and delivery yourself.
The third is a generic Kafka producer reading from a queue or a polling job. Polling a table for changed rows means you need a reliable change marker, you add query load to the source, and you have to handle the gap between the marker and the actual commit. Debezium reads the database's own change log, which is why only committed changes appear and why the source impact stays low.
The trade is real in both directions. Debezium buys ordering, durability and a single event model, and it charges you a Connect cluster and per-connector configuration. A trigger-based publisher buys simplicity and charges you per-database code plus your own delivery guarantees.
Maintenance, releases and the Apache-2.0 licence
The repository is not archived, and the last push was on 2026-11-02, so the codebase is being committed to. That is a statement about activity, not about release cadence: the repository has no published GitHub releases, so there is nothing to say about version numbering or upgrade intervals. Teams planning an upgrade should read CHANGELOG.md at the repository root, which is where the project records changes between versions.
The licence is Apache-2.0, with one exception worth noting: the README states that the Antlr grammars inside the debezium-ddl-parser module are licensed under the MIT License. That module is the DDL parser, so if you redistribute or modify it, the licence terms for that component differ from the rest of the project. LICENSE-3rd-PARTIES.txt at the root covers third-party dependencies. This is a description of what the repository says, not legal advice; check with your own counsel if redistribution matters to you.
The upgrade cost is mostly operational rather than code-level. Connectors are deployed into Kafka Connect, so upgrading means replacing connector plugin archives and restarting connectors, and the CHANGELOG is where you find out whether a configuration property changed meaning. The repository also carries RELEASING.md for the maintainer-side process and CONTRIBUTING.md for contributors, neither of which affects adopters.
Editorial conclusion
Adopt Debezium if you already operate Kafka Connect and need committed, ordered row-level change events from MySQL, PostgreSQL, MongoDB, Oracle or SQL Server without writing per-database trigger code. Do not adopt it if you want a single binary that tails a database with no Kafka, no Connect cluster and no topic management; the embedded engine and debezium-server exist, but the README frames them as the reduced-fault-tolerance path. Before committing, verify the connector module for your specific database under the repository root, confirm your database version is supported, and read how snapshot.mode behaves for your initial snapshot, because that setting decides what happens to existing rows on first start.
Frequently asked questions
What is Debezium used for?
Debezium captures row-level changes from databases and streams them as events. The README lists cache invalidation, replacing dual-writes in monolithic applications, sharing databases between applications, data integration and CQRS as common use cases.
Is Debezium part of Kafka?
No. Debezium is a separate open source project that reuses Kafka and Kafka Connect for durability, reliability and fault tolerance. It is not a Kafka component, though its default deployment model runs connectors inside Kafka Connect.
Can we use Debezium without Kafka?
Yes. The README describes an embedded connector engine that runs a connector directly in the application and sends events to the application instead of persisting them in Kafka, and the repository contains a debezium-server module for standalone use. The README notes that applications taking the embedded route give up the fault tolerance, performance, scalability and reliability that Kafka Connect provides.
How do you pronounce "Debezium"?
The README's opening sections do not give a pronunciation.
What is Debezium CDC?
CDC stands for change data capture. Debezium provides a low latency data streaming platform for CDC: you configure it to monitor databases, and applications consume one event per committed row-level change.
What is Debezium Server?
Debezium Server is a standalone module in the repository, listed at the top level as debezium-server. The project homepage is debezium.io.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/debezium-debezium)Star history chart for your README
[](https://hysenlabs.com/projects/debezium-debezium)Was this useful?