Presto builds with one Maven command and starts only with seventeen add-opens flags
The official home of the Presto distributed SQL query engine for big data
At a glance
- What is it?
- Presto is a distributed SQL query engine for big data, developed as a standard Maven project whose modules include every connector and the web console. The two things a newcomer hits first are that the server main class still lives in the com.facebook package, and that Java 17 will not start it without a long list of module opens that the documentation itself calls incomplete.
- Who is it for?
- Presto fits a team that needs one SQL surface across many data systems and is prepared to run a coordinator and workers, and it fits contributors who want a Java codebase whose connectors are separate modules they can build alone. Before you deploy it, read the installation documentation rather than the repository, because the readme deliberately points there for deployment and the build instructions here are aimed at developers.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
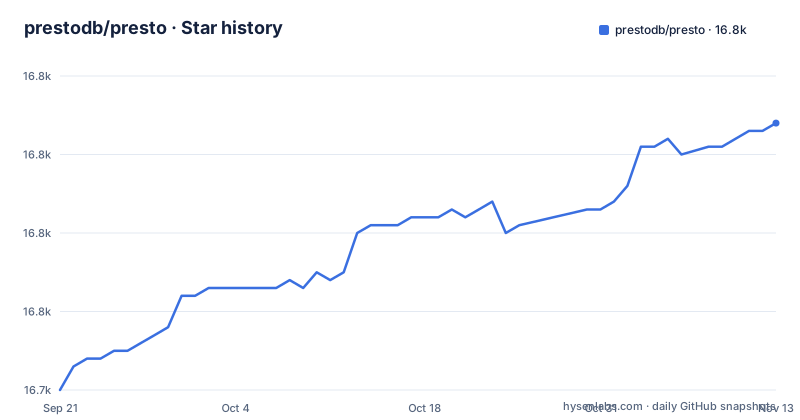
- prestodb/presto16,774 ★ · +34
| Repository | 2026-09-21 | 2026-11-13 |
|---|---|---|
| prestodb/presto | 16.7k | 16.8k |
34 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The server main class is still in the com.facebook package
The run configuration given for development starts a class named PrestoServer, and its fully qualified name is com.facebook.presto.server.PrestoServer. That package path is not an accident or a leftover in a sample file: it is the entry point you launch, the classpath you use, and the name that appears in logs and stack traces. Projects that fork and rename a query engine usually keep the original namespace for compatibility with existing deployment scripts, and this is one of the visible traces of that history. Anyone automating a local start, or writing a run configuration outside an IDE, needs the exact string rather than the modern project name. The rest of the configuration follows the same pattern of specificity: a fixed heap size, assertions enabled, the garbage collector pinned to G1 with a region size, a config file, a log levels file, and a flag that allows the process to attach to itself.
One wrapper command builds everything, and the cache is yours to relocate
Building is described as ordinary Maven work, which is the best possible answer for a repository this size. From the project root:
./mvnw clean installThe wrapper means no local Maven install is required. Two practical notes follow. The first build downloads everything from the internet into the local repository under the user's home directory, which can take a considerable amount of time, and later builds reuse that cache. When you work on more than one Presto project, each can write updates into that same global cache and cause build trouble, so the documentation tells you to configure your local maven config file to point the local repository at a directory inside the project with a repository property. The second note is about tests: the unit test suite is described as large and slow, taking several minutes, so a build that skips tests is a normal thing to type.
./mvnw clean install -DskipTestsThat flag is the difference between a coffee break and a lunch for anyone iterating on a change.
Java 17 needs a wall of add-opens flags, and the list is admitted to be short
This is the section that costs newcomers an afternoon. When running on Java 17, additional module open flags are required to allow reflective access used by certain catalogs, and the documentation prints the default set in full: opens for the io, lang, lang.ref, lang.reflect, net, nio, security, javax.security.auth, javax.security.auth.login, text, util, util.concurrent, util.concurrent.atomic and util.regex packages, plus the internal loader and the security action package, plus a Kerberos package under the security management module. Every one ends in an unnamed module target, which is the syntax that grants access without naming a module. Then the caveat that matters most: the printed set is not the whole list, and additional flags may be needed depending on the catalogs configured on the server. In other words, the flags you find in the documentation are the defaults, not the answer, and the set you need is discovered by running your own configuration.
An IDE bug is documented as a build step, with its tracker link
The IntelliJ section contains the most unusual instruction in the repository. When using JDK 17, an IntelliJ bug requires you to disable a specific setting, described as using the release option for cross-compilation for Java 9 and later, found under the compiler settings. If that option stays enabled you may hit errors such as package sun.misc does not exist, because the IDE fails to resolve certain internal JDK classes, and the documentation links the tracker issue so you can check its status. The rest of the setup is ordinary: import the project using the root pom file, select a JDK 17 distribution in the project structure, and set the project language level to at least 8.0. That last detail is the interesting one, because it explains why a codebase on Java 17 still targets an older language level, and it is the kind of compatibility setting that breaks silently when an IDE update changes a default.
The web console is compiled into a JAR and served by the coordinator
The console is not a separate application. It is composed of several React components written in JSX and ES6, and its source lives in the user interface module of the Maven reactor. The build compiles it to browser-compatible JavaScript and adds the result as JAR resources during the Maven build, so when that resource JAR is on the coordinator's classpath, the coordinator serves the assets. Two consequences follow from that design. First, there is no separate deployment for the console, which is convenient. Second, the Java code does not rely on the interface having been compiled, so a build can exclude it with a property, which is what you want in a continuous integration job that only needs the engine. The trade is that a change to the interface is invisible to the server unless the resources are rebuilt, so a stale console is a failure mode worth knowing about before you debug the wrong layer.
Talking to Hive from a laptop takes a SOCKS proxy and two properties
The sample configuration assumes a Hive metastore, and the instructions to make that work locally are specific. The Hive plugin must be given the location of the metastore's Thrift service through a property, defaulting to a local address in the example, and the list of loaded plugins is changed in the configuration file inside the main module's etc directory, where the plugin bundles entry lists plugin pom files. If the metastore or the HDFS cluster is not directly reachable from your machine, the documented route is an SSH dynamic proxy listening on a local port, followed by a second property pointing the metastore client at that proxy. With that in place, the command line client is a built executable jar, and two queries prove the setup: one selects from the system runtime nodes table to see the cluster, and one shows tables in the default database of the Hive catalog, which the sample configuration mounts under the hive name.
Every connector is a module in one reactor, plus the files that keep it honest
The module listing explains the scope better than any prose. Alongside the engine pieces you would expect, such as the client, the common library, the analyzer, the expression and bytecode modules, the function server and a blackhole connector, there is one module per data system: BigQuery, ClickHouse, Cassandra, Accumulo, Delta, Elasticsearch, Druid, Atop, an example HTTP connector, an Arrow-based flight base and its shim. Each connector therefore builds and tests as its own module inside one reactor, which is convenient for isolation and expensive for a full build. Around the code sit the files that keep such a repository honest: an architecture document that the readme points to for the mission and design, a functions document, a Jenkinsfile for continuous integration, a code owners file, a Docker directory, a pre-commit configuration, separate linting and formatting configurations for YAML, a licence header file and a development container definition.
Editorial conclusion
Presto fits a team that needs one SQL surface across many data systems and is prepared to run a coordinator and workers, and it fits contributors who want a Java codebase whose connectors are separate modules they can build alone. Before you deploy it, read the installation documentation rather than the repository, because the readme deliberately points there for deployment and the build instructions here are aimed at developers. If you are running it on Java 17, budget for the reflective access flags, and remember the documentation calls that list incomplete because it depends on which catalogs you load. Note the requirement line still names Python for the launcher script, which dates the requirements list. The newest release is 0.299 from 2026-08-28 and the default branch was pushed on 2026-11-02.
Frequently asked questions
What is Presto?
Presto is a distributed SQL query engine for big data, and this repository is its official home. The licence is Apache 2.0, the server main class is com.facebook.presto.server.PrestoServer, and the readme deliberately sends deployment questions to the separate installation documentation rather than describing deployment itself.
What do I need to build Presto from source?
Mac OS X or Linux, a 64-bit Java 17 with either Oracle JDK or OpenJDK, and Maven 3.6.3 or newer. The build itself is the Maven wrapper: run ./mvnw clean install from the project root, add -DskipTests when you do not want to wait several minutes for the unit tests, and set a project-local repository path if you build more than one Presto project at a time.
Why does the Presto server fail to start on Java 17?
Certain catalogs use reflective access that Java 17 blocks by default, so additional add-opens flags are required at runtime. The documentation prints the default set covering the io, lang, net, nio, security, text and util packages among others, and states explicitly that the printed set is not the whole list: additional flags may be needed depending on the catalogs configured on the server.
How do I run the Presto command line client?
The built client is an executable jar under the command line module's target directory, named presto-cli followed by the version and an executable suffix. Once it is connected to a server you can query the cluster with a select against the system runtime nodes table, or list tables in the Hive catalog with a show tables statement, since the sample configuration mounts the Hive connector under the hive name.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/prestodb-presto)Star history chart for your README
[](https://hysenlabs.com/projects/prestodb-presto)Was this useful?