3FS: DeepSeek's Fire-Flyer File System, Reviewed for AI Storage Teams
A high-performance distributed file system designed to address the challenges of AI training and inference workloads.
At a glance
- What is it?
- 3FS is a C++ distributed file system built for AI training and inference, using CRAQ replication, FoundationDB-backed metadata and RDMA. It is not a drop-in NFS replacement, and the build is the first real obstacle.
- Who is it for?
- Adopt 3FS if you run large-scale training or inference and already operate RDMA networks and FoundationDB, because its metadata layer depends on a transactional key-value store you must run yourself. Do not adopt it for a small cluster, a single node, or a general-purpose office file share: the README's own performance figures come from a 180-node cluster with 200Gbps InfiniBand, and there is no documented lightweight mode.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
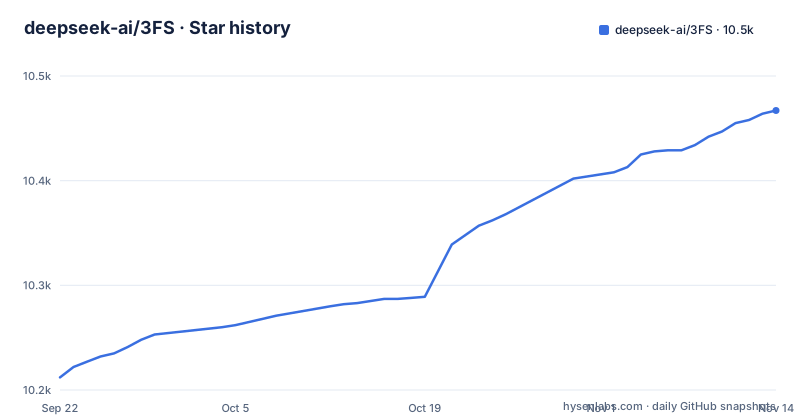
- deepseek-ai/3FS10,467 ★ · +255
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| deepseek-ai/3FS | 10.2k | 10.5k |
255 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What 3FS Is For, and Who Should Care
3FS targets a specific class of workload: AI training and inference jobs that need a shared storage layer across many compute nodes. The README lists four: data preparation, dataloaders, checkpointing, and KVCache for inference. Those four share a property that ordinary POSIX file systems handle badly. They involve many clients reading and writing large objects at the same time, and the access pattern is not locality-friendly.
The design answer is a disaggregated architecture. Storage nodes hold the SSDs, and applications access storage "in a locality-oblivious manner", as the README puts it. That is a real architectural commitment. It means you need a fast network between compute and storage, and the README's reference cluster uses 2x200Gbps InfiniBand NICs per storage node with sixteen 14TiB NVMe SSDs.
If you are running a handful of GPU servers with local NVMe, 3FS is the wrong shape of tool. The overhead of running metadata services, storage services and a FoundationDB cluster will exceed anything you gain. The project is aimed at operators who already think in terms of storage nodes and fabric bandwidth.
CRAQ Replication and the FoundationDB Metadata Layer
Two mechanisms carry most of the design weight. The first is Chain Replication with Apportioned Queries, or CRAQ, which the README describes as the basis for strong consistency. In chain replication, writes travel down a chain of replicas and reads are served by the tail. CRAQ apportions queries across the chain so reads can be served by more than one node while still returning consistent data. The practical consequence for application authors is that the README claims application code becomes "simple and easy to reason about". You do not write retry logic around eventual consistency.
The second mechanism is the metadata layer. 3FS uses stateless metadata services backed by a transactional key-value store, with FoundationDB named as the example. This is the part that determines your operational burden. Stateless metadata services are easy to scale horizontally, but they are stateless only because FoundationDB holds the state. You are therefore running a second distributed system underneath the file system, and its availability is your availability.
The file interface itself is deliberately conventional. The README states there is no need to learn a new storage API. Alongside the FUSE client in the hf3fs_fuse directory, the repository ships a USRBIO API with its own reference document at src/lib/api/UsrbIo.md, and a fio engine for USRBIO under benchmarks/fio_usrbio.
Building 3FS: Submodules, Dependencies, and the SHUFFLE_METHOD Trap
There is no package to install. 3FS is built from source, and the README's setup path starts with the repository and its submodules. The patches script is part of that sequence, not optional.
git clone https://github.com/deepseek-ai/3fs
cd 3fs
git submodule update --init --recursive
./patches/apply.sh
Dependencies are grouped by distribution in the README, with separate apt command blocks for Ubuntu 20.04 and Ubuntu 22.04, and Docker build images for TencentOS-4 and OpenCloudOS-9. Three prerequisites sit outside the package manager lists: libfuse 3.16.1 or newer, FoundationDB 7.1 or newer, and a Rust toolchain with a minimum of 1.75.0 and a recommendation of 1.85.0 or newer. The Cargo.toml workspace confirms the Rust side, with rust-version set to 1.85.0 and three members: src/client/trash_cleaner, src/storage/chunk_engine, and src/lib/rs/hf3fs-usrbio-sys.
The build itself is a CMake invocation, and this is where a genuine trap sits. The README warns that binaries compiled with different compiler versions may be incompatible because of historical use of std::shuffle, and links to issue 368. The fix is to pass SHUFFLE_METHOD explicitly.
# Replace <method> with 'g++10' or 'g++11' based on your environment
cmake -S . -B build \
      -DCMAKE_CXX_COMPILER=clang++-14 -DCMAKE_C_COMPILER=clang-14 \
      -DCMAKE_BUILD_TYPE=RelWithDebInfo -DCMAKE_EXPORT_COMPILE_COMMANDS=ON \
      -DSHUFFLE_METHOD=<method>
cmake --build build -j 32
After the build completes you should have binaries under the build directory. The README points to deploy/README.md for the actual cluster setup, and that is the document you need next, because the top-level README stops at compilation. Note what the README does not cover here: it does not document rollback, does not describe an upgrade procedure, and does not give a single-node quick start. The setup guide under deploy/ is the only place those answers could live.
Where 3FS Breaks Down or Is Simply the Wrong Choice
The clearest limitation is environmental. The README's throughput claims are tied to hardware: a 180-node cluster with 2x200Gbps InfiniBand NICs per storage node and sixteen 14TiB NVMe SSDs each, with 500+ client nodes at 1x200Gbps. The GraySort result comes from 25 storage nodes with 2x400Gbps NICs and 50 compute nodes. Those numbers describe a fabric and a disk count, not a software property you can transfer to a three-node lab.
The second limitation is the dependency stack. FoundationDB is not incidental. The README describes metadata services as backed by a transactional key-value store and names FoundationDB as the example, with version 7.1 or newer required. Operating FoundationDB is a separate skill from operating a file system, and a metadata store outage is a file system outage.
The third limitation is the compiler compatibility issue itself. The README says binaries built with different compiler versions may be incompatible, and that existing clusters should use the method corresponding to their compiler version. That is an operational constraint on how you build and upgrade, and it is the kind of detail that bites during a rolling upgrade rather than during initial setup.
Finally, consider what 3FS is not. The README does not present it as a general-purpose file server, a backup target, or a replacement for object storage. The workloads listed are all AI pipeline stages. If your problem is shared home directories for a research group, this is a large amount of machinery for a job that NFS or a parallel file system already does with less to operate.
How It Compares to a POSIX Parallel File System
The obvious alternative category is a traditional parallel file system such as Lustre or GPFS, which also present a POSIX interface over many storage nodes. The difference in approach is in the metadata layer. Traditional parallel file systems run a dedicated metadata service with its own on-disk format and its own replication scheme. 3FS makes the metadata services stateless and pushes state into FoundationDB, a general transactional key-value store.
That choice has two consequences. Metadata services become easy to restart and scale because they hold nothing, and consistency guarantees come from a database that already solves transactional semantics. The cost is that you now depend on FoundationDB's own operational model, its cluster management, and its version compatibility. If your team already runs FoundationDB for another service, this is close to free. If not, it is a new system to learn.
The second difference is the client. Traditional parallel file systems typically offer a kernel module or a native client. 3FS offers FUSE plus USRBIO. FUSE is convenient and portable, but it routes I/O through userspace; the repository also ships a separate USRBIO API and a fio engine for it.
Maintenance, Licence, and What the Repository Does Not Say
The licence is MIT, stated in the README badge and in the Cargo.toml workspace metadata. MIT is permissive: it allows commercial use, modification, and redistribution with the licence text retained. Nothing in the repository suggests a copyleft obligation on your own code. That is a summary of the licence identifier, not legal advice; if your organisation has a review process, run it.
The last push to the default branch was on 2026-05-07. The repository is not archived, but that is roughly six months before today, so treat the project as one with infrequent pushes rather than continuous activity. The repository has no published GitHub releases, which means versioning is tied to the source tree. The setup.py file computes a version string as "1.2.9+" followed by the short git revision, so a build is identified by a commit hash rather than a published release number. Plan your upgrades around commits, not tags.
Upgrade cost is dominated by the compiler compatibility constraint. Because the README warns that binaries compiled with different compiler versions may be incompatible and instructs existing clusters to keep using their original SHUFFLE_METHOD, an upgrade path that changes compilers is not a simple rebuild. The README does not document a rollback procedure, and it does not describe how to migrate a running cluster between shuffle methods. Verify that before you plan a version change.
Editorial conclusion
Adopt 3FS if you run large-scale training or inference and already operate RDMA networks and FoundationDB, because its metadata layer depends on a transactional key-value store you must run yourself. Do not adopt it for a small cluster, a single node, or a general-purpose office file share: the README's own performance figures come from a 180-node cluster with 200Gbps InfiniBand, and there is no documented lightweight mode. Before committing, verify three things: that your compilers match the -DSHUFFLE_METHOD you pass to CMake, that FoundationDB 7.1 or newer and libfuse 3.16.1 or newer are available on your target OS, and that your client nodes have the RDMA bandwidth the design assumes.
Frequently asked questions
What is 3FS?
3FS, the Fire-Flyer File System, is a distributed file system from DeepSeek aimed at AI training and inference workloads. It uses CRAQ for strong consistency and stateless metadata services backed by a transactional key-value store such as FoundationDB.
How do I build 3FS from source?
Clone the repository, run git submodule update --init --recursive and ./patches/apply.sh, install the distribution-specific dependencies plus libfuse 3.16.1, FoundationDB 7.1 and a Rust toolchain, then configure with CMake and build. The CMake step must include -DSHUFFLE_METHOD set to g++10 or g++11 to keep binaries compatible.
Does 3FS work with FUSE?
Yes. The repository contains an hf3fs_fuse component, and the README describes the file interface as well known and used everywhere. For higher throughput the project also provides the USRBIO API, documented in src/lib/api/UsrbIo.md, with a fio engine under benchmarks/fio_usrbio.
What does 3FS use for metadata storage?
The README states that 3FS develops stateless metadata services backed by a transactional key-value store, naming FoundationDB as the example. FoundationDB 7.1 or newer is listed as a build prerequisite.
Is 3FS suitable for a small cluster?
The README's performance figures come from clusters with 180 storage nodes and 200Gbps InfiniBand NICs, or 25 storage nodes with 2x400Gbps NICs. The design assumes disaggregated storage over a fast fabric and requires you to operate FoundationDB, so a small deployment carries the full operational cost without the workload that justifies it.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Jensen is out. CUDA isn't. A Developer's Guide to Everything Nvidia Builtdev.to · Nov 13, 2026 · 7 points · 2 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/deepseek-ai-3fs)Star history chart for your README
[](https://hysenlabs.com/projects/deepseek-ai-3fs)Was this useful?