LightGBM: histogram-based gradient boosting, and what the repository actually commits to
A fast, distributed, high performance gradient boosting (GBT, GBDT, GBRT, GBM or MART) framework based on decision tree algorithms, used for ranking, classification and many other machine learning tasks.
At a glance
- What is it?
- LightGBM is a C++ gradient boosting framework with Python, R and other bindings, now hosted at lightgbm-org/LightGBM. The case for adopting it rests on its histogram tree construction and distributed training modes, while the case against rests on how much tuning and infrastructure it assumes you already have.
- Who is it for?
- Adopt LightGBM when you have tabular data with many rows and a team willing to tune num_leaves, min_data_in_leaf and feature_fraction rather than accept defaults. Do not adopt it if you need calibrated probabilities out of the box, if your data is images or text where a neural approach fits better, or if you cannot operate the distributed setup that the parallel guide describes.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
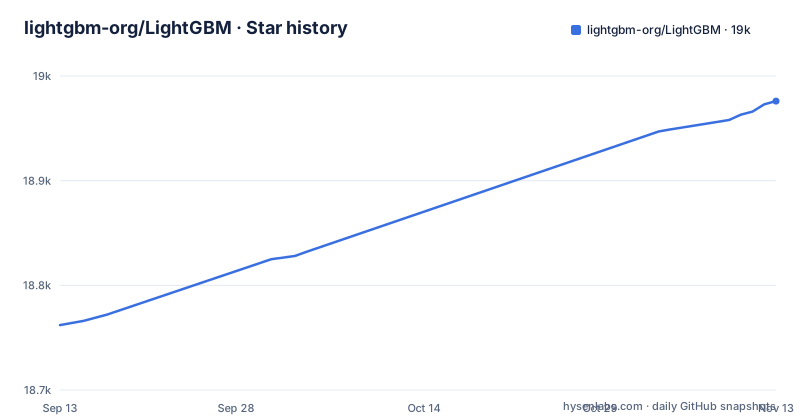
- lightgbm-org/LightGBM18,976 ★ · +214
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| lightgbm-org/LightGBM | 18.8k | 19k |
214 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem LightGBM was built to solve
Gradient boosted decision trees were already the default answer for tabular prediction before LightGBM existed. The cost was in training time and memory: exact split finding scans every feature value at every node, so a dataset with millions of rows and thousands of columns becomes slow and memory hungry. LightGBM's stated advantages in the README are faster training, lower memory use, better accuracy, and support for parallel, distributed and GPU learning, with the explicit claim of handling large-scale data. The intended audience is therefore not someone fitting a model on a few thousand rows in a notebook. It is someone who has outgrown that, whether in a competition setting (the repository links to machine learning challenge winning solutions) or in a production pipeline where retraining frequency matters. The README also points to FLAML and the Optuna LightGBM tuner for automated hyperparameter search, which tells you something about the project's own view of its defaults: they expect you to tune.
Histogram binning and leaf-wise growth, the two decisions that shape everything
The repository describes LightGBM as a gradient boosting framework using tree based learning algorithms, designed to be distributed and efficient. The efficiency claim comes from how splits are found. Rather than sorting continuous feature values and evaluating every candidate threshold, the histogram approach buckets feature values into discrete bins and searches over bin boundaries. That reduces the candidate set per feature and lets the implementation store binned data in a compact form, which is where the lower memory use comes from. The second decision is tree growth. LightGBM grows trees leaf-wise: it picks the leaf with the largest estimated gain and splits that one, rather than expanding every node at the current depth as level-wise growth does. Leaf-wise growth reaches lower training loss for a given number of leaves, but it produces deeper, less balanced trees, and it is the reason parameters like num_leaves and min_data_in_leaf matter so much. Set num_leaves high with no floor on leaf size and you get overfitting on small data. The parallel, distributed and GPU modes sit on top of the same tree construction, which is why the parallel learning guide is a separate document rather than a set of flags buried in the main parameter list.
Getting it running: install paths and the parameters you actually touch
The README directs new users to the installation instructions on readthedocs rather than giving commands inline, so the exact command depends on your platform and language binding. What the repository does confirm is the set of distribution channels: PyPI for the Python package, conda-forge, CRAN for the R package, NuGet, and winget on Windows. A Python user therefore has at least three legitimate entry points (pip, conda, or a source build). Once installed, the README points to the parameters document as an exhaustive list of customization. Commonly tuned parameters include num_leaves and min_data_in_leaf for tree shape, and feature_fraction for column subsampling. The README also lists examples showing command line usage of common tasks, which is the fastest way to see the CLI form of training before wiring up a Python script. For tuning, the README names two external tools rather than shipping one: FLAML, described as a fast and lightweight AutoML library, and the Optuna LightGBM tuner. Both are linked as code examples, not vendored into the repository.
Distributed and GPU training are separate guides, not a flag
The README treats distributed learning and GPU learning as their own documentation paths, with dedicated guides for parallel learning and a GPU tutorial. That structure is a signal. Distributed training in LightGBM is not a matter of setting one parameter and walking away; the parallel learning guide exists because there are different parallelisation strategies with different trade-offs, and the experiments document reports linear speed-up only in specific settings, which is the project's own qualifier. The GPU tutorial is likewise a separate track, with its own build requirements, and the CI configuration visible in the README shows a dedicated CUDA workflow, meaning the GPU path is built and tested independently of the CPU path. If your team plans to use either mode, budget for reading the corresponding guide and for a build that matches it.
Where LightGBM is the wrong tool
Two limitations are worth stating plainly. First, leaf-wise growth with default settings is prone to overfitting on small datasets. The mechanism is straightforward: the algorithm keeps splitting the highest-gain leaf, so with few rows it will carve out small, specific leaves that do not generalise. If your dataset is a few thousand rows with a handful of features, a level-wise implementation or a simpler model will often match or beat LightGBM with far less tuning effort. Second, the probabilities a boosted tree model outputs are not guaranteed to be calibrated. If your downstream system consumes predicted probabilities and treats them as frequencies, you need a calibration step outside LightGBM. A third case: the README's own framing is tabular and ranking oriented. That makes it a poor fit for image, audio or raw text inputs, where representation learning does the heavy lifting.
XGBoost as the alternative, and the real difference
The obvious alternative is XGBoost, and the difference is not marketing. XGBoost's default tree construction is level-wise (depth-wise) growth, expanding all nodes at a given depth before going deeper, which produces more balanced trees and tends to be more forgiving on small datasets without extensive tuning. LightGBM's leaf-wise growth is the opposite bet: accept less balanced trees in exchange for faster reduction in training loss per leaf. The second difference is split finding. XGBoost historically used an exact or approximate quantile sketch over sorted feature values; LightGBM's histogram binning is the core of its speed and memory story. The practical consequence is that LightGBM usually wins on large, wide datasets where histogram binning pays off, and XGBoost is often the safer default when your data is small or your team does not want to spend time on tree-shape parameters. Neither is universally better, and the repository's own comparison experiments are the project's evidence for its claims, not an independent benchmark.
Licence, maintenance and the cost of staying current
LightGBM is MIT licensed, which is permissive and places few obligations on how you redistribute or modify it. That is the whole of the licence implication I can state here; anything about patent grants, contributor agreements or compatibility with your organisation's policy needs a lawyer, not this article. On maintenance, the repository shows a steady release cadence: v4.5.0 in July 2024, v4.6.0 in February 2025, v4.7.0 in July 2026, with the last push dated October 2026. The README notes the project moved from Microsoft/LightGBM to lightgbm-org/LightGBM in March 2026 and states that the same maintainers, including the creator of LightGBM, are behind it. That move is the single most consequential operational detail for anyone with pinned dependency URLs, internal mirrors or vendored copies. The version scheme is EffVer, which the README advertises via a badge; EffVer ties version numbers to the effort a change demands from users rather than to semantic versioning's compatibility rules, so a minor version bump can still require code changes. Read the changelog on the releases page before upgrading, and treat the upgrade as a task with a cost rather than a routine bump.
Editorial conclusion
Adopt LightGBM when you have tabular data with many rows and a team willing to tune num_leaves, min_data_in_leaf and feature_fraction rather than accept defaults. Do not adopt it if you need calibrated probabilities out of the box, if your data is images or text where a neural approach fits better, or if you cannot operate the distributed setup that the parallel guide describes. Before committing, verify which install path your platform supports, confirm the release you pin against the changelog, and check that the repository move to lightgbm-org/LightGBM is reflected in your dependency URLs.
Frequently asked questions
Is LightGBM better than XGBoost?
The README does not name any competing library. What it says is that comparison experiments on public datasets show LightGBM can outperform existing boosting frameworks on both efficiency and accuracy, with significantly lower memory consumption, and it links the experiments document under the documentation directory. The distributed experiments are described separately as showing a linear speed-up in specific settings.
What is LightGBM used for?
It is a gradient boosting framework that uses tree based learning algorithms, described as used for ranking, classification and many other machine learning tasks, with the acronym set given as GBT, GBDT, GBRT, GBM and MART. The examples tree covers binary classification, regression, multiclass classification, a ranking objective, an `xendcg` example, and parallel learning.
What are the disadvantages of LightGBM?
The README lists advantages only, five of them, with no numbers. The facts it does state that bear on cost are that GPU learning is a build target documented by a tutorial rather than by an example, that distributed speed-up is described as linear in specific settings, and that every model compiler, alternative inference backend, ONNX converter, explanation tool and platform integration is listed as unofficial and not endorsed by the development team.
how to use lightgbm with gpu
There is no GPU code in the README. It points to a GPU learning tutorial and a distributed learning guide under the documentation directory for speeding up computation, and the continuous integration workflows include a dedicated CUDA one. GPU accelerated inference itself appears only in the list of unofficial external repositories, not as a feature of this project.
how to install lightgbm
The README carries no install command. It says the primary documentation is hosted at the readthedocs site, that the site is generated from this repository, and that anyone new to the project should follow the installation instructions there. Packages are published to PyPI, conda-forge, CRAN, NuGet and the Windows package manager.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/lightgbm-org-lightgbm)Star history chart for your README
[](https://hysenlabs.com/projects/lightgbm-org-lightgbm)Was this useful?