PowerInfer splits hot neurons onto the GPU and cold ones onto the CPU
High-speed Large Language Model Serving for Local Deployment
At a glance
- What is it?
- PowerInfer is a C++ inference engine for serving ReLU-sparse models on one consumer GPU, built on the observation that neuron activation follows a power law. It is fast inside a narrow envelope: four model families, AVX2 CPUs, NVIDIA GPUs on Linux or Windows, and a macOS path that runs on the CPU alone.
- Who is it for?
- Adopt PowerInfer if your checkpoint is already ReLU-sparse, it belongs to one of the four families the README lists, and you have an AVX2 machine with an NVIDIA GPU under Linux or Windows. Do not adopt it for a dense checkpoint, for a Mac, or for a Radeon card, because each of those is missing from the model list or the tested-platform list.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
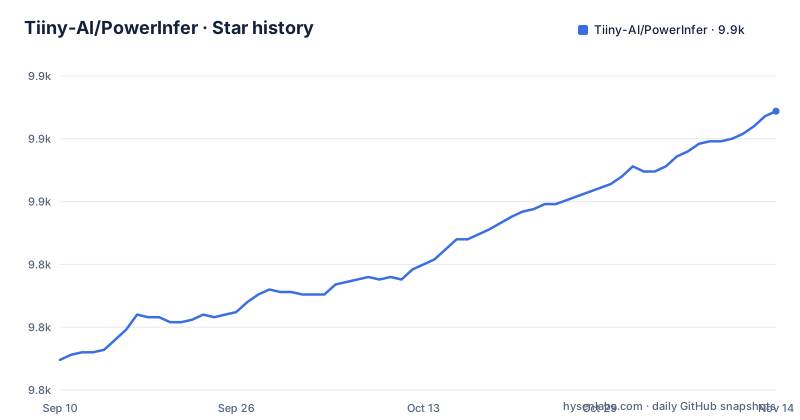
- Tiiny-AI/PowerInfer9,886 ★ · +99
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| Tiiny-AI/PowerInfer | 9.8k | 9.9k |
99 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Hot neurons go to the GPU, cold neurons go to the CPU
The design turns on one measurement: neuron activation in an LLM follows a power-law distribution, so a small set of hot neurons fires on nearly every input while the cold majority changes with the input. PowerInfer splits the work along that line. Hot-activated neurons are preloaded onto the GPU, where they are already resident and cheap to reach. Cold-activated neurons are computed on the CPU. The stated payoff is a smaller GPU memory footprint and fewer transfers between the two processors, and two more pieces sit on top of the split: adaptive predictors that decide which neurons will be hot, and neuron-aware sparse operators that do the sparse arithmetic. That mechanism carries the headline figures, an average of 13.20 tokens per second and a peak of 29.08 tokens per second across several models including OPT-175B on a single RTX 4090, reported as 18% below what the same document gets from a top-tier server-grade A100.
Four model families are usable today, and the abstract quotes a fifth
The list of models the project says you can run is short: Falcon-40B, the Llama2 family, the ProSparse Llama2 family and Bamboo-7B. Each is a ReLU-sparse model, which is what the activation-locality path needs, and the engine points at a Hugging Face collection of ReLU-sparse models as the compatible set. The gap between that list and the abstract deserves attention. The abstract quotes its token rates across various LLMs including OPT-175B, and OPT-175B appears nowhere in the list of models you can use today. So the numbers that carry the argument for the engine cannot be reproduced with the models the same document tells you to pick. If your checkpoint sits outside those four families, the model list gives no guidance for it.
macOS is CPU only while the tree already ships the Metal sources
The macOS entry in the tested-platform list is a placeholder with an admission attached: Apple M chips, CPU only, followed by a note that the project does not optimize for Mac, so the performance improvement is not significant now. A Metal backend for sparse inference on macOS sits under features coming soon, and the README points readers at a Project Kanban for the current focus. What turns this from a scheduling detail into a gap is the tree itself. ggml-metal.m, ggml-metal.h and ggml-metal.metal sit at the top level next to ggml-cuda.cu. The Metal code is in the repository, the sparse Metal backend is not in the engine. On a Mac today you get the fallback path, the one half of the hybrid design the project treats as the cold side.
AMD support shows up as a news line and never again
The news feed carries two dated entries about the same hardware story. The 2024/5/17 line announces support for AMD devices with ROCm. The 2024/5/20 line frames optimizing the engine with open-source ROCm/HIP as a problem in a national competition organised by the Technical Committee on Computer Architecture of the China Computer Federation. The tested-platform list says x86-64 CPUs with AVX2 instructions, with or without NVIDIA GPUs, under Linux, and the same under Windows. No AMD, no ROCm, in the place a reader would check before buying a card. An owner of a Radeon has a 2024 news line and a support list that names only NVIDIA, and nothing that tells them which of the two to believe.
Cloning the tree, because requirements.txt installs two local directories
Two prerequisites are named: CMake 3.17 or newer, and Python 3.8 with pip 19.3 or newer, the latter for converting model weights and automatic FFN offloading. Getting the code is three lines, and the third one carries the constraint:
git clone https://github.com/Tiiny-AI/PowerInfer
cd PowerInfer
pip install -r requirements.txt
Read what that install resolves. Two of the five entries in requirements.txt are paths inside the clone rather than names from an index:
numpy>=1.24.4
sentencepiece>=0.1.98
transformers>=4.33.2
./gguf-py
./powerinfer-py
That is why the clone comes before the install. gguf-py and powerinfer-py are local directories, so the Python side only resolves from a source tree, and the CMake prerequisite is there to build it. The first real use after that is picking one of the four supported model families and running one of the shell scripts under examples/, the same way you would with llama.cpp.
The vendored llama.cpp is a compatibility layer, and its weights buy no speed
PowerInfer carries llama.cpp inside its own tree, a llama.cpp source file next to llama.h, the ggml sources and an examples/ directory. The stated relationship is backward compatibility rather than a second implementation: most of examples/ is used the same way as in llama.cpp, server and batched generation included, and PowerInfer will run llama.cpp's model weights. The README prices that last claim in the same sentence it makes it, there will be no performance gain. So the speed does not come from the file format. It comes from the sparse activation path, which needs weights somebody already sparsified, ProSparse Llama 2, TurboSparse and Bamboo. The head-to-head the README reports is one RTX 4090(24G) running Falcon(ReLU)-40B-FP16 with an 11x speedup over llama.cpp, both fully using VRAM. A Gradio server hosting that model is online, labelled experimental and without warranties.
No releases, no homepage, and a build surface wider than the prerequisites
There is no version to install. The repository publishes no GitHub releases and has no homepage, and its default branch is main, so a clone gives you whatever that branch holds on the day you run it. The build surface is wider than the two documented prerequisites: CMakeLists.txt is there, and so are build.zig for a Zig build, flake.nix and flake.lock for Nix, Package.swift beside an examples/batched.swift, plus ci/, cmake/, scripts/, pocs/, docs/, media/ and grammars/. The last push to main was on 2026-05-11. Price the fork-and-build step before planning around it, because you are compiling a C++ engine with vendored ggml sources from an unreleased branch.
Editorial conclusion
Adopt PowerInfer if your checkpoint is already ReLU-sparse, it belongs to one of the four families the README lists, and you have an AVX2 machine with an NVIDIA GPU under Linux or Windows. Do not adopt it for a dense checkpoint, for a Mac, or for a Radeon card, because each of those is missing from the model list or the tested-platform list. Before you build, check that the model you care about is on that list and that the abstract figures you are relying on name a model that is on it. The last push to main was on 2026-05-11 and the repository publishes no releases, so you compile an unreleased branch.
Frequently asked questions
What hardware does PowerInfer run on?
x86-64 CPUs with AVX2 instructions, with or without NVIDIA GPUs, under Linux, and the same under Windows. Apple M chips run it on macOS in CPU-only mode, and the README notes the Mac path is not optimized so the gain there is not significant.
Does PowerInfer work with llama.cpp model weights?
Yes, and the README attaches the cost to the same sentence: PowerInfer supports inference with llama.cpp's model weights for compatibility purposes, but there will be no performance gain. Most of examples/ is also used the same way it is in llama.cpp.
How do I build PowerInfer from source?
You need CMake 3.17 or newer plus Python 3.8 and pip 19.3 or newer, then clone the repository and install requirements.txt. That file names numpy>=1.24.4, sentencepiece>=0.1.98 and transformers>=4.33.2 alongside two local paths, ./gguf-py and ./powerinfer-py, so the install only resolves inside a source tree.
Which models can PowerInfer serve today?
Falcon-40B, the Llama2 family, the ProSparse Llama2 family and Bamboo-7B. The engine targets ReLU-sparse models..
Does PowerInfer use the GPU on an Apple Silicon Mac?
Not yet. The tested-platform list marks Apple M chips as CPU only, and a Metal backend for sparse inference on macOS is listed under features coming soon, even though ggml-metal.m and ggml-metal.metal are present at the top level of the tree.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tiiny-ai-powerinfer)Star history chart for your README
[](https://hysenlabs.com/projects/tiiny-ai-powerinfer)Was this useful?