DeepSeek-V3: A 671B MoE Model That Puts Training Cost and Load Balancing First
The repository metadata lists Python as its primary language. The metadata lists the MIT license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- DeepSeek-V3 is a 671B-parameter Mixture-of-Experts model with 37B active parameters per token, trained for 2.788M H800 GPU hours. This review covers its architecture, how to get the weights, and the trade-offs you should check before adopting it.
- Who is it for?
- Adopt DeepSeek-V3 if you need a high-capability open-weight model with a per-token compute cost near 37B parameters and you can handle the 685B total download size. Do not adopt it if you need a small model, if your hardware cannot fit even the active 37B parameters, or if you require guaranteed stability of community MTP tooling.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Probably not. The repository last received commits 14 months ago, on August 28, 2025.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
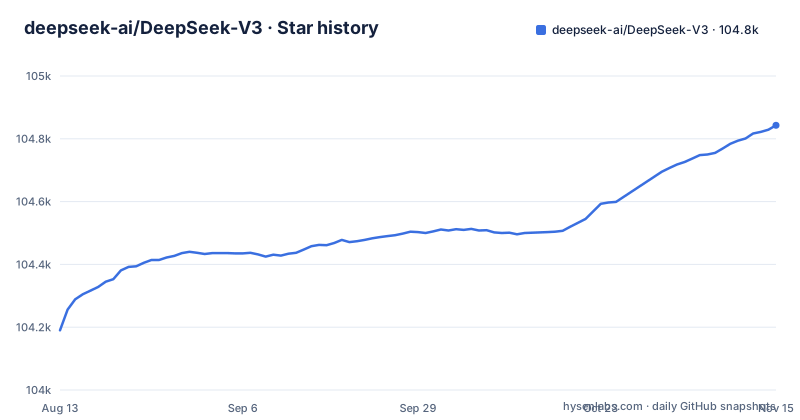
- deepseek-ai/DeepSeek-V3104,843 ★ · +653
| Repository | 2026-08-13 | 2026-11-15 |
|---|---|---|
| deepseek-ai/DeepSeek-V3 | 104.2k | 104.8k |
653 Stars in the last 94 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What DeepSeek-V3 Actually Solves
DeepSeek-V3 targets the problem of training and running a very large language model without paying the full cost of a dense model. It is a Mixture-of-Experts (MoE) model with 671B total parameters, but only 37B are activated for each token. That means the memory footprint is large, but the compute per token is closer to a 37B dense model. The project is for teams that want near-frontier quality, as the README claims it outperforms other open-source models and is comparable to closed-source ones, but who cannot spend the GPU hours that a dense 405B model like LLaMA 3.1 would require. The README states the full training took 2.788M H800 GPU hours, with pre-training at 2.664M and post-training at 0.1M. That is the core value proposition: a model that behaves like a much larger dense model, at a fraction of the training cost.
The Architecture: MLA, DeepSeekMoE, and No Auxiliary Loss
The model builds on DeepSeek-V2's architecture, which includes Multi-head Latent Attention (MLA) and DeepSeekMoE. MLA is a form of attention that compresses the key-value cache, which reduces memory during inference. DeepSeekMoE is the expert routing mechanism that activates only a subset of experts per token. The notable new piece is the auxiliary-loss-free strategy for load balancing. Traditional MoE models add an auxiliary loss to encourage all experts to receive a similar number of tokens, but that loss can degrade model quality. DeepSeek-V3 avoids that by using a different balancing mechanism, which the README says minimizes the performance degradation that comes from encouraging load balancing. This is a real design choice, not a marketing phrase. It means the model may route tokens unevenly, but the training objective does not penalize that directly. The trade-off is that you need to trust the routing is stable enough in practice. The README also claims that during the entire training, there were no irrecoverable loss spikes and no rollbacks, which suggests the balancing strategy did not cause training instability.
Multi-Token Prediction and Speculative Decoding
DeepSeek-V3 introduces a Multi-Token Prediction (MTP) objective. Instead of predicting only the next token, the model is trained to predict multiple future tokens at once. The README states this objective is beneficial to model performance. It also says MTP can be used for speculative decoding to accelerate inference. Speculative decoding works by having a smaller model propose several tokens, and the larger model verifies them in parallel. The MTP module, which is separate from the main model weights, is what enables this. The Hugging Face download size is 685B, which includes 671B of main model weights and 14B of MTP module weights. The README notes that MTP support is under active development within the community, so you should not assume it works out of the box with every inference framework. If you only need standard generation, you can likely ignore the MTP module, but you will still download the full 685B unless you selectively fetch only the main weights.
FP8 Training and the Communication Bottleneck
The training efficiency claim rests on two things: an FP8 mixed precision framework and a co-design of algorithms, frameworks, and hardware to overcome the communication bottleneck in cross-node MoE training. The README says this is the first validation of FP8 training on an extremely large-scale model. FP8 reduces memory and compute, but it can introduce numerical instability. The README claims the training was stable, with no irrecoverable loss spikes. For an engineer, this is a signal that the FP8 scheme is mature enough for large-scale use, but you are not likely to retrain the model yourself. The more relevant point for adoption is inference: does your hardware support FP8 efficiently? If you run on GPUs that do not have good FP8 support, you may need to use a higher precision like BF16, which will increase memory and compute. Verify inference performance on your own hardware.
How to Get It Running Locally
The README points to two models on Hugging Face: DeepSeek-V3-Base and DeepSeek-V3, both with 671B total parameters and 128K context length. The download size is 685B, which includes the MTP module. The README says they have partnered with open-source communities and hardware vendors to provide multiple ways to run the model locally, and it directs you to Section 6 for step-by-step guidance. The README also mentions a file README_WEIGHTS.md for details on the main model weights and MTP modules. Given the 671B total parameter size, expect to need a multi-GPU setup. Even with 37B active, the model must be loaded into memory, so you need enough VRAM to hold all weights, or use CPU offloading, which will be slow.
Evaluation Results: Where It Wins and Where It Does Not
The README includes a table comparing DeepSeek-V3 against DeepSeek-V2, Qwen2.5 72B, and LLaMA3.1 405B on standard benchmarks. On many English and code benchmarks, DeepSeek-V3 leads. For example, it scores 87.5 on BBH (EM), 87.1 on MMLU (Acc.), and 65.2 on HumanEval (Pass@1), all higher than the dense 405B LLaMA. But it does not win everywhere. On Pile-test (BPB), LLaMA3.1 405B scores 0.542 and DeepSeek-V3 scores 0.548, so the dense model is slightly better at language modeling. On HellaSwag, PIQA, WinoGrande, RACE-Middle, RACE-High, and NaturalQuestions, LLaMA3.1 405B scores higher. RACE-Middle and RACE-High show a clear gap: DeepSeek-V3 scores 67.1 and 51.3, while LLaMA3.1 scores 74.2 and 56.8. That is a meaningful drop in reading comprehension, which is a common need in enterprise text processing. If your workload is heavy on reading comprehension, you should not assume DeepSeek-V3 is the best choice just because it wins on code. The data shows that the model is strong but not universally dominant.
Post-Training: Distillation from DeepSeek-R1
The post-training stage uses knowledge distillation from one of the DeepSeek R1 series models, which are long-Chain-of-Thought (CoT) models. The README says this pipeline incorporates verification and reflection patterns from R1 into DeepSeek-V3, improving reasoning performance while controlling output style and length. The README says the pipeline maintains control over output style and length, so test output length on your own prompts.
Licensing and Maintenance Costs
The repository is licensed under MIT for the code, but the README links to separate LICENSE-CODE and LICENSE-MODEL files. That means the code is freely usable, but the model weights may have a different license. You must read LICENSE-MODEL before using the weights commercially. Do not assume MIT applies to the weights. The project is not archived, but the last push was on 2025-08-28 and the only release is v1.0.0 from 2025-06-27, so do not expect active maintenance. However, the README explicitly states that MTP support is under active development within the community, which is a maintenance risk. If you rely on MTP for speculative decoding, you may need to track community forks or patches. The total download size of 685B is a significant bandwidth and storage cost, and you will need to plan for that. The training cost figures are for the original training, not for fine-tuning on your own data. Fine-tuning a 671B MoE model will still require substantial GPU resources, even if only 37B parameters are active per token.
The Real Alternative: Dense Models Like LLaMA 3.1 405B
The README's own benchmark table includes LLaMA3.1 405B, which is a dense model with 405B total parameters and 405B active per token. That is the direct alternative. The difference in approach is fundamental: dense models activate all parameters for every token, so they have higher compute per token but no routing overhead and no load balancing concerns. DeepSeek-V3 activates only 37B parameters, so it is cheaper per token, but it requires MoE-specific inference infrastructure to handle expert routing. The benchmarks show that LLaMA3.1 405B wins on several language tasks, especially reading comprehension, while DeepSeek-V3 wins on code. If your workload is code generation, DeepSeek-V3 may offer better quality at a lower per-token cost. If your workload is general text understanding or reading comprehension, the dense model may be worth the extra compute. The choice is not just about quality; it is about whether your serving stack can efficiently handle MoE. Dense models are simpler to deploy on standard inference engines.
Editorial conclusion
Adopt DeepSeek-V3 if you need a high-capability open-weight model with a per-token compute cost near 37B parameters and you can handle the 685B total download size. Do not adopt it if you need a small model, if your hardware cannot fit even the active 37B parameters, or if you require guaranteed stability of community MTP tooling. Before committing, verify your inference stack supports the exact FP8 and MLA optimizations the model expects, and check the license files (LICENSE-CODE and LICENSE-MODEL) for any use restrictions beyond the MIT code license.
Frequently asked questions
How big is DeepSeek-V3?
It has 671B total parameters with 37B activated for each token, and both DeepSeek-V3 and DeepSeek-V3-Base are published with a 128K context length. The download is larger than the parameter count suggests.
When was DeepSeek-V3 released?
The repository's only tagged release is v1.0.0, dated 2025-06-27. The last push to the repository is dated 2025-08-28, so the tree has not been updated in over a year.
What are the parameters of DeepSeek-V3?
671B total with 37B activated per token, using Multi-head Latent Attention and the DeepSeekMoE architecture, both validated in DeepSeek-V2. The Hugging Face download totals 685B because it adds 14B of Multi-Token Prediction module weights to the 671B main model.
how to install deepseek v3 locally
Both DeepSeek-V3 and DeepSeek-V3-Base download from Hugging Face, and the project's table of contents has a dedicated How to Run Locally section that it refers readers to for step-by-step guidance. The repository's top level also carries an inference/ directory, and README_WEIGHTS.md covers the main model weights and the MTP modules.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/deepseek-ai-deepseek-v3)Star history chart for your README
[](https://hysenlabs.com/projects/deepseek-ai-deepseek-v3)Was this useful?