DeepSelect: TopK CUDA kernels for DeepSeek Sparse Attention and sampling
DeepSelect: TopK kernels for DeepSeek Sparse Attention (DSA) and Samplers
At a glance
- What is it?
- DeepSelect is a CUDA extension from DeepSeek that replaces torch.topk in two narrow workloads: the Lightning Indexer of DeepSeek Sparse Attention and a sampling path. It is fast where it fits and does not pretend to fit everywhere.
- Who is it for?
- Adopt DeepSelect if your TopK call sits in the Lightning Indexer with bfloat16 input and topk at or below 4096, or in a float32 sampling path with a vocabulary near 128K. Do not adopt it as a general replacement for torch.topk: bfloat16 outside the indexer, large topk and unaligned row strides all fall outside what the README supports.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 47 days ago.
- What is it written in?
- Mainly Cuda, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
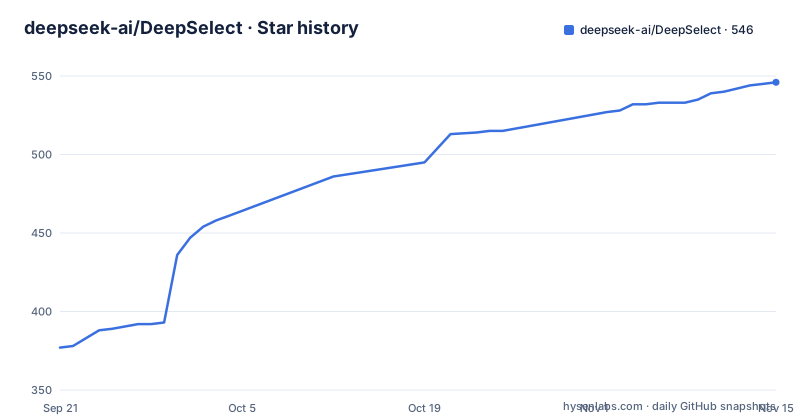
- deepseek-ai/DeepSelect546 ★ · +169
| Repository | 2026-09-21 | 2026-11-15 |
|---|---|---|
| deepseek-ai/DeepSelect | 377 | 546 |
169 Stars in the last 55 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What DeepSelect replaces, and for whom
DeepSeek Sparse Attention needs a TopK selection over a large score tensor before the sparse attention itself runs. The README calls this stage the Lightning Indexer. A second workload is sampling, where the same shape of problem appears: pick the top candidates out of a vocabulary-sized row. Both are memory-bound selections, not arithmetic, and both sit on the critical path of a model forward pass, which is why the generic torch.topk implementation leaves performance on the table.
DeepSelect is written for people who already know their workload matches one of these two shapes. It is a CUDA extension, the primary language of the repository is Cuda, and it is published under the MIT licence. The README is explicit that the project does not try to cover TopK in general: the fastest algorithm depends on input dtype, batch_size, vocab_size and topk, and the repository only focuses on the cases it lists. That narrowness is the design, not an accident.
The two supported cases are the Lightning Indexer, with torch.bfloat16 input, batch_size and vocab_size from 1 to effectively unbounded, and topk small and at most 4096; and sampling, with torch.float32 input, batch_size from 1 upward, a vocab_size around 128K, and the same topk ceiling. If your TopK call does not look like either of those, the README does not claim anything for you.
The stride alignment contract
The most consequential detail in the README is not the speedup claim. It is the alignment rule. The row stride of the input tensor must be a multiple of deep_select.get_stride_requirement()[0] bytes, and the last dimension must be contiguous. The function returns a pair of values, and the second one is the alignment used for the outputs that the call allocates, so those outputs may be non-contiguous.
That rule shapes how you write surrounding code. A tensor sliced or padded in a way that leaves an odd row stride will not be accepted, and the README says padding is necessary for unaligned inputs. If you want to avoid the allocation and write indices into your own buffer, you pass output_idx= and that buffer has to satisfy the same stride requirement. There is no fallback path documented for an unaligned tensor.
The alignment requirement is the kind of constraint that is invisible in a demo and obvious in production. It means DeepSelect cannot be dropped into an arbitrary pipeline as a transparent swap; whoever owns the tensor layout has to agree to the contract. That is a real integration cost, and the README states it plainly rather than hiding it behind a benchmark chart.
Installing DeepSelect and running a first TopK
There are no prebuilt wheels in the README. Installation is from source, and the README gives a four-line sequence that clones the repository, initialises its submodules, and installs with pip. The submodule step matters: the repository has a .gitmodules entry at the top level, and the build pulls CUDA sources from csrc/, so a clone without submodules is not a complete checkout.
git clone https://github.com/deepseek-ai/DeepSelect.git
cd DeepSelect
git submodule update --init --recursive
pip install -v .
The setup.py file shows what the build does. It enumerates a long list of pre-generated CUDA instantiation files under csrc/cuda_kernels/v3/instantiations/, with names that encode the configuration: dtype, output index type, sorted flags, return-value flag, a maxtopk value of 512, 1024 or 4096, thread counts of 256 or 512, occupancy, and tile sizes. Those files are produced by scripts/generate_instantiations.py, so the build compiles a fixed menu of kernel variants rather than specialising at runtime. Expect a long nvcc compile.
Once installed, the call mirrors torch.topk closely enough that the migration is mostly about the keyword arguments.
import torch
import deep_select

batch_size, vocab_size, topk = 4, 204800, 1024
x = torch.randn(batch_size, vocab_size, dtype=torch.bfloat16, device="cuda")

values, indices = deep_select.topk(
    x,
    topk,
    sorted_index=True,
    indices_type=torch.int32,
    return_value=True,
)
The README documents the output shapes: values is (batch_size, topk) in x.dtype, and indices is (batch_size, topk) in indices_type, which may be torch.int32 or torch.int64. The README also recommends leaving sorted_index off unless the output must be ordered by index or by value, and setting return_value=False when the values are not needed, which it says is about 10 percent faster. For the full signature the README points at deep_select/interface.py.
The repository ships a benchmark at tests/test.py, invoked as python3 tests/test.py --perf-only, which reports the ratio against torch.topk on the same input. That is the number to reproduce on your own hardware before trusting any speedup figure, because the README's charts are tied to specific dtypes, batch sizes and topk values.
Variable-length rows and the NaN trap
Two behaviours deserve attention before you ship this. The first is the end argument, which sets a per-row upper bound, exclusive. It is a tensor of shape (batch_size,), and rows shorter than topk are padded with value_oob_fill_value and idx_oob_fill_value. That makes ragged batches expressible without materialising a padded score matrix, which is useful when rows come from different sequence lengths.
batch_size, vocab_size = 2, 129280
x = torch.randn(batch_size, vocab_size, dtype=torch.float32, device="cuda")
end = torch.tensor([129280, 100000], dtype=torch.int32, device="cuda")
values, indices = deep_select.topk(x, 1000, end=end, sorted=True,
                                   indices_type=torch.int64)
The second is NaN handling, and this is the sharpest edge in the project. The README states that NaN checking is always on, that the default abort_when_nan_found=True makes the kernel invoke trap() and abort, and that rows whose length is <= topk are never NaN-checked. A trap is not a Python exception you can catch around the call. A single NaN in a checked row takes down the process. In a training or serving loop where a stray NaN is a symptom rather than a surprise, that default turns a recoverable bad batch into a crash. The README does not describe a way to log and continue instead; it documents the abort behaviour and the exemption for short rows.
The padding rule interacts with this. A row shorter than topk is exempt from the check, so the fill values you choose are what downstream code sees, and they are not validated for you.
Where DeepSelect is the wrong tool
The topk ceiling of 4096 is the first hard boundary. The README says larger values are not supported in both scenarios. If you need a top-10000 over a vocabulary, DeepSelect is not a candidate regardless of how well it performs at 512.
The dtype split is the second. The Lightning Indexer path is bfloat16 and the sampling path is float32, and the README does not present a general dtype matrix. A float16 pipeline, or a bfloat16 sampling path, is outside the documented support. The instantiation file names in setup.py confirm the split: the entries visible there are value_bf16 variants, and the sampling scenario is described separately as float32.
Third, the alignment contract makes DeepSelect a poor fit for code that cannot control tensor layout. If your scores arrive from a library that decides the stride, you either copy into an aligned buffer, which costs a pass over the data, or you give up the speedup. The README's own answer is padding, and padding is work you now own.
Finally, the variable-length path is not a general ragged TopK. The end tensor gives one bound per row, and the padding values are fixed per call. A workload with per-row topk values, rather than a per-row upper bound with a shared topk, is not what this interface expresses.
Against torch.topk and against writing your own
The honest alternative is torch.topk itself. It supports any dtype PyTorch supports, any topk value, arbitrary strides, and it will not abort your process on a NaN. It is also the baseline DeepSelect measures against in tests/test.py, and the README reports a 2 to 20x speedup over it. The difference in approach is that torch.topk must be general: it cannot assume a bfloat16 score tensor from an indexer, cannot assume a 128K vocabulary, and cannot assume the caller will accept an alignment contract. DeepSelect trades all of that generality for a fixed set of compiled kernel variants, selected by the configuration encoded in the instantiation filenames.
The other alternative is your own CUDA kernel. That is a real option for a team already maintaining custom attention kernels, and the repository makes it less attractive by shipping the generator script, scripts/generate_instantiations.py, alongside a deep-dive document in docs/. If you were going to write a TopK kernel anyway, reading the implementation notes first is cheaper than starting from scratch. If you were not, the build complexity here (submodules, a long nvcc compile, a fixed variant list) is the price of not writing one.
A note on the performance claims: the README's charts are tied to bfloat16 with topk = 512 and float32 with vocab_size = 129280 and topk = 512. Those are the configurations the project chose to show. They are not a promise for your shape.
Maintenance, licence and what a fork costs
The repository is not archived, and the last push was on 2026-09-10. The README's news section records that date twice: DeepSelect v1.0.0 was released, and a deep-dive analysis of the algorithm and its implementation was published in English and Chinese under docs/. The repository has no published GitHub releases, so v1.0.0 is the reference point. The project is young, and the version number says so.
The MIT licence is permissive, and for a CUDA extension that links into a training or inference stack, that is usually the licence teams want. It does not settle the question of whether the compiled binary is redistributable in your product, or what your obligations are when you ship a container that bundles it; that depends on your own counsel and on how the rest of your stack is licensed. Nothing here is legal advice.
Upgrade cost is dominated by the build. Because the kernel variants are generated and compiled at install time, moving to a new CUDA toolkit or a new PyTorch version means rebuilding, and the instantiation list in setup.py is part of the source you are rebuilding. A floating-point or interface change in a future version would land in deep_select/interface.py, which the README names as the place to read the full signature. Pin the commit you build against, and re-run tests/test.py --perf-only after any rebuild rather than assuming the ratio holds.
Editorial conclusion
Adopt DeepSelect if your TopK call sits in the Lightning Indexer with bfloat16 input and topk at or below 4096, or in a float32 sampling path with a vocabulary near 128K. Do not adopt it as a general replacement for torch.topk: bfloat16 outside the indexer, large topk and unaligned row strides all fall outside what the README supports. Before wiring it in, print deep_select.get_stride_requirement() and confirm your input row stride is a multiple of the first value, then decide whether sorted_index and return_value can stay off, since the README states that enabling either ordering costs performance and that return_value=False skips the value output.
Frequently asked questions
What topk values does DeepSelect support?
In both the Lightning Indexer and sampling scenarios, the README states that topk must be small and at most 4096, and that larger values are not supported. The compiled kernel variants in setup.py carry maxtopk values of 512, 1024 and 4096.
Which dtypes can I pass to deep_select.topk?
The README documents torch.bfloat16 for the Lightning Indexer scenario and torch.float32 for the sampling scenario. The example input is created with one of those two dtypes, and the README does not describe other dtypes as supported.
Why does DeepSelect abort on NaN?
The README states that NaN checking is always on and that the default abort_when_nan_found=True makes the kernel invoke trap() and abort. Rows whose length is <= topk are never NaN-checked, so short rows are exempt.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/deepseek-ai-deepselect)Star history chart for your README
[](https://hysenlabs.com/projects/deepseek-ai-deepselect)Was this useful?