FlashMLA: DeepSeek's Attention Kernels for V4.1
FlashMLA: Efficient Multi-head Latent Attention Kernels
At a glance
- What is it?
- FlashMLA is DeepSeek's library of dense and token-level sparse attention kernels, aimed at teams running DeepSeek-V4.1 on NVIDIA SM100 / SM103 GPUs or Huawei Ascend 950 NPUs. Hopper support was removed in the 2026.09.30 release.
- Who is it for?
- Adopt FlashMLA if you serve DeepSeek-V4.1 on SM100 / SM103 GPUs or Huawei Ascend 950 NPUs and you are willing to build a CUDA extension against a pinned toolchain. Do not adopt it if your GPUs are older than SM100, or if your model is not in the support matrix, since the kernels encode model-specific head dimensions.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 18 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
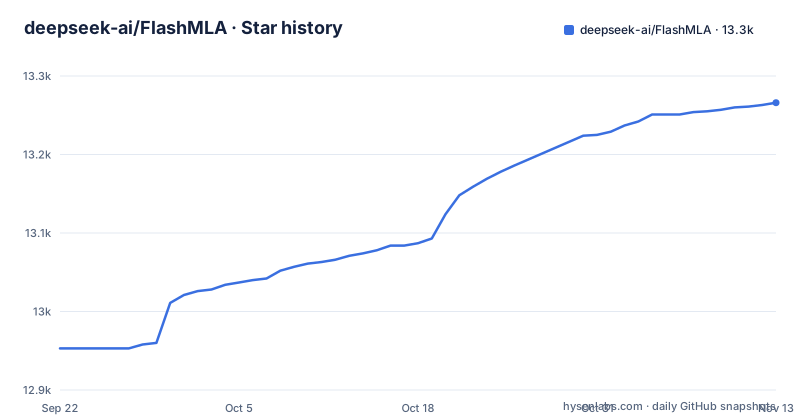
Star history
- deepseek-ai/FlashMLA13,266 ★ · +313
| Repository | 2026-09-22 | 2026-11-13 |
|---|---|---|
| deepseek-ai/FlashMLA | 13k | 13.3k |
313 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What FlashMLA is for, and who should care
FlashMLA is a kernel library, not a model and not a serving framework. Its stated purpose is to provide optimized attention kernels powering inference of the DeepSeek-V4.1 model on NVIDIA GPUs and Huawei Ascend NPUs; the 2026.09.30 release removed support for earlier models including DeepSeek V3, V3.2 and V4.0. The audience is narrow and technical: people who run DeepSeek inference and want the attention step to execute closer to the hardware limit than a generic implementation allows.
The library splits into two families. Sparse attention kernels implement DeepSeek Sparse Attention, as introduced in the V3.2-Exp paper, with token-level sparsity in both prefill and decoding; the decoding variant works with an FP8 / FP4 KV cache. Dense attention kernels cover prefill and backward. If you are not running one of the DeepSeek models named in the support matrix, this library has nothing to offer you, because the kernel shapes are tied to those models' head dimensions.
How the kernels are organized and what the support matrix constrains
The README requirements settle most adoption questions. On NVIDIA it needs an SM100 / SM103 GPU; on Huawei it needs an Ascend 950 NPU. The 2026.09.30 release removed Hopper support and earlier models (including DeepSeek V3 / V3.2 / V4.0), and points anyone who needs them to an older commit. The fused norm RoPE attention RoPE cast kernel and the dense MHA prefill kernel currently support CUDA only, not Ascend.
The repository layout reflects the split: csrc holds the CUDA sources, flash_mla the Python package, tests the benchmark scripts, and docs the deep-dive write-ups, including one on the Hopper FP8 sparse decoding kernel.
Installing FlashMLA and running a first decoding call
A source install clones the repository, initializes submodules, and builds the extension with pip; the README also mentions FlashMLA CUDA wheels.
git clone https://github.com/deepseek-ai/FlashMLA.git flash-mla
cd flash-mla
git submodule update --init --recursive
pip install -v .
On NVIDIA, requirements are an SM100 / SM103 GPU, CUDA 13.1 and above (13.2 and above recommended for the native cvt.rn.bf16x2 conversions), and PyTorch 2.10 and above; on Huawei, an Ascend 950 NPU, CANN 9.2.0 and above, torch_npu and PyTorch 2.10 and above. setup.py builds the architecture-specific targets sm_100a and sm_103a rather than the family-specific sm_100f, because the kernels use cvt with .scaled::n2::ue8m0.
To check a build, the repository ships benchmark scripts you can run directly, for example python tests/test-sparse-decode.py or python tests/test-sparse-prefill.py. The README reports up to 1024 TFlops for sparse decoding on B200 with CUDA 13.3, and 360 TFlops on the Huawei Ascend 950 NPU.
The FP8 KV cache path is sparse-only, and the format is manual
The FP8 story is where the documentation thins out fastest, and it is also where mistakes are expensive. Setting is_fp8_kvcache=True makes the kernel read the cache in what the README calls the FP8 with scale format, dequantize it to bfloat16, run attention in bfloat16, and return bfloat16 output. That is a sensible design: the memory saving comes from storage, not from doing the math in low precision.
The constraint is that in this repository, is_fp8_kvcache=True is only supported together with indices, meaning sparse attention. The 2026.09.30 release changed the FP8 / FP4 KV cache format and is not compatible with previous versions; the old format requires switching to an older commit. Anyone building a cache writer should read the current format section in the repository before writing code, because a mismatch in row stride will produce wrong numbers rather than an error.
Where FlashMLA is the wrong tool
Three cases stand out. First, hardware. The NVIDIA requirements list only SM100 / SM103 GPUs, and the 2026.09.30 release removed Hopper support, so on Hopper or older GPUs the current code has no supported path; the README points those users to an older commit.
Second, portability. These kernels are shaped for DeepSeek's MLA configurations. A model with different head dimensions cannot simply reuse them, and the MQA/MHA split means even within DeepSeek models you must pick the kernel matching the mode your model uses. Third, the current release supports only DeepSeek-V4.1; earlier models including V3, V3.2 and V4.0 need the older commit.
There is also an operational cost: the 2026.09.30 release is not compatible with previous versions, and the documented way back is switching to a specific older commit, so a team that needs reproducible builds has to pin commits itself. The fused kernel adds its own requirement: TileLang, Tile-Kernels and DeepGEMM are needed to run its test script, and the README notes the kernel requires permuting the Q_b and Wv weights in advance.
FlashInfer and the difference in approach
The most natural comparison is FlashInfer. The difference is scope. FlashInfer is a general attention kernel library covering many models, precisions and decoding schemes, so it can serve a heterogeneous fleet without asking you to match a specific model's head dimensions. FlashMLA goes the other way: it is DeepSeek's own kernels for DeepSeek's own models, and the tight coupling is the point. The sparse decoding kernel exists because DeepSeek Sparse Attention needs token-level sparsity and an FP8 / FP4 KV cache, and a general-purpose library has no reason to encode that specific format.
The trade-off is straightforward. Choosing FlashMLA means accepting a narrow support matrix in exchange for kernels tuned to one family of models, with published performance figures on H800 and B200. Choosing FlashInfer means broader coverage and less exposure to a single vendor's release cadence. The repository is not archived and the last push was on 2026-10-27, so it is being updated; that does not tell you anything about whether the kernels fit your model.
Licence, maintenance and what an upgrade costs
FlashMLA is MIT licensed, which is permissive and imposes few obligations beyond retaining the notice. The repository carries a LICENSE file at the top level. Nothing in the README suggests any additional licensing term for the kernels themselves, but the fused kernel's test script pulls in TileLang, Tile-Kernels and DeepGEMM, which are separate projects with their own licences, so a deployment that uses that path should check each one. This is a description of what the repository states, not legal advice.
Maintenance is visible through the release notes. The README lists kernel releases for V3.2 sparse attention in September 2025, MHA kernels on SM100 in August 2025, and DeepSeek V4.1 attention kernels plus the fused kernel in September 2026. The 2026.09.30 release added Ascend attention kernels. The last push to the repository was on 2026-10-27. The upgrade cost is the part worth planning for. The 2025.04.22 note says the new interface was fully compatible with the old one, which is a good sign for that release, but the 2026.09.30 release states it is not compatible with previous versions. Because the package builds against your local CUDA and PyTorch, an upgrade is a recompile.
Editorial conclusion
Adopt FlashMLA if you serve DeepSeek-V4.1 on SM100 / SM103 GPUs or Huawei Ascend 950 NPUs and you are willing to build a CUDA extension against a pinned toolchain. Do not adopt it if your GPUs are older than SM100, or if your model is not in the support matrix, since the kernels encode model-specific head dimensions. Before committing, verify that your CUDA version meets the 13.1 requirement, that your MLA mode (MQA or MHA) matches the kernel you plan to call, and that your serving stack can pass the tile scheduler metadata and indices that the sparse path expects.
Frequently asked questions
How does FlashMLA compare with FlashInfer?
FlashMLA is DeepSeek's own kernel library for DeepSeek models, with a support matrix that names specific GPU architectures, MLA modes and model versions. FlashInfer is a general attention kernel library, so the difference is that FlashMLA trades breadth for kernels tuned to one model family.
What GPU architectures does FlashMLA support?
The README lists NVIDIA SM100 / SM103 GPUs with CUDA 13.1 and above and PyTorch 2.10 and above, and the Huawei Ascend 950 NPU with CANN 9.2.0 and above. Hopper support was removed in the 2026.09.30 release.
Does FlashMLA work with an FP8 KV cache?
Yes. The sparse decoding kernels use an FP8 or FP4 KV cache, and the 2026.09.30 release changed that cache format, so it is not compatible with the old one.
How do I install FlashMLA?
The README clones the repository, runs git submodule update --init --recursive, and then pip install -v . from the repository root. The README also mentions FlashMLA CUDA wheels.
What do I need to compile the SM100 kernels in FlashMLA?
The README requires an SM100 / SM103 GPU, CUDA 13.1 and above (13.2 and above recommended), and PyTorch 2.10 and above; setup.py builds the sm_100a and sm_103a targets.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Jensen is out. CUDA isn't. A Developer's Guide to Everything Nvidia Builtdev.to · Nov 13, 2026 · 7 points · 2 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/deepseek-ai-flashmla)Star history chart for your README
[](https://hysenlabs.com/projects/deepseek-ai-flashmla)Was this useful?