dnhkng/GLaDOS: A Personality Core for a Real-Life Portal AI
This is the Personality Core for GLaDOS, the first steps towards a real-life implementation of the AI from the Portal series by Valve.
At a glance
- What is it?
- dnhkng/GLaDOS is a Python voice assistant that runs a multi-agent loop with vision, memory and MCP tools. Here is how it installs, what it assumes about your hardware, and where it stops being the right tool.
- Who is it for?
- Adopt dnhkng/GLaDOS if you want a proactive, camera-aware voice assistant and you are willing to supply the microphone, speaker and GPU it assumes. Do not adopt it if you need a documented, stable API surface or a wake-word-only assistant, because the README describes proactive responses from an Autonomy Core as the point.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 35 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
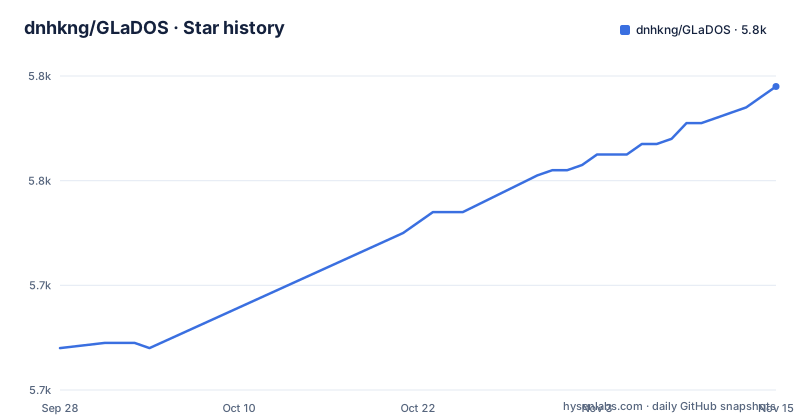
- dnhkng/GLaDOS5,778 ★ · +50
| Repository | 2026-09-28 | 2026-11-15 |
|---|---|---|
| dnhkng/GLaDOS | 5.7k | 5.8k |
50 Stars in the last 48 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What dnhkng/GLaDOS actually solves, and for whom
Most voice assistants are request-response machines. They wait for a wake word, transcribe, answer, and go quiet. The README describes a different design: independent cores publish observations into a shared context, and an Autonomy Core decides when an update deserves a spoken response. The problem it addresses is not speech recognition or text generation, both of which are solved elsewhere. It addresses the orchestration layer between them, where a personality has to stay consistent across sessions, react to a camera feed and a clock, and still let the human interrupt.
The audience is narrow and specific. You need a microphone and speaker, or a browser, and the installer selects CUDA when available, an installed ROCm backend otherwise, or CPU. The pyproject.toml offers onnxruntime-gpu and onnxruntime as mutually exclusive extras, which tells you the author expects you to pick a side.
This is a maker project with a fictional character as its specification. If you want a general assistant, the personality layer is overhead. If you want a machine that comments on your posture while you work, the personality layer is the product.
The Society of Mind loop behind the personality
The README describes a conversational model combined with independent cores for emotion, memory, vision, system health and research. Their observations feed a shared context, and an Autonomy Core decides when an update deserves a spoken response.
Independent cores publish evidence for the Autonomy Core to review, and user interactions take priority over new background inference.
In the default profile, audio goes directly to Gemma 4 E4B and Parakeet is not loaded; the extended profile uses Parakeet TDT transcription and sends text to Ollama or an OpenAI-compatible API. Vision uses E4B to describe the current scene and recent changes from timestamped images, with observation timing adapting to motion within a default range of 2–5 seconds.
A separate Emotion Core maintains pleasure, arousal and dominance, while spoken emotion directions move the browser avatar.
Installing dnhkng/GLaDOS and getting a first response
The project declares Python 3.12 or newer and ships a glados console script. The Dockerfile shows the intended flow: install uv, sync with the api and cpu extras, then run a download step to fetch models. That download step is the part people miss, because the models/ directory is copied into the image before the sync.
RUN uv sync --extra api --extra cpu --no-dev \
  && uv run glados download
For a local install, the README runs an installer from a checkout that creates a Python 3.12.8 environment, installs GLaDOS and downloads the local ONNX speech models. The optional extras matter: cuda and cpu select the ONNX runtime, tiktoken is separate, and export pulls in nemo_toolkit for ASR work.
git clone https://github.com/dnhkng/GLaDOS.git
cd GLaDOS
python scripts/install.py
The conversation model runs in a separate server: download the two Gemma 4 E4B GGUF files into models/gemma4-benchmark/, run bash scripts/run_llamacpp.sh, then start the web console with uv run --no-sync glados webapp --config configs/glados_webapp_config.yaml and open http://127.0.0.1:8050/.
The Docker path exposes a service instead of a local loop. The compose file maps a single port, defaulting to 5050.
services:
  app:
    build: .
    ports:
      - '${PORT:-5050}:5050'
The container command runs Litestar against glados.api.app:create_app on 0.0.0.0:5050, so this route is for driving GLaDOS over HTTP rather than sitting at the machine. There is also examples/audio_websocket_client.py in the repository; read that example file before writing your own client.
Where the design assumptions bite
The README says latency and memory use depend on your machine and enabled cores, and points to docs/gemma4.md for model setup, measured results, hardware and context capacity details.
Proactive behavior is the second constraint, and it is a social one rather than a technical one. A system that speaks when it has an opinion is harder to live with than a wake-word assistant.
Finally, this is the wrong tool if you need a stable integration surface. The project has one release, 0.1 from 2024-12-29, and the last push was on 2026-10-11, so the code is moving, but the version number tells you the API is not frozen.
How it differs from a Home Assistant voice pipeline
The obvious comparison is a Home Assistant voice setup with Whisper and Piper. The difference is in the control flow. A Home Assistant pipeline is intent-driven: you say something, an intent is matched, an action fires, and the assistant stops. GLaDOS inverts that. The autonomy lane runs whether or not you spoke, subagents keep writing into context, and the Autonomy Core decides whether to produce output.
That inversion changes what the tool is good at. Home Assistant is reliable because its scope is bounded and its intents are testable. GLaDOS is interesting because its scope is deliberately unbounded: the README lists performing requested internet research among its abilities. You cannot write a regression test for that.
The tool-use story is also different. GLaDOS uses MCP, and the pyproject.toml pins mcp>=1.25.0,<2.0.0. The README says it can connect MCP services, including Home Assistant, and use native controls for preferences, memory, tasks and allowlisted system commands. So GLaDOS can sit in front of Home Assistant through MCP rather than replace it.
If your goal is a dependable voice front end for a smart home, the Home Assistant route has more documentation and a narrower failure surface. If your goal is a character that inhabits a room, the loop here is the reason to pick it.
Licence, upgrades and what maintenance costs you
The repository is MIT licensed, with the licence text in LICENSE.txt. That is permissive and unsurprising for a project of this kind. The practical implication is not legal but operational: the ONNX speech models the installer downloads and the Gemma 4 GGUF files you fetch from Hugging Face are separate artifacts. Check those before you ship anything built on top of this, and do not treat the MIT file as covering them.
Upgrade cost is driven by models and runtimes. The README says to rerun the installer to update or switch the backend; it preserves the environment and replaces the old ONNX distribution before installing the selected one. The dependency list is broad, spanning sounddevice, opencv-python, textual, numba, pydantic and mcp, so a Python upgrade or an ONNX runtime bump can move several of those at once.
The project pins requires-python to >=3.12 and targets py312 in the Ruff configuration. That is a recent floor, which reduces the chance of running on an older distribution but also means you are tracking a moving interpreter target. If you deploy this, keep the previous working set of model files alongside the new one.
Editorial conclusion
Adopt dnhkng/GLaDOS if you want a proactive, camera-aware voice assistant and you are willing to supply the microphone, speaker and GPU it assumes. Do not adopt it if you need a documented, stable API surface or a wake-word-only assistant, because the README describes proactive responses from an Autonomy Core as the point. Before you build anything on it, check the pyproject.toml dependencies and the models/ directory to confirm which model weights your machine can actually run.
Frequently asked questions
What is dnhkng/GLaDOS?
It is a Python personality core for a real-life implementation of GLaDOS from Valve's Portal series, described in the README as a voice assistant with GLaDOS's custom voice, dry humour, camera observations, persistent memory and tools.
What is the personality of dnhkng/GLaDOS based on?
The README says a separate Emotion Core maintains pleasure, arousal and dominance, and that the conversational model is combined with independent cores for emotion, memory, vision, system health and research whose observations feed a shared context.
How do I install dnhkng/GLaDOS?
The Dockerfile installs uv, runs uv sync with the api and cpu extras, then runs uv run glados download to fetch models before starting the service on port 5050. A local install from a checkout runs python scripts/install.py, and the conversation model runs in a separate llama.cpp server.
What hardware does dnhkng/GLaDOS need?
The pyproject.toml offers cuda and cpu extras for onnxruntime, so a GPU is optional but supported. The installer selects CUDA when available, an installed ROCm backend otherwise, or CPU, and the reference setup uses a CUDA build of llama.cpp with Gemma 4 E4B.
Does dnhkng/GLaDOS need a wake word?
The README describes proactive responses: independent cores publish evidence for an Autonomy Core, which decides when an update deserves a spoken response, and user interactions take priority over new background inference.
What is still missing from dnhkng/GLaDOS?
The README says macOS support remains experimental, AMD model performance still needs hardware validation, and the installer does not supply an Intel runtime.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/dnhkng-glados)Star history chart for your README
[](https://hysenlabs.com/projects/dnhkng-glados)Was this useful?