Atomic Agents: a Pydantic-typed agent framework built on Instructor
Building AI agents, atomically
At a glance
- What is it?
- Atomic Agents is a Python library that wraps Instructor and Pydantic to give each agent a typed input and output schema. It suits engineers who want predictable, testable LLM calls rather than autonomous multi-agent behaviour, and the README is explicit that autonomy is not the goal.
- Who is it for?
- Adopt Atomic Agents if your team already writes Pydantic models and wants each LLM call to return a validated object rather than free text. Skip it if you need agents that decide their own control flow, since the framework is organised around pipelines you compose yourself.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
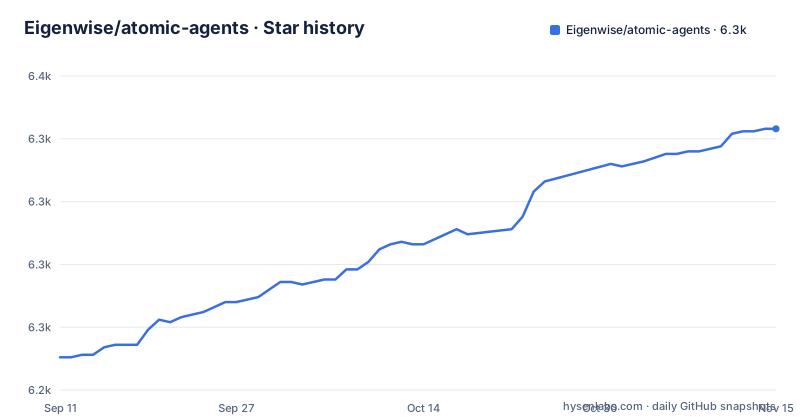
- Eigenwise/atomic-agents6,329 ★ · +91
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| Eigenwise/atomic-agents | 6.2k | 6.3k |
91 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem Atomic Agents picks: typed outputs instead of free text
Most agent frameworks in this space are built for autonomy. You give them a goal, they decide which tools to call and when to stop. The README states the opposite concern directly: existing frameworks "often lack the control and predictability required for real-world applications," and businesses need systems that produce "consistent, reliable outputs." That sentence is the whole pitch. Atomic Agents is for the engineer who has already decided the control flow and now wants each step to return a validated Python object instead of a string they have to parse.
The target user is fairly narrow. You need to be comfortable with Pydantic, because every input and output schema in the framework is a Pydantic model. You need to be comfortable with Instructor, because that is what the library is built on. If neither name means anything to you, this is probably not the framework to learn first. The README frames the design as "building AI applications with LEGO blocks," where each component is single-purpose, reusable, composable and predictable. That is a description of a library, not a platform.
How an agent is assembled: config, schemas, prompt generator, history
The quick example in the README is the clearest description of the mechanism. You define an output schema by subclassing BaseIOSchema and declaring fields with Pydantic's Field, including a description string for each. The example then sets up a system prompt with SystemPromptGenerator, and imports OpenAI, instructor, AtomicAgent, AgentConfig, BasicChatInputSchema and ChatHistory to assemble the agent.
The output schema's fields, chat_message and suggested_questions, are typed Pydantic fields with descriptions rather than free text. Instructor sits underneath, and Atomic Agents layers the agent abstraction, prompt generation and history on top.
Installation and the provider extras you actually need
The install is two steps, and the second one is easy to forget. First:
pip install atomic-agents
Then the provider SDK, which the README says is available as Instructor extras. The examples given are instructor[groq], instructor[anthropic] and instructor[google-genai]. OpenAI is included by default, which is why the quick example never installs anything else. The README points to the Instructor documentation for the full provider list rather than reproducing it, so the set of supported providers is defined upstream, not by this project.
That dependency arrangement has a practical consequence. Your provider support is tied to Instructor's integration list, and a new provider appears here only after Instructor supports it. It also means an Instructor release can change behaviour inside your agent without an Atomic Agents version bump. The project's own release cadence shows v2.13.1, v2.14.0 and v2.15.0 landing within three days of each other in October 2026. Frequent releases are normal for a young library, but they also mean you should pin versions in your own requirements file rather than tracking latest.
The README also mentions that the install brings in a CLI called Atomic Assembler, described as able to "download Tools (and soon also Agents and Pipelines)." The word soon is doing real work in that sentence. As of the README, only tools are downloadable, so if your plan depends on pulling prebuilt agents or pipelines from a registry, that part is not there yet.
Context providers and schema chaining: the composition story
Two sections of the README carry the composition model: Context Providers, and Chaining Schemas and Agents. Context providers are listed alongside agents and tools as one of the three component types. A context provider is a class that inherits from BaseDynamicContextProvider and implements get_info(), which returns a string injected into the agent's system prompt at runtime.
Chaining is where the typed-schema design pays off most clearly. Because each agent has a declared input schema and a declared output schema, connecting two agents means feeding one agent's output model into the next agent's input model. That is a normal function composition problem, and it is the reason the README can claim reusability: an agent with a stable output schema does not care what consumes it. The cost is that you must design those schemas up front. Changing a field name in an intermediate schema means touching every agent downstream of it. In a pipeline of five agents, that is five schemas to keep coherent.
This is the honest trade-off of the whole framework. You buy compile-time-ish confidence about data shapes and you pay in schema maintenance. Teams that prototype quickly and change their data model weekly will find that overhead heavier than the benefit.
Where Atomic Agents is the wrong tool
The framework is explicitly not built for autonomous multi-agent systems, and the README says so as part of its positioning. If your requirement is an agent that decides which of twenty tools to call, retries on failure, and recursively spawns sub-agents, Atomic Agents gives you the primitives (agents, tools, context providers, schemas) but not the autonomy layer. You would be writing that loop yourself.
Beyond the quick example, the README's table of contents lists sections on Core Concepts, Context Providers, Chaining Schemas and Agents, Provider and Model Compatibility, and Version 2.0 key changes, and the Context Providers section includes its own code example.
A third consideration is the v2.0 break. The README has a section headed "Upgrading from v1.x" with a warning marker, which means the upgrade path is not a drop-in. If you find older tutorials or examples, check which major version they target before copying code.
How it compares to LangChain-style orchestration
The natural comparison is a general-purpose orchestration framework such as LangChain. The difference in approach is not about features, it is about where the abstraction sits. LangChain-style frameworks provide chains, memory abstractions, retrievers and agent executors as a broad toolkit, and you assemble a system from many optional pieces. Atomic Agents provides a much smaller surface: an agent with typed input and output, a prompt generator, a chat history, and the notion of context providers and tools as separate components.
Concretely, in a LangChain-style setup the output of a step is often a string or a dict that you hand to a parser, and the parser is a separate object you configure. In Atomic Agents each agent declares its input and output schema, and the parsing is Instructor's job. That difference shows up in your test suite. With typed outputs you can assert on fields of a returned model, and you can construct fake outputs for tests without going through the model at all. With string outputs you write parsing tests as well as behaviour tests.
The cost of the smaller surface is that you get fewer batteries. If you need a document loader, a vector store integration and a retriever in one import, you will be adding those libraries yourself. Atomic Agents is closer to a well-typed HTTP client for LLMs than to an application framework.
Licence, maintenance and what to verify before adopting
The project is MIT licensed. That is a permissive licence, and it is worth noting that it covers this repository's code, not the providers you call or the Instructor dependency. Instructor and Pydantic carry their own licences, and your use of OpenAI, Anthropic, Groq or Google models is governed by those vendors' terms, not by this MIT grant. Nothing here is legal advice, and if you are shipping in a regulated context you should have someone read the dependency licences rather than the top-level one.
Maintenance signals are positive but limited. The repository is not archived, the last push was on 2026-10-29 and the latest release, v2.15.0, on 2026-10-21, and the README links to CI workflows for docs and code quality. A Discord server and a subreddit are listed as support channels. The v2.0 upgrade warning suggests that major versions do carry breaking changes, so treat the version number as meaningful.
Before adopting, verify three things against the live repository rather than this description. First, whether Atomic Assembler has gained the agent and pipeline downloads the README promises. Second, whether the provider you need appears in Instructor's integration list, since that is what determines support here. Third, whether the v2.0 migration notes match your existing code if you are upgrading rather than starting fresh. Each of those is a fact you can check in a few minutes, and each of them changes the answer to whether this framework fits.
Editorial conclusion
Adopt Atomic Agents if your team already writes Pydantic models and wants each LLM call to return a validated object rather than free text. Skip it if you need agents that decide their own control flow, since the framework is organised around pipelines you compose yourself. Before committing, check the v2.0 migration notes against your codebase, confirm the model string and provider extra you intend to use, and read the Atomic Assembler CLI source rather than trusting the README's 'soon also Agents and Pipelines' note.
Frequently asked questions
What is Atomic Agents?
It is a lightweight, modular Python framework for building agentic AI pipelines and applications, built on Instructor and Pydantic. An agent is assembled from a system prompt, an input schema, an output schema, a history slot, and context providers that inject text into the prompt at runtime.
Are Atomic Agents good?
The checkable facts are these: the package classifies itself as Development Status :: 4 - Beta, is MIT licensed, requires Python 3.12 or newer, and was last tagged v2.15.0 on 2026-10-21. The framework argues its own case through predictability, with explicit input and output schemas per agent.
What are the four types of agents?
This framework does not enumerate four types. It names five parts of an agent: system prompt, input schema, output schema, history, and context providers. What it calls single-purpose, reusable, composable and predictable are properties of any component, whether an agent, a tool or a context provider.
How do Atomic Agents compare with LangChain, CrewAI and AutoGen?
The README makes no feature-by-feature comparison. It says existing frameworks for agentic AI focus on building autonomous multi-agent systems and often lack the control and predictability needed for real-world applications, and that all logic and control flows in this framework are written in Python.
How does Atomic Agents compare with Agno?
Nothing in the repository compares the two. What the project states about itself is that it is MIT licensed, built on Instructor and Pydantic, requires Python 3.12 or newer, and depends on instructor>=1.17.0,<2.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/eigenwise-atomic-agents)Star history chart for your README
[](https://hysenlabs.com/projects/eigenwise-atomic-agents)Was this useful?