Evidence: SQL and Markdown Reports That Compile to a Static Site
Business intelligence as code: build fast, interactive data visualizations in SQL and markdown
At a glance
- What is it?
- Evidence is an MIT-licensed TypeScript tool that turns SQL queries and markdown pages into interactive reports you can self-host. The pitch is business intelligence as code, and the README is short enough that the interesting questions sit in the parts it leaves out.
- Who is it for?
- Adopt Evidence if your team already keeps SQL in version control and wants dashboards that live in the same repository, and if you are willing to treat the CLI as the interface. Do not adopt it if you need a governed semantic layer or a point-and-click builder for non-technical authors, because the README describes neither.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
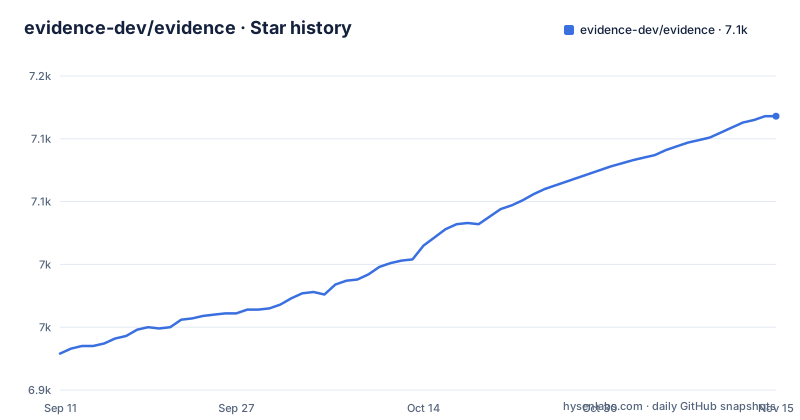
- evidence-dev/evidence7,118 ★ · +189
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| evidence-dev/evidence | 6.9k | 7.1k |
189 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem Evidence Targets: Dashboards That Live in Git
Drag-and-drop BI tools keep the report inside the tool. The query, the layout and the formatting live in a vendor's database, and the only way to review a change is to open the tool. Evidence inverts that. The repository describes the project as an open-source, code-based alternative to drag-and-drop business intelligence tools, and the README's first bullet is the whole design: create reports in code using SQL and markdown. The audience follows from that. It is for analysts and data engineers who already write SQL and already use git, and who would rather review a dashboard change as a diff than as a screenshot. It is a poor fit for someone whose job is to hand a non-technical colleague a builder canvas, because the README does not describe one. The second audience is newer and worth naming: the README says you can develop using Evidence's Agent, or on your local machine with Claude Code or Cursor. That places the project in the camp of tools designed to be edited by coding agents as much as by people.
What Actually Runs: SQL, Markdown, and a Build Step
The README does not document an architecture, so the mechanism has to be read off the surface. The inputs are SQL and markdown. The output, per the publish section, is a generated static site: you either publish on Evidence Studio for hosted reports, or self-host the generated static site on your own infrastructure. That single sentence is the most consequential technical fact available, because it means the report is a build artifact rather than a live application querying a warehouse on every page load. The release feed confirms that connectors are shipped as separate versioned packages rather than baked into one binary. The most recent releases listed are @evidence-dev/evidence, @evidence-dev/csv and @evidence-dev/sqlite, each on its own version number. So the practical picture is a monorepo of npm packages, one per data source plus shared runtime pieces, assembled by a CLI. Anything beyond that, such as how queries are cached at build time or how the WASM layer is used, is not stated in the README.
Installing and Scaffolding: The Three Commands That Matter
The install path is a shell script piped to sh on macOS and Linux, and a PowerShell equivalent on Windows. The README gives both verbatim: curl -fsSL https://evidence.studio/install.sh | sh followed by evidence help, and irm https://evidence.studio/install.ps1 | iex followed by evidence help. Piping a remote script into a shell is a normal pattern for developer CLIs and it is also a supply-chain decision, so on a managed machine you may want to read the script before running it. Project creation is three commands: evidence init my-project, then cd my-project, then evidence dev. The init step is where a data source would be wired up, though the README does not show that step or name any configuration keys, so I cannot tell you what the generated config file is called or what it contains. That gap matters more than it looks. The release feed shows csv and sqlite connector packages, but the README never explains how a project points at a warehouse. If you are evaluating this, the first thing to do after evidence init is open the generated project and read its config, because that is where the connector story actually lives.
Two Publish Paths and the Trade-off Between Them
Evidence offers hosted and self-hosted publishing, and they are not equivalent. Evidence Studio gives you hosted reports, which is the low-effort path and the one the README leads with. Self-hosting means taking the generated static site and serving it from your own infrastructure. The self-hosted route is the reason a team with data residency constraints would look at this project at all, and it is also the route with the least documentation. A static site is easy to serve and hard to permission. There is no mention of row-level security, user authentication, or per-viewer filtering anywhere in the README. If your reports contain anything that not every viewer should see, the static export model means access control is a property of the host and the network, not of the report. That is a real constraint, not a nitpick, and it is the kind of thing that gets discovered late when a dashboard is moved from a laptop to a shared URL.
Where the README Stops Being Useful
The documentation gaps are consistent enough to be a pattern. There is no supported data source list in the README, only csv and sqlite packages in the release feed. There is no configuration reference. There is no description of how the build handles a slow query, a failed connector, or a schema change, which are the three things that break a build-time report pipeline in practice. There is no versioning or upgrade guidance beyond the existence of independently versioned packages. The README points to docs.evidence.studio and a Slack channel, so the assumption is clearly that the real documentation lives elsewhere. That is a reasonable choice for a project of this shape, but it means the README alone is not enough to decide whether Evidence fits your warehouse. The release cadence visible in the feed is also worth reading carefully: the three most recent releases are all dated 2026-02-06, which suggests coordinated package bumps rather than a single product release, so pinning versions across the @evidence-dev scope is likely to matter more here than in a project that ships one artifact.
How Evidence Differs From a Semantic-Layer BI Tool
The obvious comparison is a warehouse-native BI tool that sits on top of a semantic model, where metrics are defined once and every chart references that definition. Evidence's approach is the opposite by default: the SQL is in the report file, next to the markdown that frames it. The difference shows up when two reports need the same number. With a semantic layer, you change the definition and both reports move. With SQL in the page, you either duplicate the query or find some other way to share it, and nothing in the README describes a shared metric layer. If your team does not already run dbt or something like it, the SQL-in-markdown model will drift toward copy-pasted queries faster than a semantic-layer tool would.
Licence, Maintenance, and Upgrade Cost
The licence is MIT, stated in the README and confirmed by the repository metadata. MIT is permissive: you can use, modify and redistribute the code, including in commercial settings, provided the copyright notice and licence text are preserved. That is the general shape of the licence and not legal advice; if you are embedding Evidence in a product, have counsel read the LICENSE file. The maintenance picture is more interesting than the licence. Because the tool is published as a set of scoped packages with independent version numbers, an upgrade is not one decision. The feed shows @evidence-dev/evidence at 40.1.8, @evidence-dev/csv at 1.0.16 and @evidence-dev/sqlite at 2.0.9, all released on the same day. A main-package update and connector patches can arrive together, and the connector's compatibility with the runtime is something you would need to verify per upgrade. The practical cost is that someone on the team has to own the dependency graph, not just the report content. The compensating factor is that the output is a static site, so a broken upgrade is caught at build time rather than in front of a viewer.
Who Should Adopt Evidence, and What to Check First
Adopt it if your analysts write SQL, your team reviews changes through pull requests, and you want the report to be a build artifact you can host yourself. The MIT licence and the static output make it easy to reason about where the data ends up. Do not adopt it if you need a governed metric layer, per-user permissions, or a drag-and-drop authoring surface, because the README describes none of those and the static publish model actively works against the second one. If you are on the fence, the cheapest test is to run evidence init, open the generated project, and read the config file to see which connector it wires up by default. That single file will tell you more about fit than the rest of the README does, because the connector list is the boundary of what Evidence can actually query.
Editorial conclusion
Adopt Evidence if your team already keeps SQL in version control and wants dashboards that live in the same repository, and if you are willing to treat the CLI as the interface. Do not adopt it if you need a governed semantic layer or a point-and-click builder for non-technical authors, because the README describes neither. Before committing, verify three things against your own data: that a connector exists for your warehouse, that the self-hosted build output fits your deployment target, and that the generated site is acceptable to whoever owns data access, since a static export is only as private as the host you put it on.
Frequently asked questions
How do I install the Evidence CLI on Linux or macOS?
The documented install pipes a script into your shell with curl -fsSL https://evidence.studio/install.sh | sh, then run evidence help. Windows uses irm against install.ps1 piped into iex. The README does not describe a version pin, checksum or offline install.
Where can an Evidence project be published?
Either on Evidence Studio for hosted reports, or by self-hosting the generated static site on your own infrastructure. The README refers you to the publishing documentation for the available options.
Do I need a database connection to build an Evidence report?
Reports are created in code using SQL and markdown, so queries need a data source to run against. The README does not walk through choosing or configuring that source, and points at docs.evidence.studio instead.
Which package manager does the Evidence repository use?
The root package.json is private, sets module type, and pins pnpm 9.15.0 as its package manager. Scripts address the workspace packages by filter, and the evd script runs the CLI entry point with Bun.
What do the recent Evidence GitHub releases cover?
The three most recent releases are scoped packages: @evidence-dev/evidence 40.1.8, @evidence-dev/csv 1.0.16 and @evidence-dev/sqlite 2.0.9, all published on 2026-02-06.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/evidence-dev-evidence)Star history chart for your README
[](https://hysenlabs.com/projects/evidence-dev-evidence)Was this useful?