exo: Stitching Macs Into a Local AI Cluster With RDMA Over Thunderbolt
Run frontier AI locally.
At a glance
- What is it?
- exo turns multiple Apple Silicon devices into one distributed inference box, using MLX and topology-aware sharding. The headline feature is day-0 RDMA over Thunderbolt 5, which cuts inter-device latency dramatically, but the RDMA feature needs macOS Tahoe 26.2 or later.
- Who is it for?
- Adopt exo if you own multiple Apple Silicon Macs, especially high-memory Apple Silicon Macs like the M3 Ultra Mac Studios in the README's cluster, and need to run models larger than one device can hold, or want faster inference via RDMA over Thunderbolt 5. On Linux, exo runs from source, and pyproject.toml defines mlx-cpu, mlx-cuda12 and mlx-cuda13 extras.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 9 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
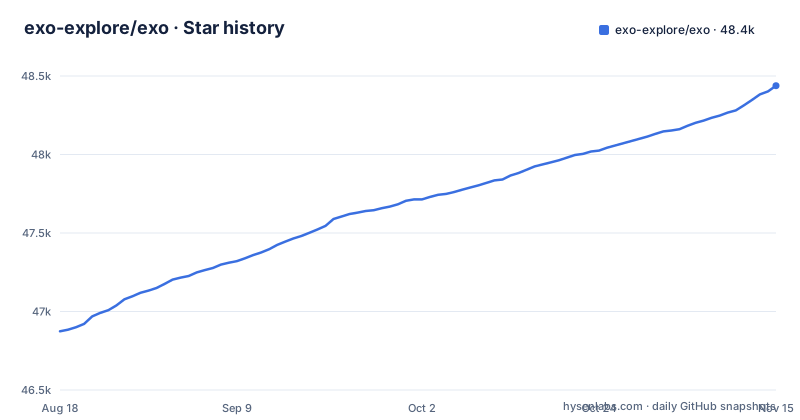
- exo-explore/exo48,438 ★ · +1,564
| Repository | 2026-08-18 | 2026-11-15 |
|---|---|---|
| exo-explore/exo | 46.9k | 48.4k |
1,564 Stars in the last 89 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem: Single-Device Memory Limits
Frontier models like DeepSeek v3.1 671B exceed the unified memory of even the most expensive Mac Studio. You could rent cloud GPUs, but that means shipping data out and paying per hour. exo takes the opposite route: it pools the memory and compute of the devices you already own. The README shows a cluster of four 512GB M3 Ultra Mac Studios running DeepSeek v3.1 (8-bit) and Kimi-K2-Thinking (4-bit). That is 2TB of unified memory across four machines. The target user is someone with multiple high-end Macs, or access to them, who wants local inference without cloud dependency. It is not for a single laptop user, unless that laptop is one node in a larger collection.
How exo Distributes Models: Topology-Aware Auto Parallel
exo does not just shard a model round-robin across devices. It builds a real-time view of the device topology, including each device's resources and the network latency and bandwidth between every link. Then it decides how to split the model. This is the core mechanism: topology-aware auto parallelization. The README also mentions tensor parallelism, with claims of up to 1.8x speedup on two devices and 3.2x on four. Those numbers come from the project's own material, not from an independent test, so treat them as vendor claims. The distributed communication runs through MLX distributed, which is part of Apple's MLX framework. MLX is Apple's array framework, though pyproject.toml also defines mlx-cpu, mlx-cuda12 and mlx-cuda13 extras for Linux. The result is a system that treats your home network as a single GPU, but only if that network is fast enough.
RDMA Over Thunderbolt: The Killer Feature and Its Catch
The most distinctive part of exo is day-0 support for RDMA over Thunderbolt 5. RDMA, remote direct memory access, lets one device read another device's memory without involving the CPU or OS on the receiving side. The README claims a 99% reduction in latency between devices. That is a huge claim, and it is sourced from the project's own announcement, not a peer-reviewed benchmark. The catch is in the setup: the README says RDMA over Thunderbolt needs macOS Tahoe 26.2 or later, which means you need a recent macOS version, and you likely need Thunderbolt 5 hardware on both ends. If you have older Macs with Thunderbolt 3 or 4, you get the automatic discovery and network-based sharding, but you lose the headline latency reduction.
Getting Started: Commands and Prerequisites
The README offers three ways to run exo: the macOS app (the easiest way on a Mac, needing Apple silicon and macOS Sequoia 15.1 or later), Homebrew with `brew install --cask exo`, or from source on macOS or Linux. Each device provides an API and a dashboard at `http://localhost:52415`, and devices on the same network running the same version of exo find each other automatically. The justfile builds the dashboard with `npm install` and `npm run build` inside the dashboard directory and syncs Python dependencies with `uv sync --all-packages --extra mlx`; on Linux, pyproject.toml defines mlx-cpu, mlx-cuda12 and mlx-cuda13 extras.
API Compatibility: Bring Your Own Client
Once exo is running, each device exposes an API and a dashboard. The API is compatible with several existing protocols: OpenAI Chat Completions, Claude Messages, OpenAI Responses, and Ollama. That means you can point existing tools at `http://localhost:52415` and they should work without modification. This is a practical advantage. You do not need a new client or a custom SDK. The README also mentions custom model support from the Hugging Face hub, which expands the range beyond the default set. The API compatibility is a strong reason to try exo, because it lowers the switching cost.
Limitations: macOS Focus, Setup Complexity, and the RDMA Requirement
The most obvious limitation is the platform focus. The README's quick start leads with a macOS app that needs Apple silicon and macOS Sequoia 15.1 or later. Running from source is possible on Linux too, and pyproject.toml defines mlx-cpu, mlx-cuda12 and mlx-cuda13 extras. Another limitation is the RDMA feature's hardware requirement. Without Thunderbolt 5 and macOS 26.2, you lose the 99% latency reduction, and the performance gains from tensor parallelism will be lower. If you have a single Mac, exo offers no benefit over running MLX directly. If your devices are on a slow Wi-Fi network, the auto-parallelizer will see high latency and may split the model poorly, or you may get worse performance than running on one device.
Alternatives: MLX Direct, Ollama, and Distributed Inference Projects
The closest alternative is to run MLX directly on each Mac without clustering. That is simpler and works for models that fit on one device, but it does not solve the memory problem. Ollama is another alternative. It runs models locally with a simple API, but it does not pool memory across devices. For distributed inference, there are other projects like llama.cpp's RPC backend, but they use a different communication mechanism, typically TCP sockets, and do not have RDMA over Thunderbolt support. The key difference is that exo is built specifically around MLX and Apple's ecosystem, so it can exploit Thunderbolt's low latency. A generic distributed inference framework that works over Ethernet will not give you the same speed on a Thunderbolt network. If you do not have Apple hardware, those other projects may be more portable. The choice depends on your hardware and whether you need the low-latency link.
Maintenance and Licensing
The project is under Apache-2.0, which is permissive. You can modify and redistribute it, even for commercial use, as long as you preserve the license notice. The repository shows active development, with releases v1.0.69, v1.0.70, and v1.0.71 coming in March and April 2026. The newest of these is dated 2026-04-23, while the last push was 2026-11-02. If you build from source, the dashboard build with npm is a separate step, so upgrades may require rebuilding it. Overall, the maintenance cost is moderate to high, especially if you build from source.
Editorial conclusion
Adopt exo if you own multiple Apple Silicon Macs, especially high-memory Apple Silicon Macs like the M3 Ultra Mac Studios in the README's cluster, and need to run models larger than one device can hold, or want faster inference via RDMA over Thunderbolt 5. On Linux, exo runs from source, and pyproject.toml defines mlx-cpu, mlx-cuda12 and mlx-cuda13 extras. Before adopting, verify that your macOS version supports RDMA (the README points to a section for macOS >=26.2), that your model is available on Hugging Face or in the supported formats. If you build from source, note that pyproject.toml requires Python 3.13.
Frequently asked questions
What is exo used for?
exo connects multiple devices into an AI cluster so a model larger than one machine can run across them, and each device serves an API and dashboard at http://localhost:52415. It shards the model based on a realtime view of device resources and the latency and bandwidth of each link.
What is exo for AI?
The inference backend is MLX, with MLX distributed handling communication between devices, and the API is compatible with the OpenAI Chat Completions, Claude Messages, OpenAI Responses and Ollama APIs. Custom models load from the HuggingFace hub.
What is the software EXO?
It is a Python and Rust cluster runtime whose entry point is the exo script mapping to exo.main:main, with the Rust side exposed through the exo-rs bindings and pyinstaller used to package the binary. The project is licensed Apache-2.0 and maintained by exo labs.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/exo-explore-exo)Star history chart for your README
[](https://hysenlabs.com/projects/exo-explore-exo)Was this useful?