Segment Anything: A Promptable Segmentation Model with a Clear Ceiling
GitHub describes it as The repository provides code for running inference with the SegmentAnything Model (SAM), links for downloading the trained model checkpoints, and example notebooks that show how to use the model.. The repository metadata lists Jupyter Notebook as its primary language. The metadata lists the Apache-2.0 license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- Meta's Segment Anything Model (SAM) turns segmentation into a prompt-driven task, but this repository is now a frozen snapshot. Here is what it does, how to run it, and where its limits are.
- Who is it for?
- Adopt SAM if you need a single model that can segment objects from point or box prompts without task-specific fine-tuning; evaluate accuracy on your images, and if you are willing to pin PyTorch versions and manage checkpoints manually. Do not adopt it if you need video segmentation or a maintained codebase, because SAM 2 is the successor and this repo is effectively frozen.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Probably not. The repository last received commits 26 months ago, on September 18, 2024.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
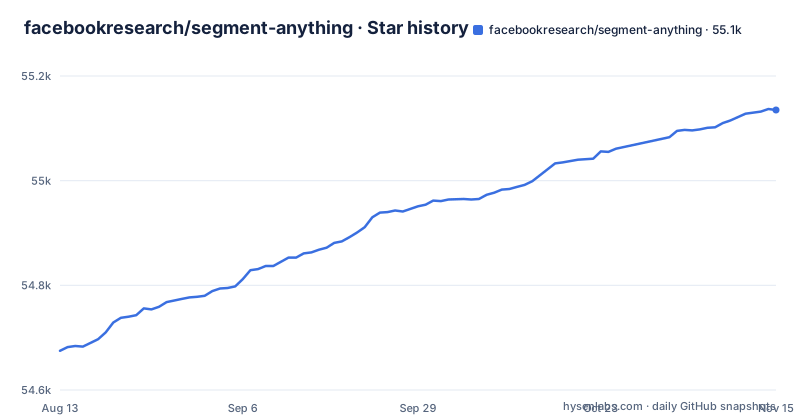
Star history
- facebookresearch/segment-anything55,135 ★ · +460
| Repository | 2026-08-13 | 2026-11-15 |
|---|---|---|
| facebookresearch/segment-anything | 54.7k | 55.1k |
460 Stars in the last 94 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem SAM Solves and Who Needs It
Traditional segmentation models are trained for a fixed set of classes, so a model that can find a person cannot find a car unless you retrain it. SAM changes that by treating segmentation as a promptable task: you give it a point, a box, or even nothing, and it returns a mask for whatever object you indicated. This is aimed at researchers and engineers who need a general-purpose segmentation tool for images they have not seen during training. The README is explicit about the zero-shot claim: SAM has strong zero-shot performance on a variety of segmentation tasks. That means you can point at a novel object in a photo and get a mask without any fine-tuning. The target user is someone who values flexibility over task-specific accuracy, and who is comfortable with a model that requires a prompt rather than producing a fixed set of classes.
How SAM Works: Prompt Encoder, Image Encoder, Mask Decoder
The README shows the data flow through the Python API. You first load a checkpoint into a registry, then create a SamPredictor, set an image, and call predict with prompts. For automatic mask generation, you use SamAutomaticMaskGenerator, which runs the model over the whole image and returns masks for all objects without any prompt. The command line script scripts/amg.py wraps this generator. The README calls the mask decoder lightweight, and the ONNX export covers that decoder. The README shows that the decoder can be exported to ONNX and run in a browser, while the image preprocessing stays in PyTorch. That split is practical, but it means you cannot fully escape PyTorch for the backbone.
Getting It Running: Installation and First Commands
The installation path is straightforward for anyone who has used PyTorch. You need Python 3.8 or newer, PyTorch 1.7 or newer, and torchvision 0.8 or newer. The README recommends CUDA support. You can install directly from GitHub with pip install git+https://github.com/facebookresearch/segment-anything.git, or clone and run pip install -e . for an editable install. Optional dependencies include opencv-python, pycocotools, matplotlib, onnxruntime, and onnx, plus jupyter for the notebooks. After installation, you download a checkpoint: vit_h (also called default), vit_l, or vit_b. The model type string goes into sam_model_registry, for example sam = sam_model_registry["vit_h"](checkpoint="sam_vit_h_4b8939.pth"). Then you create a predictor, set an image, and call predict with your prompts. The automatic mask generator works the same way but with no prompts. For a quick test, the command line script scripts/amg.py takes a checkpoint, model type, input image or folder, and an output directory. The example notebooks in the notebooks folder show both the prompt-based and automatic workflows in detail.
Checkpoint Sizes and What They Mean for You
Three model versions are available, and the names indicate the backbone: ViT-H, ViT-L, and ViT-B. The README calls ViT-H the default, which suggests it is the best quality model. ViT-L and ViT-B use different backbone sizes. The checkpoint files are direct downloads from dl.fbaipublicfiles.com, and each has a hash in the filename, like sam_vit_h_4b8939.pth. The practical impact is that ViT-H is likely to be heavy on GPU memory, so if you are on a modest machine, you may want to start with ViT-B. The choice of checkpoint is a trade-off between quality and resource use,
ONNX Export and the Browser Demo: A Partial Escape from Python
SAM's mask decoder can be exported to ONNX, which means you can run it in environments that support ONNX runtime, including in a web browser. The export command is python scripts/export_onnx_model.py --checkpoint <path/to/checkpoint> --model-type <model_type> --output <path/to/output>. The README points to an example notebook that shows how to combine image preprocessing via SAM's backbone with mask prediction using the ONNX model. The demo folder contains a React app that runs mask prediction in the browser with multithreading. This is a real benefit if you want to deploy SAM on the client side. However, the export only covers the decoder, not the image encoder. The image encoder remains a PyTorch operation, so you still need a Python backend for the heavy lifting. The README recommends using the latest stable PyTorch for ONNX export, which hints that export can be sensitive to PyTorch versions. That is a maintenance point: if you upgrade PyTorch, you may need to re-export the model.
Where SAM Falls Short: Single Images, Frozen Code, and Dataset Licensing
The biggest limitation is that this repository is for images only. The README's top section is a banner for SAM 2, which extends the approach to video. If you need video segmentation, this repo is the wrong tool. Another limitation is that the repository appears to be frozen. The repository has no GitHub releases, its last push was 2024-09-18, and the README opens with a prominent SAM 2 link, which suggests that development has moved on. That means bug fixes and new features are unlikely to land here. A third limitation is the SA-1B dataset license. The README states that downloading the dataset means you accept the SA-1B Dataset Research License. That is a research license, not a commercial one, so if you plan to train or fine-tune on that data, you need to check whether your use case is covered. The repository code is under Apache-2.0, which is permissive, but the dataset is separate. Finally, the automatic mask generator can produce a huge number of masks, so you may need your own logic to pick the useful ones.
The Alternative: SAM 2 for Video and a Live Codebase
The obvious alternative is SAM 2, which the README itself points to. SAM 2 extends SAM to video by treating images as a single-frame video. The architecture adds streaming memory for real-time video processing, and it is trained on the SA-V dataset, which the README calls the largest video segmentation dataset to date. The key difference is scope: SAM 2 handles images and videos, while SAM 1 handles images only. If you are starting a new project, there is little reason to choose SAM 1 over SAM 2 unless you have a specific reason to avoid the newer model, such as a smaller footprint or a need to match an existing pipeline. The README for SAM 1 points to the SAM 2 repository for its code, demo and paper.
Maintenance and Upgrade Cost: What You Are Signing Up For
The maintenance burden for SAM is moderate but real. The code depends on PyTorch and torchvision, and the README recommends the latest stable PyTorch for ONNX export. The model checkpoints are external files, so you must manage them yourself, including verifying hashes. The repository itself is under Apache-2.0, which allows commercial use and modification. The upgrade path is clear: migrate to SAM 2 if you need video or active maintenance. In short, the cost is low for inference, but the cost of staying current is the cost of moving to SAM 2.
Editorial conclusion
Adopt SAM if you need a single model that can segment objects from point or box prompts without task-specific fine-tuning; evaluate accuracy on your images, and if you are willing to pin PyTorch versions and manage checkpoints manually. Do not adopt it if you need video segmentation or a maintained codebase, because SAM 2 is the successor and this repo is effectively frozen. Before committing, verify that your PyTorch and torchvision versions meet the minimums, download the correct checkpoint for your chosen model type, and test the ONNX export path if you plan to run outside Python. The repository is stable but static, so plan for a migration to SAM 2 if your needs grow beyond single images.
Frequently asked questions
What is the SAM segment anything model?
The Segment Anything Model from Meta AI Research, which produces high quality object masks from input prompts such as points or boxes, and can also generate masks for all objects in an image. It has strong zero-shot performance across a variety of segmentation tasks.
how to install segment anything
With pip install git+https://github.com/facebookresearch/segment-anything.git, or by cloning and running pip install -e . The repository declares no install requirements, so you must install pytorch>=1.7 and torchvision>=0.8 yourself, with CUDA support recommended.
how to use segment anything model in python
Instantiate from the registry with sam_model_registry and a checkpoint, then either wrap it in a SamPredictor, call set_image and predict with prompts, or wrap it in a SamAutomaticMaskGenerator and call generate to mask a whole image without prompts.
How is the Segment Anything Model (SAM) trained?
On the SA-1B dataset, described as 11 million images and 1.1 billion masks. The successor model SAM 2 adds a model-in-the-loop data engine that improves model and data through user interaction to collect the SA-V video dataset.
how to use segment anything 2
SAM 2 lives in its own repository, facebookresearch/segment-anything-2, and the paper is on arXiv at 2408.00714. It extends SAM to video, including images treated as single-frame video, using a transformer architecture with streaming memory for real-time processing.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/facebookresearch-segment-anything)Star history chart for your README
[](https://hysenlabs.com/projects/facebookresearch-segment-anything)Was this useful?