GPTCache: a cache in front of the model, with a temperature dial
Semantic cache for LLMs. Fully integrated with LangChain and llama_index.
At a glance
- What is it?
- An MIT licensed Python library that stores LLM responses and answers repeated or similar questions without calling the model again, either by exact match or by embedding search over SQLite and faiss. Its headline numbers are its own marketing, its API may change at any time, and it no longer adds adapters for new model providers.
- Who is it for?
- It suits an application whose users repeat themselves, where a stored answer is an acceptable substitute for a fresh one, and where Python 3.8.1 or newer and a willingness to auto-install extra libraries at runtime are fine.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 53 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
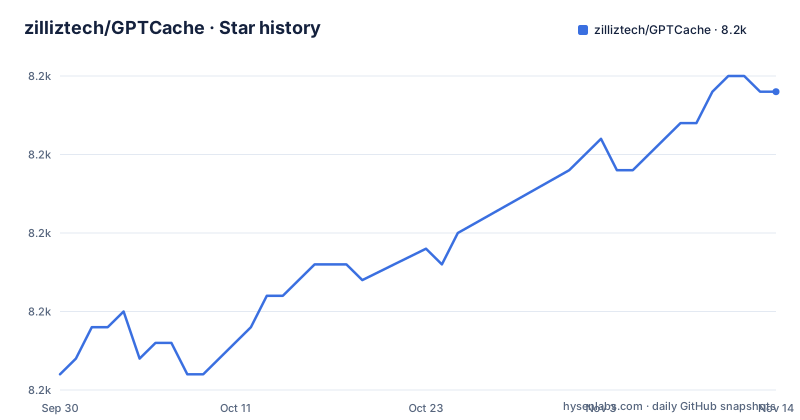
Star history
- zilliztech/GPTCache8,224 ★ · +18
| Repository | 2026-09-30 | 2026-11-14 |
|---|---|---|
| zilliztech/GPTCache | 8.2k | 8.2k |
18 Stars in the last 45 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two cache modes, and the second one needs an embedding function
GPTCache offers exact match and similar search, and the difference is the whole design. With exact match, asking the same question twice means the second answer comes out of the cache without requesting the model again, and the integration is three lines of Python: import the cache, call cache.init, call cache.set_openai_key. Similar search goes further. Once an answer has been obtained for several similar questions, the answers to subsequent questions can be retrieved from the cache without contacting the model, and getting there needs the machinery wired up explicitly: an Onnx embedding function, a data manager combining a CacheBase backed by sqlite with a VectorBase backed by faiss sized to the embedding dimension, and a distance based similarity evaluation imported from the similarity evaluation distance module.
from gptcache import cache
from gptcache.adapter import openai
from gptcache.embedding import Onnx
from gptcache.manager import CacheBase, VectorBase, get_data_manager
from gptcache.similarity_evaluation.distance import SearchDistanceEvaluation

print("Cache loading.....")

onnx = Onnx()
data_manager = get_data_manager(CacheBase("sqlite"), VectorBase("faiss", dimension=onnx.dimension))
temperature decides whether the cache is consulted at all
There is a deliberate freshness dial, and it is the parameter to understand before anything else. A temperature value can always be passed when requesting the API service or model. The range is 0 to 2 and the default is 0.0. The semantics are blunt: a higher temperature means a higher possibility of skipping the cache search and requesting the large model directly. At 2 it will skip the cache and send the request to the model for sure, and at 0 it will search the cache before requesting the model service. So the default is cache-first, and moving the dial up is how you buy freshness at the cost of hit rate. The output side is governed by post_process_messages_func, whose default is temperature_softmax.
New provider support has stopped, so write to get and set
This is the sharpest constraint in the project and it is stated as a note rather than buried. Because the number of large models is growing explosively and their API shape is constantly evolving, the project no longer adds support for new APIs or models. What it does instead is encourage you to use the get and set API in gptcache, with a demo pointing at examples/adapter/api.py. The practical reading is that an existing adapter is a convenience, not an extension point: if your provider is new, you write the adapter yourself against two operations instead of waiting for an official one. There is a second note with the same flavour of warning, that the project is undergoing swift development and the API may be subject to change at any time, which is why the documentation and release note are the two links given for anything current.
Three required libraries, and the rest install themselves at runtime
The dependency story is unusually light and slightly unusual in how it behaves. requirements.txt lists three packages and nothing else: numpy, cachetools and requests. That is the floor, because by default only a limited number of libraries are installed to support the basic cache functionalities. When you reach for an additional feature, the related libraries are installed automatically at that point. So a minimal install stays small, and a fuller one grows while your process is running, which is worth knowing if you run this in a locked down environment or an air gapped one. Two other requirements are explicit: Python 3.8.1 or higher, checked with python --version, and a reasonably current pip, since installation trouble caused by a low pip version is answered with python -m pip install --upgrade pip. The same file is what the packaging reads to build install_requires, so the declared dependencies of a release and the optional ones are two different things.
The server image is what makes the cache reachable from other languages
GPTCache is a Python library, and there is a second shape for everyone else. A GPTCache server docker image has been released, which the announcement frames as meaning that any language will be able to use GPTCache, since the cache moves behind a service boundary rather than being imported. That boundary is a real program: the packaging registers a console script entry point named gptcache_server pointing at gptcache_server.server:main, and gptcache_server/ sits at the top of the tree next to gptcache/. Python callers can also use GPTCache through LangChain, for which detailed usage instructions are published in LangChain's own documentation, and the project description also lists llama_index as integrated. The examples directory mirrors the library's structure rather than showing one happy path, with separate folders for adapter, benchmark, context processing, data manager, embedding, eviction, integration, processor, session and similarity evaluation, plus a vqa demo, so the eviction and data manager examples are where the cache replacement policy is demonstrated. The README's headline, cutting LLM API costs by ten times and boosting speed a hundred times, is the project's own claim rather than a measurement you can check.
The last tagged release is from 2024 and the branch kept moving
Version history is the thing to look at before pinning anything. The tags are 0.1.42 on 2023-09-28, 0.1.43 on 2023-11-28 and 0.1.44 on 2024-08-01, while the last push to the main branch is dated 2026-09-22. In other words the branch is considerably ahead of the newest release, and the version scheme has never left the 0.1 range, so a dependency specification tells you very little about how old the code is. The package version is not stored in the packaging file at all: setup.py reads it with a regular expression over the version string in gptcache/__init__.py and raises an error if the pattern does not match, so a malformed version line breaks the build rather than shipping a bad version. For anything beyond experimenting, install from the branch you intend to run and read the release note.
The install path runs setup.py and a three line requirements file
There are two ways in, and the developer one is explicit about the branch it uses. The quick install for users is a single pip command.
pip install gptcacheFor working on the library itself, the documented steps clone the dev branch, move into the directory, install the requirements file and then run the setup script.
# clone GPTCache repo
git clone -b dev https://github.com/zilliztech/GPTCache.git
cd GPTCache

# install the repo
pip install -r requirements.txt
python setup.py install
The Makefile repeats the same pair as its install target and adds the rest of the release chores: packaging with sdist and bdist_wheel, uploading with twine to PyPI or to the test index, pylint against a checked-in configuration, and pytest over the tests directory. Running the examples also needs a key in the environment, verified by echoing OPENAI_API_KEY and exported per platform, with the caveat that exporting only works for the current session and a permanent setting means editing a configuration file such as /etc/profile on a Mac.
Editorial conclusion
It suits an application whose users repeat themselves, where a stored answer is an acceptable substitute for a fresh one, and where Python 3.8.1 or newer and a willingness to auto-install extra libraries at runtime are fine. It does not suit a team that needs each answer freshly generated, because a cache hit returns an old response by design, and it does not suit anyone waiting for official adapters for new providers, since that support has been discontinued in favour of writing against the get and set API. Check four things before adopting it: which version you are pinning, since the last tagged release is 0.1.44 from 2024-08-01 while the branch has moved since, whether a semantic hit is good enough for your use case, where your API key is set, because the examples read OPENAI_API_KEY from the environment, and whether a pip install during a request is acceptable in your deployment.
Frequently asked questions
what is gpt cache
GPTCache is a library for creating a semantic cache for LLM queries, storing responses so an application does not pay for or wait on a model call it has already made. It installs with pip install gptcache and requires Python 3.8.1 or higher.
What is semantic caching and how does it work in LLMs?
In GPTCache there are two modes. Exact match returns the stored answer when the same question is asked again, and similar search retrieves an answer for a question that resembles ones already answered. Similar search requires an embedding function, a data manager combining a sqlite cache base with a faiss vector base sized to the embedding dimension, and a distance based similarity evaluation.
Does GPTCache add support for new LLM providers?
No. The project states that because model APIs keep changing it no longer adds support for new APIs or models, and it encourages using the get and set API in gptcache instead. A demo of that pattern is in examples/adapter/api.py.
Can I use GPTCache from a language other than Python?
Yes, through the GPTCache server docker image, which was released so that any language can use it. The packaging registers a console script entry point named gptcache_server that points at gptcache_server.server:main, and the server code lives in gptcache_server/.
How do I make GPTCache skip the cache and always call the model?
Use the temperature parameter, whose range is 0 to 2 with a default of 0.0. At 0 the cache is searched before the model is called, a higher value raises the chance of skipping the search, and at 2 the cache is skipped and the request always goes to the model.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zilliztech-gptcache)Star history chart for your README
[](https://hysenlabs.com/projects/zilliztech-gptcache)Was this useful?