FreshRSS: A Self-Hosted Aggregator with Built-In XPath Scraping
A free, self-hostable news aggregator…. FreshRSS natively supports basic Web scraping, based on XPath, for Web sites not providing any RSS / Atom feed.
At a glance
- What is it?
- FreshRSS is a lightweight, self-hostable RSS aggregator that adds native XPath-based web scraping for sites without feeds. It targets privacy-conscious users and small server operators, but its scraping is basic and requires manual configuration.
- Who is it for?
- Adopt FreshRSS if you want a self-hosted, multi-user aggregator with a low server footprint and are willing to configure XPath scrapers for feedless sites. Avoid it if you need automated, robust scraping without manual per-site work, or if your team lacks PHP administration skills.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly PHP, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
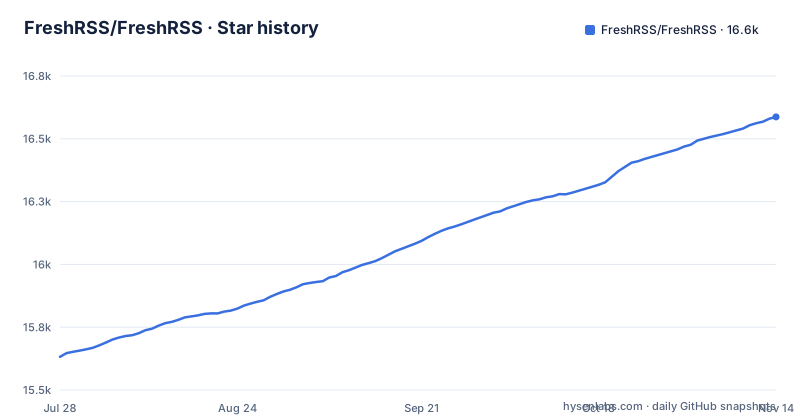
- FreshRSS/FreshRSS16,587 ★ · +955
| Repository | 2026-07-28 | 2026-11-14 |
|---|---|---|
| FreshRSS/FreshRSS | 15.6k | 16.6k |
955 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What FreshRSS Solves and Who It Is For
FreshRSS solves the problem of aggregating news from multiple sources into a single, self-hosted interface. It is for individuals and organizations that want control over their reading data and do not want to rely on cloud-based feed readers. The project explicitly supports multi-user setups with anonymous reading mode, which suits families, small teams, or communities. It also handles sites that do not publish RSS or Atom feeds through native XPath-based scraping. The target user is technically comfortable enough to run a PHP application on a server, but not necessarily a developer.
The Mechanism: XPath Scraping and JSON Support
FreshRSS's scraping mechanism is based on XPath 1.0, as documented in the project's website scraping guide. For a site without a feed, an administrator defines an XPath query that selects the article elements from the HTML. FreshRSS then fetches the page and extracts the content according to that query. The README states that it also supports JSON documents, which means you can parse structured data from APIs or JSON-based sites. This is a manual process: you must know the site's HTML structure and write the correct XPath. There is no automatic detection or machine learning. The data flow is straightforward: the fetcher retrieves the URL, the XPath engine processes the DOM, and the results become feed items. This approach works for simple, predictable layouts, but it has no tolerance for markup changes.
Getting It Running: Installation and Configuration
Installation is manual or automated. The README lists Docker, YunoHost, and several cloud providers. For manual install, you download the archive or clone the repository, place it on a server, and expose only the ./p/ folder to the web. You must give the web server user write access to the ./data/ folder. Then you access the application in a browser and follow the installation wizard, or use the command-line interface. The requirements are specific: PHP 8.2 or later with extensions like cURL, DOM, JSON, XML, session, and ctype. For databases, you need PostgreSQL 10+, SQLite, MariaDB 10.6+, or MySQL 8.0+. Advanced configuration lives in config.default.php, and you modify the generated data/config.php. The README also advises enabling AllowEncodedSlashes in Apache for better mobile client compatibility. These steps are clear but require a server administrator's attention.
A Genuine Limitation: Basic Scraping and Maintenance Burden
The XPath scraping is explicitly described as 'basic' in the README. That means it is not a general-purpose scraping tool. It also breaks when a site's layout changes; you would have to update the XPath queries manually. For sites that change frequently or use complex structures, this is the wrong tool. The burden of maintaining scrapers falls entirely on the administrator.
Maintenance and Upgrade Cost
New versions are published a few times a year, according to the README. That means regular upgrades are part of the maintenance cycle. The project also maintains an 'edge' branch, its default, for a rolling release with the newest features and security fixes, while the 'latest' branch gets fewer updates at the price of less security and more known bugs. The release cadence implies you must plan for updates. The code is licensed under AGPL-3.0, which has implications if you modify and distribute the software: you must share your changes under the same license. The README links a Command-Line Interface documented in cli/README.md, but the README does not detail all commands. The database requirements are version-specific, so you must keep your database up to date to match FreshRSS's support.
Comparison with Alternatives: Different Approaches to Scraping
A common alternative to FreshRSS is a hosted feed reader like Feedly or Inoreader. The key difference is that they are not self-hosted, so you give up control over your data and rely on their infrastructure. Another alternative is a dedicated scraping tool like Huginn or a custom script using Python's BeautifulSoup. FreshRSS's advantage is that it combines aggregation and scraping in one lightweight PHP app. The trade-off is that its scraping is simplistic compared to a dedicated tool. If your scraping needs are extensive, you would be better off with a purpose-built scraper that can handle JavaScript rendering and complex selectors.
Who Should Adopt FreshRSS and What to Verify First
FreshRSS is a strong fit for users who want a self-hosted aggregator with a small footprint. The README claims it runs on a Raspberry Pi 1 with under a second response time for 150 feeds and 22,000 articles, which is a concrete performance indicator. It is also suitable for those who need multi-user support and are comfortable with PHP. Before adopting, verify that your server meets the PHP and database requirements. Test the XPath scraping on the specific sites you care about, because the documentation warns it is basic. Check whether the sites you want to scrape use JavaScript, as that will likely fail. Also confirm that you can expose only the ./p/ folder, because the data folder contains personal information. If you are not prepared to maintain XPath queries and handle regular upgrades, FreshRSS may not be the right choice.
Editorial conclusion
Adopt FreshRSS if you want a self-hosted, multi-user aggregator with a low server footprint and are willing to configure XPath scrapers for feedless sites. Avoid it if you need automated, robust scraping without manual per-site work, or if your team lacks PHP administration skills. Before deploying, verify that your database (PostgreSQL, SQLite, MySQL, or MariaDB) meets the version requirements and that you can expose only the ./p/ folder to the web. Also test the XPath scraping on your target sites, because it only handles simple HTML structures and JSON documents, and it may break when sites change their markup.
Frequently asked questions
What does FreshRSS do?
FreshRSS is a self-hosted RSS feed aggregator written in PHP and licensed under the GNU AGPL 3. It natively supports basic web scraping based on XPath for websites that provide no RSS or Atom feed, and it also supports JSON documents.
what is freshrss
It is a multi-user application with an anonymous reading mode, custom tags, an API for mobile clients, and a Command-Line Interface. It is described as lightweight and easy to work with, and it comes with absolutely no warranty.
how to install freshrss
Get it with git or by downloading the archive, put it on your server exposing only the ./p/ folder to the web, add write access to the ./data/ folder for the webserver user, then open it in a browser to follow the installation process. A Command-Line Interface can do that final step instead.
how to install freshrss extensions
FreshRSS supports extensions for further tuning, and the repository contains an extensions/ directory. The README has an extensions section, and GitHub issues are the stated channel for feature requests.
Is FreshRSS free?
Yes. FreshRSS is free and self-hostable, licensed under the GNU AGPL 3, and the project states it comes with absolutely no warranty.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/freshrss-freshrss)Star history chart for your README
[](https://hysenlabs.com/projects/freshrss-freshrss)Was this useful?