GLM-5 is a 744B model card with no code in it
GLM-5: From Vibe Coding to Agentic Engineering
At a glance
- What is it?
- The zai-org/GLM-5 repository publishes weights, benchmark claims and serving notes for a family of open models running from GLM-5 up to GLM-5.3-Flash, and nothing else. There is no inference code, no training code and no release tag, so the reader has to bring a runtime and pick a version from prose.
- Who is it for?
- GLM-5, 5.1, 5.2 and 5.3 are listed at 744B total and 40B active parameters, while GLM-5.3-Flash is listed at 320B total and 18B active. Check the hosting requirements and benchmark results for the specific model, or consider the documented API for 5.3 and 5.3-Flash.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 30 days ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
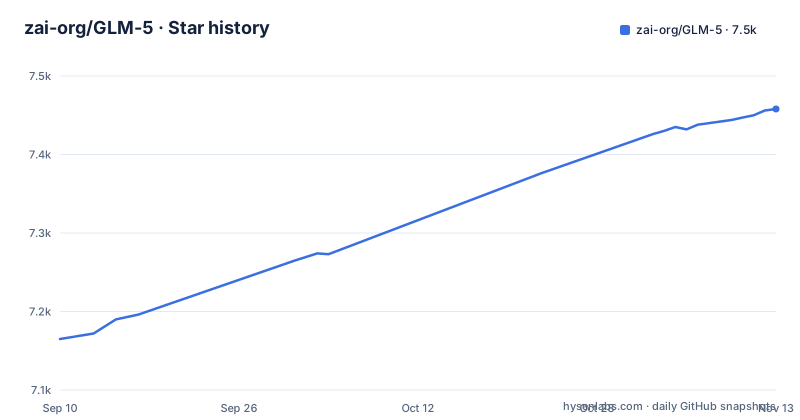
- zai-org/GLM-57,458 ★ · +293
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| zai-org/GLM-5 | 7.2k | 7.5k |
293 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A model card with no code and no release tag
Everything at the top level of zai-org/GLM-5 is documentation or metadata: README.md, its Chinese counterpart README_zh.md, LICENSE, .pre-commit-config.yaml, .github/, and directories called resources/, skills/ and example/, the last holding an ascend.md file. There is no src/, no inference server, no training script and no evaluation harness, and the language of the repository is not recorded as a programming language. The complete Python dependency list is three lines:
transformers>=5.15.0
pre-commit>=4.6.2
accelerate>=1.14.0
Only pre-commit is tooling; transformers and accelerate are libraries, so a reader who expected to clone and run something finishes with weights to fetch and a runtime to choose. The one piece of training infrastructure the project is credited with, an asynchronous RL system called slime, lives in a different repository at THUDM/slime. There are three documented ways in: weights from the download table on Hugging Face and ModelScope, an API documented for GLM-5.3 and GLM-5.3-Flash through the Z.ai API Platform at docs.z.ai/guides/llm/glm-5.3, and a chat interface at z.ai. No GitHub releases exist, and the default branch main was last pushed on 2026-10-15, so pinning a version means pinning a hub revision or an API model name, not a tag.
GLM-5.3 kept the base model and moved the work into post-training
GLM-5.3 uses the same base model as GLM-5.2, and the stated reason for every gain is post-training. That single sentence decides what kind of upgrade 5.3 is. You are not picking a new architecture, a new tokenizer or a new context regime; you are picking different behaviour out of weights you may already have infrastructure for. The headline figure attached to that change is a 50% improvement over GLM-5.2 on an in-house benchmark called Z.ai Code Bench, plus open-source state of the art results on public benchmarks including Terminal Bench 3.0 and Agents' Last Exam. The in-house half is the part you cannot rerun, so a reader comparing 5.2 and 5.3 has to decide how much weight to put on a number that exists only on the vendor's own harness.
Cyber capability grew faster than the authors expected
The most unusual admission in the release notes concerns security. As post-training was scaled, cyber capability developed faster than expected, and GLM-5.3 is called state of the art on CyberGym for vulnerability discovery. The stated pattern is that the gains are largest further up the exploitation chain, where the model more than doubles GLM-5.2 on exploitation benchmarks. Nothing here is a tool, a script or an exploitation technique, and it is worth reading as a risk disclosure rather than a feature list. A team that selects this model for long-horizon coding is also selecting offensive security benchmark leadership it did not ask for, and the same training runs are what produced it. No weight is given for how broad that capability is outside the named benchmarks.
IndexShare reuses one indexer across every four sparse layers
The serving cost story for GLM-5.2 is an architecture proposal called IndexShare, written up separately. Instead of giving every sparse attention layer its own indexer, it reuses the same indexer across every four sparse attention layers, and the claim is a reduction of per-token FLOPs by 2.9 times at a 1M context length. The same model also improves its MTP layer for speculative decoding, which raises the acceptance length by up to 20%. Both numbers are author-reported and depend on a serving stack you assemble yourself. Nothing in this repository lets you reproduce either figure, and neither one is a guarantee about your own throughput: the saving is per token at a specific context length, so short-context workloads see a different ratio than the one advertised.
The 1M-token context arrives with GLM-5.2, not with GLM-5
Context length is where the version numbers stop being interchangeable. GLM-5.2 is the release that first delivers a solid 1M-token context, described as stably sustaining long-horizon work. GLM-5, the earlier one, takes a different route to the same problem: it integrates DeepSeek Sparse Attention, which the notes credit with largely reducing deployment cost while preserving long-context capacity. GLM-5.3-Flash goes further and changes the base model entirely, starting from a newly trained one whose architecture and recipe were redesigned for capability and efficiency. For the first time in the series it combines sparse and linear attention in a hybrid design, adds Manifold-Constrained Hyper-Connections for scaling efficiency, and trains on a 30T-token multimodal corpus. So the name alone tells you nothing about context behaviour.
Two classes of benchmark sit side by side in the same table
The evaluation claims come in two currencies. Public ones can be checked by a reader: Terminal-Bench 2.1 at 81.0 for GLM-5.2 against 62.0 for GLM-5.1, SWE-bench Pro at 62.1 against 58.4, and a first place among open-source models on Vending Bench 2, a simulation where GLM-5 runs a vending machine business for a simulated year and finishes with an account balance of $4,432. Private ones cannot: CC-Bench-V2 across frontend, backend and long-horizon tasks, and Z.ai Code Bench. The cross-vendor comparisons point at Claude Opus 4.8 at 85.0 on Terminal-Bench 2.1, Gemini 3.1 Pro, and Claude Opus 4.5 on the vending and internal suites. The practical consequence is that half this evidence is reproducible and half is a claim you either accept or price into your own evaluation.
744B total with 40B active is the budget you inherit
The scaling numbers for GLM-5 against GLM-4.5 are explicit: parameters go from 355B with 32B active to 744B with 40B active, and pre-training data grows from 23T to 28.5T tokens. The active figure is the one that shapes your infrastructure, because it approximates the work per token; the total figure is what has to be stored. To get there the team built the asynchronous RL infrastructure mentioned earlier, and credits it with more fine-grained post-training iterations. The download table also lists GLM-5.3-Flash at 320B total and 18B active parameters, so the 744B/40B figures do not describe every model in the family. It pairs models with Hugging Face links under zai-org and ModelScope links under ZhipuAI, alongside size and precision columns.
Effort levels trade latency, and no dial values are published
GLM-5.2 introduces multiple thinking effort levels, described as a way to balance performance against latency, and that is the entire specification of the control. The related long-horizon claim is equally qualitative: GLM-5.1 is described as built to stay effective across hundreds of rounds and thousands of tool calls, in contrast to earlier models that exhaust their repertoire early and plateau. That is a design intention stated in prose. Blog posts for GLM-5.3, GLM-5.3-Flash and GLM-5.2, plus a technical report on arXiv at 2602.15763, carry the longer argument.
Editorial conclusion
GLM-5, 5.1, 5.2 and 5.3 are listed at 744B total and 40B active parameters, while GLM-5.3-Flash is listed at 320B total and 18B active. Check the hosting requirements and benchmark results for the specific model, or consider the documented API for 5.3 and 5.3-Flash. They do not suit anyone who wants a pip install or a tagged version to pin. Before choosing between GLM-5.2, GLM-5.3 and GLM-5.3-Flash, decide whether you want the shared base model with new post-training, the newly trained Flash base, or an API call.
Frequently asked questions
What is the GLM-5 model?
It targets complex systems engineering and long-horizon agentic tasks. Against GLM-4.5 it scales from 355B parameters with 32B active to 744B with 40B active, and pre-training data grows from 23T to 28.5T tokens.
How do I install GLM-5.2 locally?
The repository ships no inference code of its own. Its requirements.txt lists transformers>=5.15.0, pre-commit>=4.6.2 and accelerate>=1.14.0, and the download table points at Hugging Face and ModelScope for the weights.
How do I use GLM-5.2?
Through the weights, which the download table hosts on Hugging Face under the zai-org organisation and on ModelScope under ZhipuAI. The API path the documentation covers is for GLM-5.3 and GLM-5.3-Flash on the Z.ai API Platform.
Is GLM ai free?
The visible README states no price or free tier. It points GLM-5.3 and GLM-5.3-Flash users to the Z.ai API Platform documentation and to z.ai for trying them, and gives no cost figures.
Is GLM a Chinese model?
Origin is not addressed in the release notes. The organizational signals available are the ModelScope namespace ZhipuAI used to publish the weights and the z.ai blog and API platform domains the documentation links.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zai-org-glm-5)Star history chart for your README
[](https://hysenlabs.com/projects/zai-org-glm-5)Was this useful?