huggingface/audio-transformers-course: A Translation-First MDX Course Repo
The Hugging Face Course on Transformers for Audio
At a glance
- What is it?
- This repository holds the MDX source for Hugging Face's free Audio Transformers Course, with eight language trees and a copy-then-translate workflow. It is a content repo, not a library, and its structure is the thing to judge before you fork it.
- Who is it for?
- Adopt this repo if you are translating the Audio Transformers Course or vendoring its MDX into a static site build, and skip it if you want a Python package or an offline copy of the lessons, since the README does not describe either.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly MDX, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
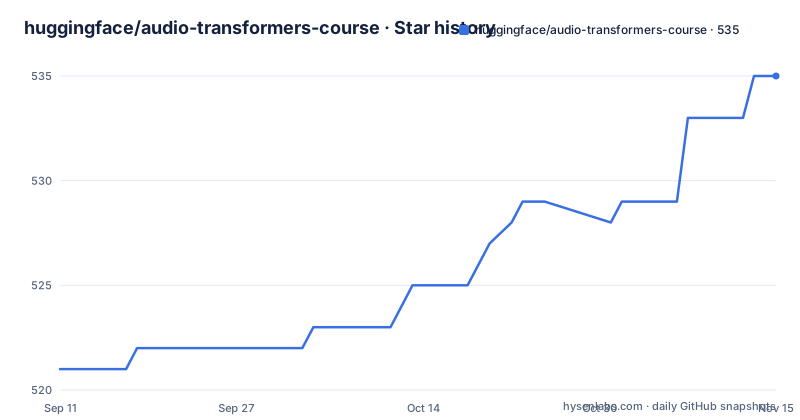
- huggingface/audio-transformers-course535 ★ · +14
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| huggingface/audio-transformers-course | 521 | 535 |
14 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What the repo actually contains
The README opens with a plain statement of scope: the repo holds the content used to build Hugging Face's Audio Transformers Course, a free course about applying Transformers to audio and speech tasks. The homepage field is empty, and the canonical reading experience lives at huggingface.co/learn/audio-course. So the repository is the source of truth for the lessons, not the delivery mechanism. The primary language is MDX, which tells you the files mix Markdown prose with JSX components for the rendered site. Everything under chapters is text and code snippets. If you are looking for a pip-installable package, an inference library, or a set of pretrained weights, this is not that. The README describes no install step, no CLI, and no Python module of its own. It is a content tree with a build contract attached.
Who the chapters directory is for
Two audiences are visible in the README. The first is translators. Hugging Face states it wants the course in more languages and lays out a contribution path for that: open an issue, comment on which chapters you want, then fork and copy. The second audience is anyone who wants the course material in a form they can edit or republish, since the MDX files are plain text in a Git repo under Apache-2.0. What this repo does not serve well is a learner who just wants to read the course. The README points readers at the hosted site rather than at a build you run yourself. If your goal is to study audio Transformers, the repo is a detour; the hosted course is the destination.
The copy-then-translate workflow, step by step
The README gives the translation path as a sequence of concrete commands. First fork the repo, then clone your fork: git clone https://github.com/YOUR-USERNAME/audio-transformers-course. Then change into the checkout and copy a chapter from the English tree into a new language tree: cd ~/path/to/audio-transformers-course followed by cp -r chapters/en/CHAPTER-NUMBER chapters/LANG-ID/CHAPTER-NUMBER. The README defines the placeholders: CHAPTER-NUMBER is the chapter you want, and LANG-ID should be an ISO 639-1 two lowercase letter code, with the {two lowercase letters}-{two uppercase letters} form also supported, as in zh-CN. After copying, the README recommends translating the _toctree.yml entries that correspond to your chapter, changing only the title fields. The example it gives is a title line like 0. Setup and a section entry pairing local: chapter0/1 with a title. The local path stays as is; only the human-readable title moves to your language.
The _toctree.yml rule that breaks builds
This is the one hard constraint in the README, and it is worth reading twice. The file _toctree.yml drives the site's table of contents and the links to the Colab notebooks. The README warns, with a raised-hand marker in the source, that the file must contain only sections that have actually been translated, otherwise the content will not build. In practice that means you cannot copy all of English chapter 3 into chapters/tr and then list all of chapter 3 in the Turkish _toctree.yml while only two files are done. The table of contents has to track reality. This is a translation workflow that fails at build time rather than at review time, which is a reasonable design for a docs site but a sharp edge for first-time contributors who assume the TOC is just navigation. It also means partial translations are the normal state, not an error, as long as the YAML agrees with the files on disk.
Eight language trees and the coordination cost
The README's language table lists Bengali, English, Spanish, French, Korean, Russian, Turkish, and Chinese (simplified), each mapped to a chapters/<LANG-ID> path. Only the Russian row credits named authors, @artyomboyko and @Lightmourne; the other rows leave the author column blank. That blank column is a quiet signal about how these trees are maintained. A translation tree with no listed maintainer is a tree that can drift from the English source when a chapter is edited upstream. The README's answer to coordination is social rather than technical: it asks contributors to open an issue from a Translation template, comment which chapters they will take, and join the Discord channels created per language, because, as the README puts it, discussing translation details over GitHub issues can be difficult.
Licence and the cost of keeping a fork current
The repository is Apache-2.0, which permits reuse and modification, including in commercial contexts, provided the licence terms are met. That is the repository's licence; the README does not state a separate content licence for the prose and figures, and it does not address attribution requirements for translations beyond the author column in the table. Treat that as an open question to resolve before republishing a translated tree under your own branding, and get your own legal read rather than mine. On maintenance: the repo has no published GitHub releases, so there is no versioned artifact to pin. Your fork tracks main. The last push recorded is 2026-05-26, and the topics list includes hacktoberfest, which suggests periodic contribution drives. The practical cost of a fork is therefore not upgrades in the dependency sense but re-syncing prose: every upstream edit to chapters/en is a potential divergence in every language tree, and the README offers no automated way to find those divergences.
Where this repo is the wrong tool
If you need to run audio Transformers on your own data, this repo will not get you there. It contains course text and code snippets, not a runtime. The README's own framing is that the content is used to create the course; the code that actually performs inference lives in the libraries the course teaches about, which are outside this repository. A second mismatch is offline study. A reader without network access has no documented path from this repo to a readable course. A third is single-language, English-only editing: if you only want to fix a typo in the English text, the full translation workflow described in the README is irrelevant to you, and the README does not describe a lighter path for that case.
A real alternative: the hosted course and the sibling NLP course
The most direct alternative is not another repository but the rendered course at huggingface.co/learn/audio-course, which the README names as the thing this content produces. The difference in approach is stark. The hosted course is read-only, always current, and needs no fork, no _toctree.yml, and no Git. This repo is editable, forkable, and translatable, and it puts the build contract in your hands. If you are consuming the material, the hosted site wins on every axis. If you are producing a translation or a derivative, the repo is the only one of the two that lets you. The README also references the NLP course's Chinese tree as an example of the zh-CN naming convention, which is a useful precedent if you are choosing a language code format for a new tree: the same {lowercase}-{uppercase} pattern is already in use across Hugging Face course repos.
Editorial conclusion
Adopt this repo if you are translating the Audio Transformers Course or vendoring its MDX into a static site build, and skip it if you want a Python package or an offline copy of the lessons, since the README does not describe either. Before forking, open the language issue first, check whether chapters/<LANG-ID> already exists for your code, and confirm that every chapter you copy has a matching entry in _toctree.yml, because the README states the build fails when the file lists untranslated sections.
Frequently asked questions
Where can I find a free audio transformers course?
Hugging Face's Audio Transformers Course is free and open source, and its content is published on the Hugging Face learning site. This repository holds the source chapters that produce it.
Which languages is the audio transformers course available in?
Eight: Bengali, English, Spanish, French, Korean, Russian, Turkish and simplified Chinese. Each lives in its own subdirectory under chapters, named by a two lowercase letter ISO 639-1 code or a lowercase and uppercase pair such as the simplified Chinese identifier.
How do I start translating the audio course?
Check the issue tracker for an existing claim on your language, open one from the translation template if there is none, and comment with the chapters you want to work on. Join Discord for the per-language channel to agree terminology before writing, then fork and clone.
What must I do before writing prose in a translated chapter?
Translate the corresponding part of the toctree file first, since it renders the table of contents and supplies the Colab notebook links. Within it, only the title fields should change; the local key must be left exactly as it is.
Why does my translation fail to build on the website?
Because the toctree file lists sections that have not actually been translated. It must contain only the sections that exist, so a listed but unfinished chapter is what stops the content building.
How is code in translated chapters checked?
A formatter script in the utils directory formats code samples automatically and then reports anything it could not fix, which still needs manual attention. One make target checks formatting without changing files and the other formats and reports.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/huggingface-audio-transformers-course)Star history chart for your README
[](https://hysenlabs.com/projects/huggingface-audio-transformers-course)Was this useful?