The Architecture heading is empty
AI Infra / AI Orchestration / AI Control Plane
At a glance
- What is it?
- Polyaxon orchestrates machine learning workloads by deploying into your Kubernetes cluster with Helm. What lives in this repository is the documentation site and the command line client; the control plane, the tuner and the tracer are separate components with their own build workflows.
- Who is it for?
- Polyaxon suits a team that already runs Kubernetes and wants training jobs, tuning and pipelines managed from one control plane rather than from a set of scripts. Four things to check before you commit.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly MDX, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
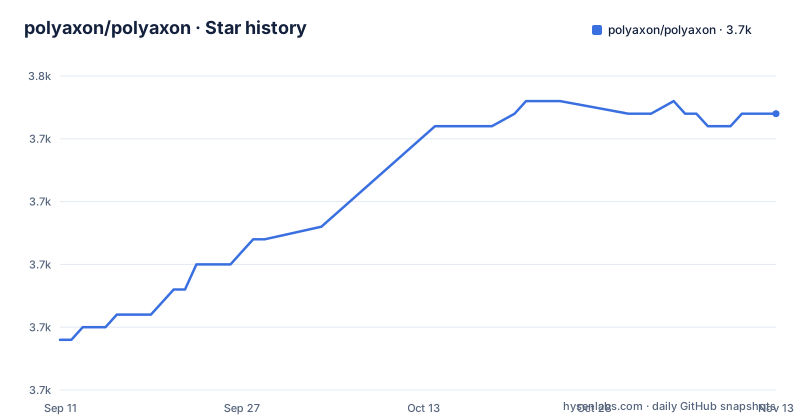
- polyaxon/polyaxon3,747 ★ · +18
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| polyaxon/polyaxon | 3.7k | 3.7k |
18 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Four of the five components are not in this repository
The repository root mixes real directories with symlinks, and the symlinks are the interesting part. The API, the tuning service and the tracing service appear as separate top-level entries, and the continuous integration configuration backs that up: there are four distinct build workflows, one for the command line client, one for the control plane, one for the tuner and one for the tracer. Each is a project with its own release cadence. The result is that installing the client with pip gives you the tool that talks to the platform, not the platform itself. The server-side pieces arrive through the Helm chart rather than through this repository, which also explains why repository metadata reports MDX as the primary language: with the documentation site included, prose outnumbers code. A separate operator entry for machine learning workloads and a directory of client libraries sit alongside, both also linked rather than tracked.
The Architecture section of the README is a heading with nothing under it
Between the description of the DAG engine and the documentation link there is a section titled Architecture, and it is empty. No diagram, no description, no link to an architecture document. Given what the platform actually does, that is the section a reader most needs: the relationships between the client, the API, the operator, the tuner and the tracing service are exactly what is hard to infer from the outside, and the empty heading is where that explanation should have been. Two other structural sections are similarly thin. Documentation is a single line with a link, and there is a status section that is a single sentence. The sections with real content are the ones that are effectively command and capability listings: Install, Quick start, and the grouped lists of distributed job types, search algorithms and workflow features.
Installation is namespace, Helm repo, deploy, then port-forward
The install sequence is four commands, and the third one is the important one:
# Create a namespace
$ kubectl create namespace polyaxon

# Add Polyaxon charts repo
$ helm repo add polyaxon https://charts.polyaxon.com

# Deploy Polyaxon
$ polyaxon admin deploy -f config.yaml

# Access API
$ polyaxon port-forward
The client deploys the platform into your cluster. That means the thing you install with pip needs permission to create namespace-scoped or cluster-scoped resources, install a custom resource definition through the operator, and pull a chart from the vendor's repository. It also means your Helm source list and your container registry trust now include Polyaxon. The last step is the one with a security consequence in the other direction. Access is by port-forward, so the API is bound to your loopback interface and there is no ingress, no hostname and no TLS certificate unless you add them. That is a good default for a first evaluation and a problem for a team that needs shared access, at which point you are the one putting authentication in front of it.
Distributed training asks you to deploy an operator and change your code
The distributed section is where the operational footprint grows. It states plainly that you need to deploy the corresponding operator, adapt your own code to enable distributed training, and update the configuration file. That is three separate obligations, and the first is a cluster-level change rather than a job-level one. The supported shapes are enumerated as separate documentation entries rather than as one mechanism: TensorFlow, PyTorch, MPI, Horovod, Spark and Dask each get their own page, which implies a different operator or a different launch shape per framework. The same pattern appears further down. Hyperparameter tuning needs an experiment group, which defines a search algorithm, a search space and a model to train, and six search strategies are offered including Hyperband and two Bayesian approaches. Parallel execution is handled by a separate mapping abstraction, and workflows are a container-native DAG engine where an operation can itself be a nested DAG.
The framework list still names MXNet and Caffe
The opening paragraph says the platform supports all the major deep learning frameworks, and lists TensorFlow, MXNet, Caffe and Torch. Two of those four are no longer active projects. MXNet reached its announced end of life and Caffe has been dormant for years, while the list contains no mention of the frameworks that dominate current work. This is not a criticism of the orchestration layer, which talks to containers and operators rather than to framework internals, and it may well run those two perfectly well. It is a signal about the age of the prose, and it matters for a reader deciding how current the documentation is. The same paragraph also frames the product in terms of turning GPU servers into shared self-service resources for a team, which is a cluster management pitch rather than a framework compatibility pitch, and that framing is where the actual value is.
A quick start command ships a placeholder that was never substituted
The quick start walks through creating a project, running an experiment, opening the dashboard and starting notebook and TensorBoard servers. Two details in it are worth copying carefully. The dashboard step is interactive by default, printing a confirmation prompt before opening a browser, so a scripted invocation needs a flag to skip it, which the dashboard section later shows as a separate documented form of the same command. And the TensorBoard step ends like this:
# Start TensorBoard for a run's output
$ polyaxon run --hub tensorboard -P uuid=UUID
The value after the equals sign is a literal placeholder in capitals. A reader who pastes the line verbatim gets a parameter assignment to the string UUID and a hub request for a run that does not exist. The experiment step has the same shape of problem in a milder form, since two single-letter flags are shown with no explanation anywhere in the file, one of which uploads code. Quick starts are the most-read text in any repository, and this one assumes you already know which flags are required.
The stability claim carries no evidence, and releases are tracked in docs
The status section consists of one sentence: the project is stable and running in production mode at many startups and Fortune 500 companies. Nothing in the repository substantiates either half. There is no customer list, no case study, no reference architecture and no uptime figure, and the sentence sits under a heading rather than beside any measurement. The versioning is worth reading alongside it. The documented release is 2.16, linked from the README as release notes, and the repository also has Git tags that can be checked out. Consult the release notes for the relevant version. There is a citation file and an invitation to make contact for custom needs, and the project also offers to host and manage the platform for you, so there is a commercial layer behind the open-source one. What the repository does support is narrower and checkable: an Apache 2.0 licence, a contribution guide, a code of conduct, and a coverage configuration for the client.
Editorial conclusion
Polyaxon suits a team that already runs Kubernetes and wants training jobs, tuning and pipelines managed from one control plane rather than from a set of scripts. Four things to check before you commit. Read the Helm chart before running the admin deploy command, because the client installs an operator and pulls from a vendor chart repository. Decide how the API will be reached, since the documented path is a loopback port-forward and anything shared needs authentication you supply. Confirm the frameworks you actually use are supported today, since the prose still advertises MXNet and Caffe. And do not rely on the stability sentence as evidence, since the repository has no GitHub releases and its version history lives in the documentation rather than in tags.
Frequently asked questions
What is Polyaxon?
It is a platform for building, training and monitoring large scale deep learning applications, aimed at reproducibility, automation and scalability. It manages workloads with container and node management, deploys into any data centre or cloud provider or can be hosted by Polyaxon, and positions GPU servers as shared self-service resources for a team.
How do I install Polyaxon?
Install the client with pip, create a Kubernetes namespace, add the Polyaxon charts repository to Helm, then run the admin deploy command against a configuration file. The last step is port-forward, which binds the API to your loopback interface rather than exposing it through an ingress.
What is an experiment group in Polyaxon?
It is the unit for suggesting hyperparameters and managing their results, described as similar to Google Vizier. An experiment group defines a search algorithm, a search space and a model to train, and the available strategies include grid search, random search, Hyperband, Bayesian optimization, Hyperopt and a custom iterative option.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/polyaxon-polyaxon)Star history chart for your README
[](https://hysenlabs.com/projects/polyaxon-polyaxon)Was this useful?