huggingface/course: what the repository actually contains, and who should clone it
The Hugging Face course on Transformers
At a glance
- What is it?
- The Hugging Face course repository is the MDX source behind the hosted Transformers course, not a software library. Its value depends on whether you want to read the course or translate it, and the README shows the translation pipeline is the part with real maintenance weight.
- Who is it for?
- Adopt this repository if you are translating the course into a new language, mirroring it for offline classroom use, or reviewing the MDX source behind a hosted lesson. Do not clone it expecting a runnable library: it is prose and code samples, and the repository has no GitHub releases to pin to.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly MDX, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
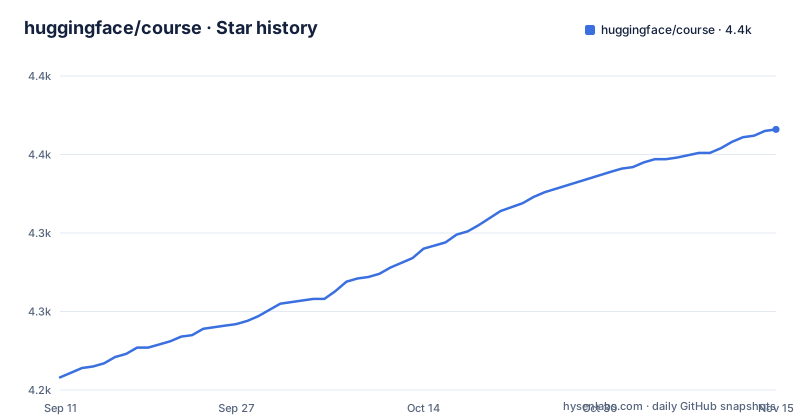
- huggingface/course4,366 ★ · +158
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| huggingface/course | 4.2k | 4.4k |
158 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The repository is course prose, not a package you install
The README opens by stating the repo contains the content used to create the Hugging Face course at huggingface.co/course/chapter1/1. That single sentence settles the scope question. The repository has no setup.py, no environment file, and no published GitHub releases. The primary language is MDX, which is Markdown with embedded JSX, and the content is organised into chapters per language. If you arrived looking for a library that wraps Transformers, Datasets, Tokenizers or Accelerate, this is the wrong repository. Those are separate projects, linked from the README as the ecosystem the course teaches. What you get here is the teaching material itself: explanations, and code samples that call into those libraries. Treating the repo as a dependency would be a category error.
Who this is for: translators, mirror maintainers, and course reviewers
The README's language table is the clearest signal of intended audience. It lists English as the source under chapters/en, with named authors, and then a long set of translations, each pointing at its own directory such as chapters/fr, chapters/de, chapters/es, chapters/bn, chapters/fa, chapters/gu, chapters/he, chapters/hi and chapters/id. Most of those entries carry a WIP marker next to the language name. That tells you the repository is built for people who want to move the course into another language, or who want to host or adapt the text themselves. It is also useful for an engineer who wants to read a lesson in MDX form, for example to copy a code sample into a notebook without the surrounding page furniture. It is not aimed at someone who wants a stable API, a CLI, or a test harness. Authors are credited by GitHub handle for the English track and for each translation.
How the content is laid out: chapters per locale
The mechanism is directory-per-language. English lives at chapters/en and is described as the source. Each translation lives at chapters/<language-code>, and the hosted course serves the same chapters under a locale path, so the English course is at huggingface.co/course/en/chapter1/1 and the French one at huggingface.co/course/fr/chapter1/1. The chapter numbering in the URLs is shared across languages, which means a translation is expected to track the English chapter structure rather than invent its own. That is a reasonable design for a course, because it keeps cross-language links predictable and lets the site route by locale prefix. The cost is coupling: when an English chapter is rewritten or renumbered, every translation directory that mirrors it is now out of step.
The WIP markers are the real limitation
Look at the table again and count the WIP labels. Bengali, German, Spanish, Persian, Gujarati, Hebrew, Hindi and Bahasa Indonesia are all marked WIP in the README's language table. French is listed without that marker. The practical consequence is that a reader told to use the Spanish course is being pointed at a moving target, and a translator joining a WIP track is joining unfinished work. For a learner, the safe path is the English source. For a contributor, the safe assumption is that you are signing up to maintain a branch of prose that will drift whenever the English text changes. That is a maintenance burden, not a bug, but it should be priced in before you start.
Getting it running means building the site, and the README does not say how
The repository root holds a Makefile whose two targets, quality and style, run utils/code_formatter.py to check or reformat the code samples, and a requirements.txt listing nbformat, PyYAML and black; none of these builds the site. What can be said concretely is what you would do with the files once you have them: clone the repository, open chapters/en, and read the MDX directly, since MDX is text and the code samples are readable without a renderer. Anyone writing a setup guide for this repo should start by reading the root files rather than trusting a summary.
Where the course sits against the library documentation
The obvious alternative is the documentation shipped with each library the course covers. Transformers, Datasets, Tokenizers and Accelerate each maintain their own docs, and those are written to describe APIs as they exist at a given version. The course takes the opposite approach: it is narrative, task-oriented, and versioned by prose edits rather than by release tags. The README notes the course teaches applying Transformers to tasks in natural language processing and beyond, which is a pedagogical framing, not an API reference framing. The difference matters when something breaks. If a function signature changes, the library docs are updated as part of the release process, while the course text is corrected by whoever notices. The repository has no published GitHub releases, so there is no changelog to consult when a sample stops working. Choose the course when you are learning a workflow end to end; choose the library docs when you need the current signature of a specific call.
Licence and the cost of keeping a fork alive
The repository is Apache-2.0, which permits reuse and modification provided the licence terms are met, including attribution and the preservation of notices. That is a permissive licence, so a translation or an internal mirror is not blocked by licensing. This is not legal advice, and if you plan to redistribute a modified course, read the licence text and the NOTICE requirements yourself. On maintenance: the last push recorded is 2026-10-06, and the content is under active translation across many locales, so a fork will need periodic rebasing against chapters/en to stay accurate. The absence of releases means there is no tagged snapshot to pin to, which makes reproducing a specific state of the course harder than reproducing a specific version of a library. Budget for reading diffs in the English directory before each sync, not for a version bump.
The judgement: read it, translate it, or leave it alone
If you want to learn how to apply Transformers to NLP tasks using the Hugging Face ecosystem, the hosted course is the product and this repository is its source. Cloning it adds nothing over reading huggingface.co/course unless you need the raw MDX. If you want to translate, the directory-per-locale layout is straightforward and the licence permits it, but most translation tracks in the README's table are marked WIP. If you want a library, close this tab and open the Transformers, Datasets, Tokenizers or Accelerate repositories instead. The one thing worth verifying before you invest time is whether the chapters in your target language directory still match the structure of chapters/en, because nothing in the README suggests that comparison is automated.
Editorial conclusion
Adopt this repository if you are translating the course into a new language, mirroring it for offline classroom use, or reviewing the MDX source behind a hosted lesson. Do not clone it expecting a runnable library: it is prose and code samples, and the repository has no GitHub releases to pin to. Before committing to a translation, open chapters/en and the target language directory side by side, because the README marks most non-English tracks WIP, which means the two will diverge as English chapters are edited.
Frequently asked questions
What is the Hugging Face course?
A free and open-source course on applying Transformers to natural language processing tasks and beyond. The repository holds the content used to create it, and along the way the course teaches the Transformers, Datasets, Tokenizers and Accelerate libraries as well as the model hub.
Which languages is the Hugging Face course available in?
English and French are listed without a WIP marker, while Bengali, German, Spanish, Persian, Gujarati, Hebrew, Hindi and Bahasa Indonesia are marked as work in progress. Each language has its own directory of source chapters, and the table credits the authors of each.
How are the code samples in the Hugging Face course kept formatted?
By a script in the repository's utilities directory, invoked by two make targets: one passes a check-only flag and one rewrites the samples, then checks whether anything is left that needs manual fixing. requirements.txt lists three dependencies: nbformat, PyYAML and black.
Does the Hugging Face course repository publish releases?
No. It has no GitHub releases, so the content is versioned by commits, with the last push dated 2026-10-06. The licence is Apache 2.0 and the project states that the course is free and open source.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/huggingface-course)Star history chart for your README
[](https://hysenlabs.com/projects/huggingface-course)Was this useful?