Diffusers 0.42: A modular toolbox for diffusion models, with trade-offs you should know
🤗 Diffusers: State-of-the-art diffusion models for image, video, and audio generation in PyTorch.
At a glance
- What is it?
- Hugging Face Diffusers is a Python library for image, video, and audio generation with pretrained pipelines, schedulers, and models. This review covers what it actually does, how to run it, and where its design philosophy creates friction.
- Who is it for?
- Adopt Diffusers if you need a broad, modular toolkit for diffusion models across image, video, and audio, and if you prioritize easy experimentation over raw speed. Avoid it if you require minimal dependencies or maximum performance for production inference, where the abstraction layer may be too heavy.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
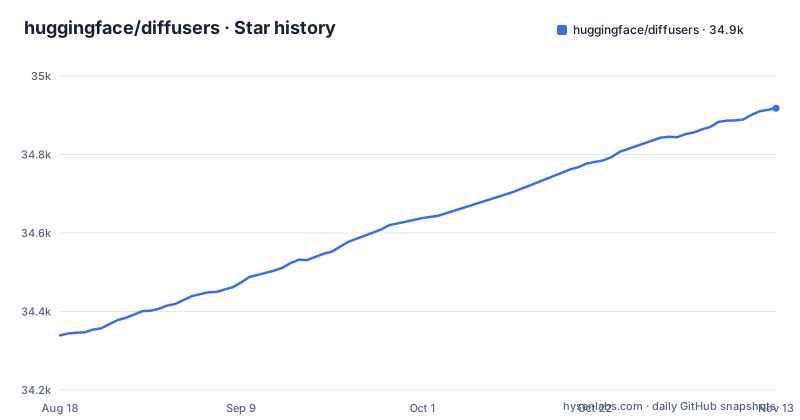
- huggingface/diffusers34,918 ★ · +579
| Repository | 2026-08-18 | 2026-11-13 |
|---|---|---|
| huggingface/diffusers | 34.3k | 34.9k |
579 Stars in the last 87 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Diffusers actually solves, and who should care
The core design philosophy is stated directly in the README: usability over performance, simple over easy, and customizability over abstractions. That last point is important. The library prefers exposing many small pieces over hiding them behind a monolithic API. For a beginner, that means more concepts to learn. For an expert, it means you can replace a scheduler or a model without rewriting the whole pipeline. The trade-off is real: you get flexibility, but you also get a learning curve. The README's example of building a custom diffusion loop with DDPMScheduler and UNet2DModel shows that you can bypass pipelines entirely if you want full control. That is the point of the modular design, and it is also the source of its complexity.
The three components: pipelines, schedulers, and models
The custom loop example in the README is worth reading closely. It loads a scheduler and a model separately, sets 50 timesteps, and then iterates through the scheduler's timesteps, calling the model and the scheduler's step method. That is the full diffusion loop. It is only a few lines of code. If you understand that loop, you understand the core mechanism of diffusion. The pipeline abstraction just wraps that loop with additional logic for text encoding and image decoding. This is a concrete illustration of the 'simple over easy' philosophy: the simple loop is exposed, not hidden. If you want to change the number of timesteps or the noise schedule, you can do it directly. That is a genuine advantage for experimentation, but it also means you need to know what you are doing.
Getting it running: installation and the quickstart
The from_pretrained method is the central entry point. It works for pipelines, models, and schedulers, and it pulls checkpoints from the Hub. The README mentions browsing the Hub for over 30,000 checkpoints, which is a lot of options. But that also means you need to know which checkpoint you want. The quickstart uses stable-diffusion-v1-5/stable-diffusion-v1-5, which is a common baseline. The installation command includes the torch extra, which brings in PyTorch dependencies.
The performance trade-off: usability over speed
The custom loop example is a good illustration of the performance ceiling. It uses a Python for loop over 50 timesteps, with a model call and a scheduler step at each iteration. That is not optimized for speed. A compiled or graph-based runtime could fuse those operations and run much faster. Diffusers is designed for flexibility, not for maximum throughput. For research and prototyping, that is the right choice. For deployment, you will likely need to convert the model to a different format or use a separate serving stack. The repository does include example server code in examples/server/ and examples/server-async/.
Where it is the wrong tool: limitations and failure modes
The 'simple over easy' philosophy has a concrete consequence: you need to understand the diffusion process to use the library effectively. The quickstart hides that, but the custom loop example shows the underlying complexity. If you just want a black box that turns text into an image, Diffusers is more complicated than it needs to be. You could use a hosted API or a single-purpose tool. The library is not a failure for that use case, but it is overkill. For audio and video, the repository description claims support, and the repository has example folders such as examples/cogvideo/. If you are evaluating Diffusers for a video generation project, you should verify that the specific pipeline you need exists and is stable. Recent releases (v0.41.0 and v0.42.0) added new pipelines such as QwenImage 2.1, FLUX.3, Fibo 2.0 and Kandinsky 6, so the space is moving fast, but that also means the APIs are young.
Alternatives and how they differ
The most direct alternative is to use the underlying model repositories directly. For example, a model's own repository may ship its own inference code. That approach gives you less abstraction and more control over the exact implementation. The difference is that Diffusers standardizes the interface across many models, while a model-specific repository is tailored to one model. If you only ever use one model, the model-specific code might be simpler and faster. If you switch models often, Diffusers saves you from learning a new API each time. Another alternative is to use a serving framework like TensorRT or ONNX Runtime with a diffusion model converted to those formats. Those tools focus on inference speed and throughput, not on flexibility. You would lose the ability to swap schedulers easily, but you would gain performance. The philosophy statement implies that Diffusers is not competing on raw speed. For training, Diffusers includes training guides, but a dedicated training library like PyTorch Lightning or a custom training loop might give you more control. This is a judgment based on the stated philosophy.
Maintenance and upgrade cost
The README also mentions the use of AI agents for contribution, with commands like claude plugin marketplace add huggingface/diffusers and diffusers-cli skills add <name>. That is a sign that the project is embracing AI-assisted development, which could speed up contributions but also introduces new maintenance concerns. The .ai directory is a convention for AI agents to follow, which is an interesting experiment. For a user, that does not affect you directly, but it shows that the project is willing to try new workflows. Overall, the maintenance cost is moderate: you need to keep up with releases, but the project is active, with three releases between 2026-10-06 and 2026-10-27.
Editorial conclusion
Adopt Diffusers if you need a broad, modular toolkit for diffusion models across image, video, and audio, and if you prioritize easy experimentation over raw speed. Avoid it if you require minimal dependencies or maximum performance for production inference, where the abstraction layer may be too heavy. Before committing, verify that the specific pipeline you need is present in the current release, since new pipelines appear frequently but not every model is supported. Also check the PyTorch version and hardware requirements for your target workloads, especially for video and audio pipelines that may not be optimized for CPU or older GPUs.
Frequently asked questions
how to install diffusers in python
The README gives two commands, pip install --upgrade diffusers[torch] as the official package and conda install -c conda-forge diffusers as the community-maintained one, and recommends a virtual environment from PyPI or Conda. For details about installing PyTorch, the README points to pytorch.org.
what is diffusers in ai
Diffusers is an Apache-2.0 PyTorch library for pretrained diffusion models, built from three parts: pipelines that run inference, interchangeable schedulers that set diffusion speed and output quality, and model classes you can combine yourself. It covers image, audio and molecule structure generation, and supports both inference and training your own model.
how to install diffusers stable diffusion
After installing the package, load the checkpoint with DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5", dtype=torch.float16) and call pipeline.to("cuda"). The quickstart passes dtype rather than torch_dtype, and the same page points Apple Silicon users to a separate guide on Stable Diffusion on Apple Silicon.
how to install diffusers from source
The repository ships setup.py, a Makefile and a src/ layout, and the Makefile exports PYTHONPATH = src so targets run against your checkout rather than an installed wheel. Contributor targets include quality, repo-consistency, deps_table_update and modified_only_fixup, and the tools they call, ruff and doc-builder, are not part of the two install commands the README gives.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/huggingface-diffusers)Star history chart for your README
[](https://hysenlabs.com/projects/huggingface-diffusers)Was this useful?