huggingface/smol-course: a peer-reviewed alignment course on SmolLM3 whose later units were still on a 2025 schedule
A course on aligning smol models.
At a glance
- What is it?
- huggingface/smol-course is a Jupyter Notebook course on aligning small language models, built around SmolLM3 and SmolVLM2 and meant to run on local machines. Four of its seven units are marked released, and its dependency files assume Python 3.11 and a 2024 era library stack.
- Who is it for?
- Take smol-course if you can already fine-tune with transformers and want a structured path through instruction tuning, evaluation, preference alignment and vision models on small models. Skip it if you need a finished reinforcement learning or synthetic data unit, or a fixed release to cite, because neither is tagged.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
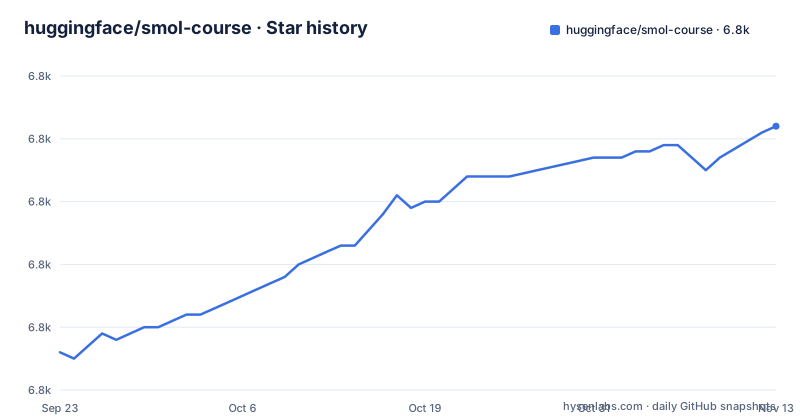
- huggingface/smol-course6,792 ★ · +36
| Repository | 2026-09-23 | 2026-11-13 |
|---|---|---|
| huggingface/smol-course | 6.8k | 6.8k |
36 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The pitch is alignment on a local machine with no paid services
The course describes itself as a practical course on aligning language models for your specific use case, and says everything runs on most local machines, with minimal GPU requirements and no paid services. It is built around SmolLM3 and SmolVLM2, and says the skills carry over to larger models or other small LLMs and VLMs.
The phrase minimal GPU requirements is not given a number. The project states no memory figure, no card model and no training time, so you cannot tell from the repository whether your laptop will cope with a given unit. The practical step is to run the first notebook and watch memory before committing time.
The project's own case for small models is a list of claims: efficiency, easier customisation, better control of behaviour, lower cost, local privacy, a smaller carbon footprint and an easier start for academic research. Treat those as the course's motivation, not measured results.
Four units are released, and the last three carry 2025 dates
The outline table has seven rows. Instruction Tuning covers supervised fine-tuning, chat templates and instruction following. Evaluation covers benchmarks and custom domain evaluation. Preference Alignment aligns models to human preferences with algorithms like DPO. Vision Language Models adapts and uses multimodal models. These four carry a check mark in the Released column.
The remaining three have dates instead of check marks: Reinforcement Learning in October 2025, Synthetic Data in November 2025 and an Award Ceremony in December 2025. Those dates are well in the past, but the table was never updated to show a check mark, so the repository does not confirm they shipped.
If reinforcement learning or synthetic data generation is why you are here, open the units directory first and see what actually exists. Otherwise you may plan a study schedule around material that is still a placeholder.
Participation runs through pull requests and a model leaderboard
The course calls itself open and peer reviewed. To take part you follow the Hugging Face Hub organisation, read the material, make changes, do the exercises and add your own examples, then submit a model to the leaderboard and try to climb it. The route for submitting work for review is a pull request.
The repository has a leaderboard directory, which is where that mechanism lives. The aim stated is a community driven course that keeps improving.
The consequence for a solo learner is that the course is designed as a social loop. You can work through the notebooks alone, but the leaderboard and review steps assume you submit something, so progress is judged on a submitted model, not on finishing every cell. A Discord link is also provided for questions.
Prerequisites assume you already fine-tune with transformers
The course lists three prerequisites. You need a basic understanding of machine learning and natural language processing, familiarity with Python, PyTorch and the transformers library, and access to a pre-trained language model and a labeled dataset.
Nothing in that list teaches those skills, so this is not an introduction to PyTorch or to tokenisation. A reader who has never loaded a model with transformers will be learning two things at once, which is the main way people stall.
The last prerequisite is easy to overlook. You are expected to bring a labeled dataset, so the course does not promise to hand you one for every exercise. The datasets package at version 3.1.0 or newer is a dependency, and the Hub is the natural place to find data, but check each unit for what data it expects before you start.
Two dependency files disagree on how strict to be
pyproject.toml names the project smol-course at version 0.1.0 with the description a smol course on llms, requires Python 3.11 or newer, and lists seven floors: datasets>=3.1.0, huggingface-hub>=0.26.3, lighteval>=0.6.2, ipywidgets>=8.1.5, transformers>=4.46.3, trl>=0.12.1 and bitsandbytes>=0.45.0.
requirements.txt is different. It is autogenerated by uv with uv export --format requirements-txt --no-hashes, and it pins exact versions such as accelerate==1.1.1, aiohttp==3.11.9, datasets==3.1.0, huggingface-hub==0.26.3, numpy==2.1.3 and pandas==2.2.3. The repository also has uv.lock and .python-version.
The consequence is a choice. Installing the pins reproduces the stack the author locked, which will be older than current releases. Installing from pyproject.toml gets newer packages, and a newer trl or transformers can change training APIs under the notebooks. If a notebook fails on a fresh environment, try the pinned set first.
The CUDA pins only apply on x86_64 Linux
The nvidia packages in requirements.txt carry environment markers. nvidia-cublas-cu12==12.4.5.8, nvidia-cudnn-cu12==9.1.0.70, nvidia-nccl-cu12==2.21.5 and the other cu12 entries apply only when platform_machine is x86_64 and platform_system is Linux. colorama==0.4.6 applies only on Windows.
So the pinned file is shaped for a Linux machine with an Nvidia GPU. On macOS, or on an ARM machine, those CUDA packages are skipped. The repository does not say whether the training units are practical on those platforms, and bitsandbytes is listed as a dependency without a platform note, so be ready for friction there.
The repository includes a .devcontainer directory, which is a ready made environment option if you want to avoid setting up Python 3.11 yourself.
Version 1 still sits in v1/, and the course is moving to Hugging Face Learn
The first version of the course used GitHub markdown and Jupyter notebooks and is kept in the v1 directory. Version 2 is the live one, with materials in units and notebooks. A banner states that smol course v2 is live.
A second notice says the course will soon be re-released on Hugging Face Learn. That matters for bookmarks and for contributors: the home of the canonical content may shift, and a pull request to this repository may target something that moves.
There are no GitHub releases and the package version is 0.1.0, so there is nothing to cite by tag. The last push was on 2026-10-06, the repository is not archived, and the license is Apache-2.0. If you need a stable reference, record the commit you worked from.
Editorial conclusion
Take smol-course if you can already fine-tune with transformers and want a structured path through instruction tuning, evaluation, preference alignment and vision models on small models. Skip it if you need a finished reinforcement learning or synthetic data unit, or a fixed release to cite, because neither is tagged. Before starting, check units/ for which units exist and decide between the pinned requirements.txt and the looser pyproject.toml.
Frequently asked questions
Is there a course that teaches small language models?
Yes. huggingface/smol-course is a practical course on aligning small language models, built around SmolLM3 and SmolVLM2 and designed to run on most local machines.
What is instruction tuning and how does it work in smol-course?
The first unit, Instruction Tuning, covers supervised fine-tuning, chat templates and instruction following, using libraries such as transformers and trl.
How to train SmolLM with smol-course?
The course is built around SmolLM3 and uses datasets, transformers, trl and bitsandbytes; start with the Instruction Tuning unit and its notebooks on Python 3.11 or newer.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/huggingface-smol-course)Star history chart for your README
[](https://hysenlabs.com/projects/huggingface-smol-course)Was this useful?