Claude Code Karma: a local dashboard for your ~/.claude session data
Dashboard for monitoring claude code sessions.
At a glance
- What is it?
- Claude Code Karma reads the JSONL files Claude Code already writes and renders them as a browser dashboard for sessions, tools, agents, hooks and cost. It is local-only, Python plus SvelteKit, and it is only as complete as Claude Code's roughly 30-day retention window.
- Who is it for?
- Adopt Claude Code Karma if you already run Claude Code CLI or Claude Desktop and want per-session cost, tool and subagent breakdowns without sending session data anywhere. Skip it if you need long-term retention or cross-machine aggregation: the README states Claude Code keeps session data for about 30 days and that deleted JSONL files disappear from the dashboard too.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 21, 2026, and from our analysis. They are not legal advice.
Star history
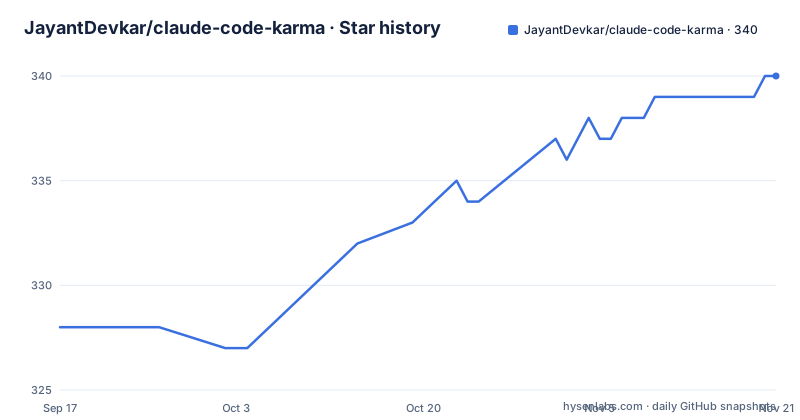
- JayantDevkar/claude-code-karma340 ★ · +12
| Repository | 2026-09-17 | 2026-11-21 |
|---|---|---|
| JayantDevkar/claude-code-karma | 328 | 340 |
12 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem: your session history is JSONL you will never read
Claude Code writes a record of everything it does. Prompts, tool calls, thinking blocks, responses, token counts. The README puts the location at `~/.claude/`, with session files under `~/.claude/projects/`. That is a complete audit trail of your work, and in practice nobody opens it. The files are newline-delimited JSON, one event per line, and reconstructing a single session's cost or tool distribution by hand is tedious enough that people do not do it.
Claude Code Karma is aimed at that gap. It is for individual developers and small teams who already use Claude Code and want to see what happened, without standing up a hosted observability service. The README is explicit about the posture: "No cloud. No accounts. No telemetry. Just your data, on your machine." That sentence is the whole product thesis. If you are comfortable shipping session transcripts to a third party, this tool is solving a problem you have already decided not to have.
How Karma turns ~/.claude JSONL into a dashboard
The architecture visible in the repository is two processes. There is a Python `api/` directory and a SvelteKit `frontend/`, plus `hooks/`, `skills/`, `scripts/` and `captain-hook/` at the top level. Karma does not intercept Claude Code at runtime and does not patch it. It reads the same files Claude Code already writes, which is why the README can say any session that writes to `~/.claude/` shows up automatically, including Claude Desktop running in Claude Code mode.
That read-only design has a direct consequence worth stating plainly. Karma is a viewer, not a recorder. If the underlying JSONL is gone, the dashboard has nothing to render. The README warns that Claude Code only keeps session data for about 30 days and that older files in `~/.claude/projects/` are cleaned up automatically. So the retention ceiling of your dashboard is the retention ceiling of Claude Code itself. Anyone expecting a permanent archive will be disappointed, and no configuration inside Karma changes that.
The feature set follows from what is in those files. A session browser with search by title, prompt or slug, and project filtering. A per-session timeline of prompts, tool calls, thinking blocks and responses. Tabs for tasks, files, subagents, skills, shells and analytics. Analytics cover per-session cost breakdown, token usage, cache hit rates and a tool distribution donut chart. Across sessions there are aggregated views for projects, tools and MCP servers, agents, and hooks organized by lifecycle phase. The hooks page notes which hooks can block execution, which is a detail that matters more than it looks: a blocking hook is a failure mode, and seeing registrations grouped by lifecycle phase is a faster way to audit them than reading settings files.
One feature is worth calling out because it goes beyond reading files. The session browser shows live sessions with status badges and a `>_` button that raises the terminal window a live session is running in. That implies Karma detects running sessions rather than only completed ones, which is a different problem from parsing JSONL after the fact.
Installing Claude Code Karma and reading your first session
The README does not carry install commands; it points at `SETUP.md` in the repository root for setup instructions, and the badge block lists the requirements as Python 3.10+, Node 18+ and SvelteKit 2. Treat `SETUP.md` as the source of truth for exact commands and ports, because the README does not specify either.
What the repository layout tells you is that there are two things to start: the Python API in `api/` and the SvelteKit frontend in `frontend/`. A reasonable first check before anything else is that your Claude Code data actually exists where Karma expects it:
ls ~/.claude/projects/If that directory is empty, Karma has nothing to show and the problem is upstream. If it lists project directories, you have session data inside the retention window.
Once the API and frontend are running per `SETUP.md`, the first useful screen is the session browser. The README describes searching by title, prompt or slug and filtering by project. Pick a session you remember and open its Analytics tab. That tab is where the per-session cost breakdown, token usage, cache hit rate and tool distribution live, and it is the fastest way to confirm the parser is reading your files correctly rather than silently rendering zeros.
From there, the Tools and MCP page is the second stop. It groups every tool Claude Code used, built-in ones like Read, Edit and Bash plus any MCP integrations, by server, with call counts and session coverage. If your MCP servers do not appear there, that is a parsing or path issue, not a missing feature.
Where Claude Code Karma stops being the right tool
The 30-day retention window is the hard limit. Karma reads from `~/.claude/projects/`; Claude Code deletes old files there; deleted sessions vanish from the dashboard. The README states this as a warning rather than burying it, which is honest, but it means Karma is a recent-history tool. If your question is "how much did this project cost me over six months," Karma cannot answer it from local files alone.
There is a second boundary: single machine. The README describes reading local data on your machine. There is no mention of a sync layer, a remote store, or multi-user accounts. A team that wants one shared view across several developers' machines is outside what the documentation describes.
Third, the project is young. The releases listed are v0.2.0 (Session to Ticket Linking) from 2026-05-19 and a first release v0.1.0 from 2026-03-01. Version 0.2.0's headline feature is ticket linking, which suggests the integration surface is still being built out rather than settled. The README is also truncated mid-sentence in the hooks section, so the full hook feature set is not documented in what is available. Anyone evaluating this for a workflow that depends on hooks visualization should read `FEATURES.md` and the rest of the README rather than trusting the excerpt.
Finally, Karma is a viewer. It does not enforce budgets, block expensive tool calls, or alert you mid-session. If you want intervention rather than observation, a dashboard is the wrong shape of tool.
Karma against a hosted LLM observability platform
The obvious alternative category is a hosted observability platform that instruments LLM applications and ships traces to a server, where you get cross-machine aggregation, long retention, alerting and team dashboards. The difference in approach is not cosmetic. A hosted platform requires you to instrument your code and accept that session content leaves your machine. Claude Code Karma requires neither, because it reads files Claude Code already wrote and serves them locally.
That trade is clean. You give up retention beyond what Claude Code keeps, cross-machine views and alerting. You get zero instrumentation work and no data egress. For a solo developer debugging why a session burned tokens, the local approach is strictly less work. For a platform team that needs to answer questions about usage across twenty engineers over a quarter, the local approach cannot answer the question at all, and no amount of configuration in Karma fixes it.
A second, smaller alternative is just reading the JSONL with `jq` or a short script. That works for one-off questions and costs nothing. Karma's value over it is the cross-session aggregation: tool call counts grouped by server, agent run counts, cache hit rates over time, and the hooks view by lifecycle phase. If your questions are always about a single session, a script is genuinely competitive.
Maintenance, licence and what upgrading costs you
The repository is not archived, and the last push was on 2026-09-12, which is recent. The release cadence visible in the repository is two releases in roughly three months, v0.1.0 in March 2026 and v0.2.0 in May 2026, with repository activity continuing through September. That is a young project with an active commit history, and the pre-1.0 version number means breaking changes between releases are a real possibility rather than a theoretical one.
The practical upgrade cost is that you are running two processes against a moving API. A version bump can change what the Python `api/` returns and require a matching `frontend/` build. Because there is no published compatibility matrix in the repository, the safe assumption is that `api/` and `frontend/` should be updated together from the same revision.
Licensing is Apache-2.0, per the LICENSE file and the badge in the README. Apache-2.0 is a permissive licence that includes an explicit patent grant and requires preservation of notices. It does not impose copyleft obligations on your own code. This is a description of the licence text, not legal advice; if you plan to redistribute Karma inside a commercial product, read the LICENSE file and consult counsel.
Editorial conclusion
Adopt Claude Code Karma if you already run Claude Code CLI or Claude Desktop and want per-session cost, tool and subagent breakdowns without sending session data anywhere. Skip it if you need long-term retention or cross-machine aggregation: the README states Claude Code keeps session data for about 30 days and that deleted JSONL files disappear from the dashboard too. Before relying on it, run the install steps in SETUP.md, confirm the API and frontend both start, and check which of your sessions fall inside the retention window.
Frequently asked questions
What does Claude Code Karma give you?
It reads the session data Claude Code already writes under ~/.claude/ and renders it as a local dashboard: a session browser, per-session timelines and analytics with cost and token breakdowns, plus aggregated views for projects, tools and MCP servers, agents and hooks. The README describes it as local-first with no cloud, accounts or telemetry.
Does Claude Code Karma save your code?
The README does not describe Karma storing or uploading your code. It reads local JSONL session files and serves a dashboard on your machine, and the README states there is no cloud, no accounts and no telemetry. Note that the session files it reads include file operations such as reads, writes and edits, which the Files tab displays.
How do I download and install Claude Code Karma?
The README does not give install commands; it points to SETUP.md in the repository root for setup. The requirements listed are Python 3.10+, Node 18+ and SvelteKit 2, and the repository has separate api/ and frontend/ directories to run.
Which Claude Code sessions appear in the Claude Code Karma dashboard?
Any session that writes to ~/.claude/ shows up automatically, which the README says covers both Claude Code CLI and Claude Desktop in Claude Code mode. Sessions whose JSONL files have been deleted by Claude Code's roughly 30-day cleanup will not appear.
Does Claude Code Karma work with MCP servers and hooks?
Yes. The Tools and MCP page groups every tool by server with call counts and session coverage, including built-in tools like Read, Edit and Bash and any MCP integrations you added. Hooks are organized by lifecycle phase, and the README notes which hooks can block execution.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/jayantdevkar-claude-code-karma)Star history chart for your README
[](https://hysenlabs.com/projects/jayantdevkar-claude-code-karma)Was this useful?