joblib's vendored loky backend and its single cloudpickle dependency
Computing with Python functions.
At a glance
- What is it?
- joblib ships process management inside the wheel and depends on cloudpickle alone. That packaging choice buys a small install footprint and keeps that backend inside the package, so it cannot be upgraded on its own.
- Who is it for?
- Adopt joblib when your workload fits on a single machine and the same function runs repeatedly, and skip it when you need a distributed scheduler or an API surface the README never covers. It is a reasonable default for scientific Python on a single machine, and a poor fit for a cluster you do not own or for a project that needs an upgrade path outside the vendored loky copy.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
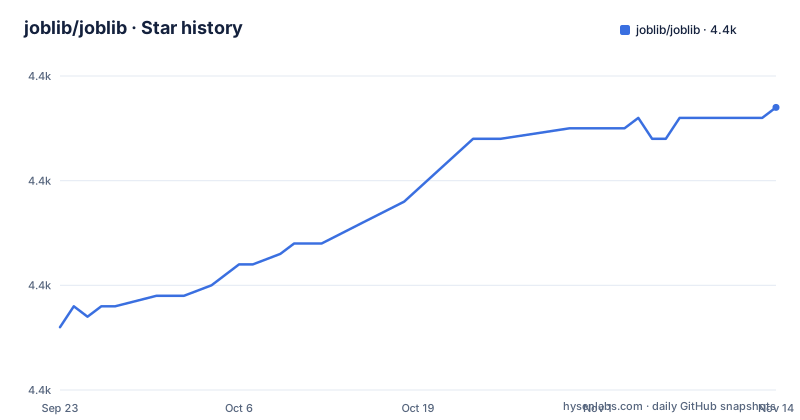
- joblib/joblib4,417 ★ · +21
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| joblib/joblib | 4.4k | 4.4k |
21 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The install footprint is one dependency, cloudpickle
The cheapest way to read joblib's dependency story is to open pyproject.toml and count the runtime list. It holds a single entry, cloudpickle at version 3 or above. Everything else is optional, which is an unusual position for a library whose whole purpose is running work across machines and processes.
The README gives a floor version for two optional packages. numpy is not required at all, yet joblib claims it can dump and load numpy arrays efficiently, and the oldest numpy it supports is 1.23.2, the oldest numpy version supported by Python 3.11. The distributed backend works the same way: joblib can hand off to Dask distributed when it is installed, and the oldest version it accepts is 2022.12.1.
Two further optional packages change behaviour rather than add features. python-lz4 replaces zlib and gzip for compressed serialization. psutil mitigates memory leaks in parallel worker processes.
Process management lives inside the package, not in a separate install
joblib includes its own vendored copy of loky for process management. That is the project's clearest structural decision. There is no loky install step, no version to reconcile, no import of an unrelated executor that could drift. The cost is visibility: the backend is inside the wheel, so you cannot upgrade it independently.
The repository layout backs this up. Top-level entries include benchmarks/, examples/, conftest.py, pyproject.toml, CHANGES.rst, CITATION.cff, SECURITY.md and TODO.rst. The test extras pull in distributed, lz4, numpy, memory_profiler, pytest, pytest-asyncio, pytest-cov, pytest-run-parallel, pytest-timeout and threadpoolctl, a list that describes the shape of the test suite better than any prose summary would.
Two different one-line descriptions, which is the small contradiction
The repository description on GitHub reads "Computing with Python functions." The project metadata in pyproject.toml says "Lightweight pipelining with Python functions." Those are not the same promise. One describes a capability, the other names a pattern and adds a weight claim.
The classifiers are narrower still. Intended Audience covers Developers, Science/Research and Education, and the Topic entries are Scientific/Engineering, Utilities and Software Development/Libraries. Nothing here claims a general purpose parallel computing system.
Installing from a wheel or from a clone, with the cost of each
The wheel install works from any directory and pulls only cloudpickle:
pip install joblibWorking from a source clone gives you the tests, the Makefile targets and the doc build. The clone itself is:
git clone https://github.com/joblib/joblib.gitThe README offers a zip of the main branch when git is unavailable, and then the editable install from the source directory:
pip install -e .The build backend is setuptools, pinned at 77.0.3 or above in build-system requires, and requires-python is >=3.11. The classifiers list 3.11 through 3.15, so a version gap between metadata and reality is not something you will hit in the supported range.
First run goes through pytest, not through an example script
Here is the part that surprises newcomers. The README never shows a joblib API call. It shows how to run the test suite, and that is the shortest honest first run the project offers. From the root of the project:
pip install joblib[test]
pytest joblib
The Makefile gives you a stricter variant with a per-test timeout and verbose output:
pytest joblib --timeout 30 -vlIt also gives you a target that turns multiprocessing off by exporting a single environment variable, which is the fastest way to separate a serialisation bug from a concurrency bug:
export JOBLIB_MULTIPROCESSING=0 && pytest joblibFor actual use, the README points to https://joblib.readthedocs.io and nothing else. The example scripts under examples/, including parallel_generator.py, parallel_memmap.py and nested_parallel_memory.py, are named but not described. A reader deciding whether to adopt the library has to leave the repository to learn what any of them do, and that gap is the honest edge of what this README can tell you.
The tarball claim and the cloudpickle requirement do not line up
The README states that `python -m build --sdist` creates a tarball that can be installed with no extra dependencies than the Python standard library. The pyproject.toml runtime dependencies list names cloudpickle>=3.0. Those two statements cannot both describe the same artifact, and the metadata is the machine-readable one, so treat the tarball sentence as stale.
The same section gives the build commands:
pip install build
python -m build --sdist
This is a small thing, but it is the same pattern the README repeats elsewhere. CHANGES.rst is described as manually updated, with a git log invocation offered to generate lines. Documentation and metadata drift apart quietly in projects where the README is maintained by hand.
Where joblib loses to pickle, and to Dask
Against pickle, the difference is not speed but reach. joblib keeps the pickle format and adds processes, memory mapping and optional compression on top, so anything pickle can store, joblib stores too. Pickle stays the answer for a single artifact on one machine with no worker pool to pay for.
Against Dask distributed, the difference is scope. Dask distributed is a cluster scheduler across hosts; joblib's Dask support is an optional backend used when that package happens to be installed. Choosing joblib means choosing the vendored loky model; choosing Dask means accepting a scheduler joblib does not ship. For a laptop or a single box, the first is enough. Across machines, the second is the real answer.
Editorial conclusion
Adopt joblib when your workload fits on a single machine and the same function runs repeatedly, and skip it when you need a distributed scheduler or an API surface the README never covers. It is a reasonable default for scientific Python on a single machine, and a poor fit for a cluster you do not own or for a project that needs an upgrade path outside the vendored loky copy. Before anything else, read the user documentation at joblib.readthedocs.org, because the README documents contributing and packaging rather than the API. Then verify two things on your own machine: that pytest joblib passes with the test extras installed, and that any artifacts you already saved still load after an upgrade. The last push was 2026-11-02, so the code is moving, and the version you pin is the version whose behaviour you keep.
Frequently asked questions
What is joblib used for?
The project metadata describes joblib as "Lightweight pipelining with Python functions", and the repository summary calls it computing with Python functions. Its dependencies point at parallel execution, serialization of large arrays, and memory mapping.
Which is better, pickle or joblib?
Pickle handles a single artifact with no worker pool. joblib builds on the same serialization idea and adds process management through its vendored loky copy, plus optional compression through lz4 and memory mapping.
Is joblib part of Python?
No. joblib is a separate package installed from PyPI, and its only runtime dependency is cloudpickle at version 3 or above. It requires Python 3.11 or newer.
How do I install joblib in Python?
From any directory, run pip install joblib. From a source clone, use pip install -e . so the test suite, Makefile targets and doc build are available locally.
How do I use joblib to save a model?
The README does not document the serialization API. It points to the user documentation at https://joblib.readthedocs.io, and the repository carries example scripts such as serialization_and_wrappers.py under examples/.
How do I use joblib in parallel?
The README does not show a parallel call. It documents the machinery around it: a vendored loky copy for process management, an optional Dask distributed backend, and JOBLIB_MULTIPROCESSING=0 as a switch to disable multiprocessing while running the tests.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/joblib-joblib)Star history chart for your README
[](https://hysenlabs.com/projects/joblib-joblib)Was this useful?