oMLX: A Menu Bar LLM Server That Puts KV Cache on SSD for Apple Silicon
LLM inference server with continuous batching & SSD caching for Apple Silicon, managed from the macOS menu bar.
At a glance
- What is it?
- oMLX is a macOS menu bar app and CLI that runs LLM inference on Apple Silicon with continuous batching and a tiered KV cache that spills to SSD. It targets developers who want local models without sacrificing control over memory and context.
- Who is it for?
- Adopt oMLX if you are a Mac developer who needs a local, OpenAI-compatible server that keeps everyday models pinned in memory and swaps heavier ones on demand, with a menu bar UI and a CLI for automation. Do not adopt it if you are on Intel Macs, macOS versions before Sequoia, or if you need multi-GPU or non-Metal acceleration.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
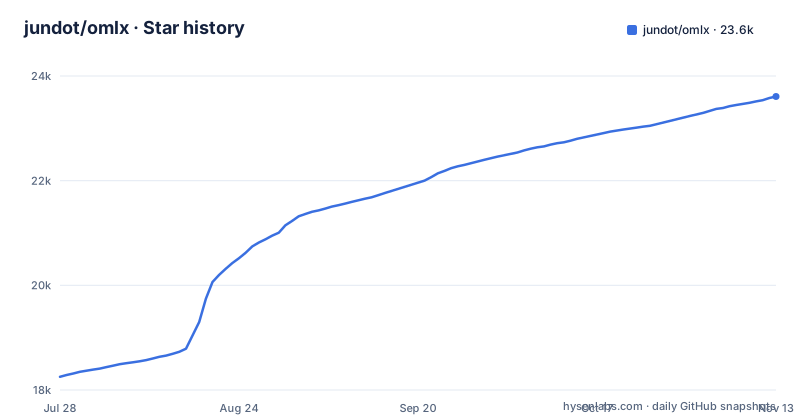
- jundot/omlx23,609 ★ · +5,356
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| jundot/omlx | 18.3k | 23.6k |
5,356 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem: Local LLM Servers Force a Tradeoff Between Convenience and Control
The README frames the core pain as a choice between convenience and control. oMLX tries to deliver both by offering a menu bar app that manages a background server, plus a CLI that can start, stop, and restart that server. The server speaks the OpenAI-compatible API on localhost:8000, so any existing client can connect. That means you can point Claude Code or similar tools at it without custom integration code. The convenience comes from the app's auto-update and one-click setup. The control comes from environment variables and a settings file that persist across restarts.
Tiered KV Caching: How the SSD Cache Works
The tiered cache is the reason oMLX claims to make local LLMs practical for real coding work. Without it, a long session with a tool like Claude Code would either exhaust memory or force a full context reload. With it, past context stays cached and reusable across requests, persisted across a hot in-memory tier and a cold SSD tier.
Getting It Running: DMG, Homebrew, or Source
Configuration is done through environment variables like `OMLX_MODEL_DIR` and `OMLX_PORT`, or by running `omlx serve --model-dir /your/path` once to persist settings to `~/.omlx/settings.json`. Logs go to two places: the service log under `$(brew --prefix)/var/log/omlx.log` and a structured server log at `~/.omlx/logs/server.log`. For MCP support, you can install the optional package: `/opt/homebrew/opt/omlx/libexec/bin/pip install mcp`. The source install requires macOS 15.0+, Python 3.11 to 3.13, and Apple Silicon. Those are hard requirements. If you are on an Intel Mac or an older macOS, this project will not run.
The Custom Kernel Trap: A 30x Performance Difference You Must Verify
The README provides a verification command: `python -c "from omlx.custom_kernels import native_kernel_status; print(native_kernel_status())"`. You should run this after any source or Homebrew install. If you skip this check, you might think your server is performing normally when it is actually running at a fraction of its potential. This is a concrete, project-specific gotcha that separates oMLX from servers that have a single uniform code path. The tradeoff is that the custom kernels are not optional for good performance on specific model families, but they add a build dependency that is easy to miss.
What It Supports: Models, Admin Dashboard, and Multi-Mac
There is also an experimental multi-Mac inference feature. Source builds can split a model across unequal-memory Macs using MLX pipeline ranks over Ring or Thunderbolt RDMA/JACCL. The README describes a Cluster dashboard with peer discovery, SSH verification, shard planning, and a live shard map. This is clearly early-stage. The README points to a separate document for setup and limitations. Treat this feature as a proof of concept, not a production capability.
Alternatives and Tradeoffs: Where oMLX Sits in the Local Inference Landscape
The README does not compare oMLX to Ollama directly. The tradeoff is that oMLX is tied to macOS and Apple Silicon, while Ollama runs on multiple platforms. If you need cross-platform support, oMLX is the wrong tool. If you are all-in on Mac, the tiered cache could be the deciding factor.
Maintenance and Upgrade Costs: Auto-Update, Homebrew, and License
The macOS app includes in-app auto-update, so future upgrades are one click. Homebrew users can run `brew update && brew upgrade omlx`. The project is under Apache-2.0, which is permissive and allows commercial use, but you should read the license text yourself for any specific obligations. The last push was on November 2, 2026, and v0.7.3 was released on October 31, 2026, so the project is actively maintained. However, the custom kernel requirement means upgrades could break if the Metal toolchain changes or if the precompiled kernels in the DMG lag behind the source. You should verify the kernel status after every upgrade. The log files are split into two locations, which is a minor operational overhead but not a burden. Overall, the upgrade path is straightforward for app users, but source builders face a recurring build dependency.
Editorial conclusion
Adopt oMLX if you are a Mac developer who needs a local, OpenAI-compatible server that keeps everyday models pinned in memory and swaps heavier ones on demand, with a menu bar UI and a CLI for automation. Do not adopt it if you are on Intel Macs, macOS versions before Sequoia, or if you need multi-GPU or non-Metal acceleration. Before relying on it, verify that you have full Xcode with the Metal toolchain if you build from source, and check `native_kernel_status()` to ensure custom kernels are active for GLM-5.2, MiniMax M3 or Qwen3.5, otherwise those families fall back to much slower generic paths (roughly 30x slower prefill for GLM-5.2). Also confirm your SSD has enough free space for the cold KV cache tier.
Frequently asked questions
How does oMLX work?
oMLX is an LLM inference server for Apple Silicon that uses continuous batching and tiered KV caching, keeping the cache across a hot in-memory tier and a cold SSD tier even when context changes mid-conversation. It is managed from the macOS menu bar and exposes an OpenAI-compatible endpoint at http://localhost:8000/v1.
How to setup oMLX?
Install the DMG and drag it into Applications, install from Homebrew with `brew tap jundot/omlx https://github.com/jundot/omlx` then `brew install jundot/omlx/omlx`, or clone the repository and run `make install` (a plain `pip install -e .` skips the native custom kernels). Requirements are macOS 15.0 or newer, Python 3.11 to 3.13, and an M1 through M5 Apple Silicon chip.
How to get oMLX API key?
The README's quickstart states that any OpenAI-compatible client can connect to http://localhost:8000/v1, and that a built-in chat UI is available at http://localhost:8000/admin/chat.
What is olmx?
oMLX is an Apache-2.0 licensed Python project described as an LLM inference server optimized for your Mac, supporting text LLMs, vision-language models, OCR models, embeddings and rerankers on Apple Silicon, with an admin dashboard at /admin.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- OMLX: Use a second Mac to speed up local LLM prefill 2.9xHacker News · Nov 7, 2026 · 1 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/jundot-omlx)Star history chart for your README
[](https://hysenlabs.com/projects/jundot-omlx)Was this useful?