vMLX: A Self-Hosted MLX Inference Server with Persistent Disk Caching for Apple Silicon
vMLX - JANGTQ Uber Compressed MLX Models - L2 Disk Cache (survives restart) + L1 Paged (super fast ttft) + Hybrid SSM Scheduler + Cont Batching + etc!
At a glance
- What is it?
- vMLX is a Python-based inference server for Apple Silicon that exposes OpenAI, Anthropic, and Ollama compatible APIs, with a focus on caching and quantization. Its standout feature is an L2 disk cache that survives restarts, but its aggressive 2-bit quantization claims and rapid release cadence demand scrutiny.
- Who is it for?
- Adopt vMLX if you run MLX models on Apple Silicon and need an OpenAI-compatible server with persistent disk caching and continuous batching, especially for multi-turn or repeated-prompt workloads. Do not adopt it if you require production-grade stability, as the project's rapid release cycle and experimental features like JIT compilation and 2-bit quantization indicate a fast-moving codebase.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 8 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
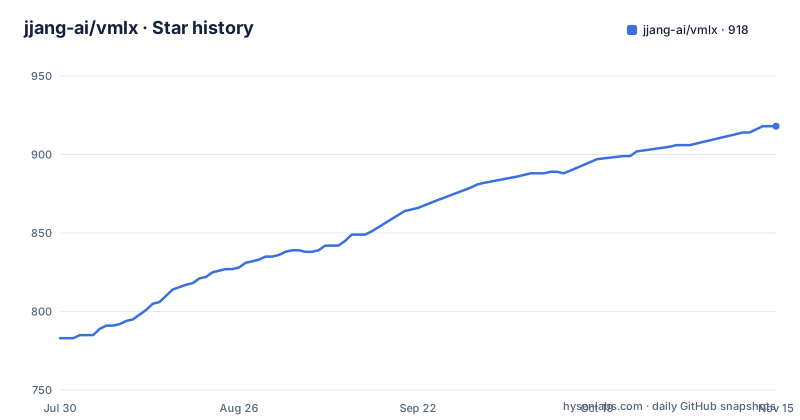
- jjang-ai/vmlx918 ★ · +135
| Repository | 2026-07-30 | 2026-11-15 |
|---|---|---|
| jjang-ai/vmlx | 783 | 918 |
135 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What vMLX Solves and Who It Is For
vMLX targets developers and researchers who want to run large language models, vision models, and image generation on Apple Silicon without sending data to third-party APIs. The README positions it as a self-hosted inference server that is compatible with OpenAI, Anthropic, and Ollama HTTP APIs, so existing clients can point at a local endpoint. The intended user is someone who already uses MLX models from the mlx-community hub and wants a server that handles concurrent requests, caches aggressively, and supports a wide range of model types. The project also offers a desktop app called MLX Studio for those who prefer a GUI. The core problem it solves is the latency and memory cost of repeated inference: by caching prompts and KV states, it aims to make follow-up messages and similar requests faster.
The Caching Architecture: L2 Disk, L1 Paged, and Prefix Reuse
The most distinctive part of vMLX is its multi-level cache design. The README describes an L2 disk cache that persists prompt caches to SSD and survives server restarts, paired with a block-based disk cache that works alongside a paged KV cache. The L1 cache is paged, meaning KV states are stored in fixed-size blocks with content-addressable deduplication. This is not just a simple memoization: the combination allows repeated tokens and prompt prefixes to be reused across requests. The claimed benefit is that follow-up messages become instant because the prefix cache reuses KV states. The disk cache extends this across process restarts, which is unusual for MLX servers. The README also mentions KV cache quantization to q4/q8, which compresses cached states for 2-4x memory savings. This architecture is aimed at workloads with high prompt reuse, such as multi-turn chat or code completion where the same context is sent repeatedly.
Getting It Running: Install and Serve Commands
The quickstart shows three installation paths: uv, pipx, or pip in a virtual environment. The recommended command is `uv tool install vmlx` followed by `vmlx serve mlx-community/Qwen3-8B-4bit`. The README warns that on macOS 14+, bare `pip install` fails with an externally-managed-environment error, so users must use uv, pipx, or a venv. Once running, the server listens on `http://0.0.0.0:8000` and exposes an OpenAI-compatible API. The README gives examples for the OpenAI Python SDK, the Anthropic SDK, and curl, all using `model="local"` and an api-key of `not-needed`. This simplicity is a strength: you do not need to configure model paths or API keys. The server also supports a desktop app via DMG download. For advanced features, there are CLI commands and configuration options mentioned.
Quantization Claims: 2-bit vs 4-bit on MiniMax M2.5
The README leads with a benchmark table claiming that JANG 2-bit quantization outperforms MLX 4-bit on MiniMax M2.5, with MMLU scores of 74% versus 26.5% on 200 questions. This is a striking claim because lower bit width usually degrades quality. The explanation is adaptive mixed-precision: critical layers are kept at higher precision. The table shows JANG_2L at 89 GB, while MLX 4-bit is 120 GB, so the 2-bit model is both smaller and more accurate in this test. However, this is a single model and a single benchmark with only 200 questions. The README points to jangq.ai for scores and to HuggingFace for models. As an engineer, you should treat these numbers as vendor-reported, not independently verified. The gap between 74% and 26.5% is so large that it raises questions about the MLX baseline's configuration. Before adopting, you would want to reproduce this on your own model and task.
Model Support and Hybrid SSM Handling
vMLX claims to run any MLX model, with a table listing many families: Qwen, Llama, Mistral, Gemma, DeepSeek, GLM, MiniMax, and others. It also supports vision models like Qwen-VL and Pixtral, plus multimodal omni models like Nemotron-3-Nano-Omni that handle text, image, audio, and video. For image generation, it uses mflux for Flux and Z-Image. A notable technical feature is hybrid SSM support, meaning models that mix Mamba or GatedDeltaNet layers with attention are handled correctly. This is not trivial because SSM layers have different state management than attention. The README specifically mentions Nemotron-H, Jamba, and GatedDeltaNet. If you work with these architectures, vMLX may be one of the few servers that support them on Apple Silicon. The breadth is impressive, but it also means the codebase must handle many model-specific quirks, which could be a source of bugs.
Limitations and Failure Modes
The most obvious limitation is platform: vMLX is for Apple Silicon only, so it is useless on NVIDIA or AMD hardware. Another limitation is the reliance on experimental features. The README marks JIT compilation with `mx.compile` as experimental, and the speculative decoding feature claims 20-90% speedup but depends on a draft model. The disk cache, while a differentiator, may not help for one-off prompts; it only pays off with repeated prefixes. The README also mentions 'native MTP artifact detection and family-specific cache policy gates' to keep speculative/cache settings model-safe, which suggests that some models may not work well with caching or speculative decoding, and the server has to disable them automatically. This is a sign that the feature set is complex and may have edge cases. Additionally, the project's release cadence is very fast: v1.6.45, v1.6.44, and v1.6.43 were pushed on consecutive days. That indicates a project in active development, which can mean frequent breaking changes or incomplete features.
Alternatives and How They Differ
The most direct alternative is llama.cpp, which also runs on Apple Silicon and offers an OpenAI-compatible server. The key difference is that llama.cpp uses its own GGUF format, while vMLX runs MLX models directly. MLX models are already quantized to MLX format, so with vMLX you avoid conversion. However, llama.cpp has a longer track record and a larger community, and it supports GPU acceleration on NVIDIA via CUDA, making it more portable. Another alternative is the official mlx-lm package, which provides a simple server but lacks the advanced caching and disk cache features of vMLX. If you only need basic inference, mlx-lm is simpler and more stable. vMLX's edge is its caching architecture and hybrid SSM support, but those come with added complexity. For image generation, mflux is a separate tool, so vMLX wraps it rather than replacing it.
Maintenance, Upgrades, and License
vMLX is licensed under Apache-2.0, which permits commercial use, modification, and distribution without copyleft obligations. The project is on PyPI as `vmlx`, so upgrades are straightforward with `uv tool upgrade vmlx` or `pipx upgrade vmlx`. However, the rapid release schedule means you will likely need to upgrade frequently to get bug fixes, and each upgrade could change behavior. The README does not mention a migration guide or changelog, so you may need to read release notes carefully. The project is not archived, and the last push was in August 2026, so it is actively maintained. The dependency on mflux and mlx-audio for image and audio features means those libraries also need to be kept in sync. Overall, maintenance cost is moderate but requires attention to release notes. The license is permissive, which is good for adoption, but you should verify that any bundled dependencies also have compatible licenses.
Editorial conclusion
Adopt vMLX if you run MLX models on Apple Silicon and need an OpenAI-compatible server with persistent disk caching and continuous batching, especially for multi-turn or repeated-prompt workloads. Do not adopt it if you require production-grade stability, as the project's rapid release cycle and experimental features like JIT compilation and 2-bit quantization indicate a fast-moving codebase. Before committing, verify the actual MMLU scores for your target model on jangq.ai, test the L2 cache behavior across restarts with your own prompts, and confirm that the hybrid SSM support covers your specific model architecture.
Frequently asked questions
How do I install vmlx on macOS?
Three routes are given: uv with brew install uv then uv tool install vmlx, pipx with brew install pipx then pipx install vmlx, or a virtual environment with python3 -m venv and pip install vmlx. A bare pip install fails on macOS 14 and newer with an externally-managed-environment error. Then run vmlx serve with a model reference such as mlx-community/Qwen3-8B-4bit.
Is the vmlx API OpenAI compatible?
It serves OpenAI, Anthropic and Ollama compatible HTTP APIs from one port. The OpenAI client example uses base_url http://localhost:8000/v1 with api_key="not-needed" and model="local", the Anthropic client is constructed the same way, and a curl example posts to /v1/chat/completions with streaming enabled.
Does vmlx need an API key, and what does it listen on?
No third-party API keys are required, and the page says the server runs at http://0.0.0.0:8000. The client examples pass a placeholder key rather than a real credential, and the visible text describes no authentication step, so the bind address and any access control are the operator's decision.
What does vmlx cache, and what survives a restart?
Four mechanisms stack up. A prefix cache reuses key-value states for repeated prompts, a paged KV cache is block-based with content-addressable deduplication, KV cache quantization compresses cached states to q4 or q8 for a stated two to four times saving, and an L2 disk cache persists prompt caches to SSD across server restarts, with a per-block persistent cache paired with the paged cache.
What is JANG 2-bit in vmlx?
An adaptive mixed-precision 2-bit quantization that keeps critical layers at higher precision. The project's own table on MiniMax M2.5 reports 74% on a 200-question MMLU subset at 89 GB, against MLX 4-bit at 26.5% and 120 GB, 3-bit at 24.5% and 93 GB, and 2-bit at 25% and 68 GB, with scores hosted at jangq.ai and models under JANGQ-AI.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/jjang-ai-vmlx)Star history chart for your README
[](https://hysenlabs.com/projects/jjang-ai-vmlx)Was this useful?