Deep Learning Drizzle: A Curated Lecture Index, Not a Course
Drench yourself in Deep Learning, Reinforcement Learning, Machine Learning, Computer Vision, and NLP by learning from these exciting lectures!!
At a glance
- What is it?
- Deep Learning Drizzle is a single HTML page that collects links to university lectures and summer school recordings across deep learning, reinforcement learning, computer vision, NLP, speech and medical imaging. The judgement is simple: it is a useful reading list and a poor substitute for a syllabus with exercises, and its licence status is unresolved.
- Who is it for?
- Adopt it as a discovery layer if you already know which subfield you want and need pointers to recorded lectures; skip it if you need graded exercises, runnable notebooks, or a curriculum with prerequisites. Before relying on it, open the repository and confirm two things: that no LICENSE file sits at the root, and how the published site is produced, since the repository has no .github/ workflows.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 85 days ago.
- What is it written in?
- Mainly HTML, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
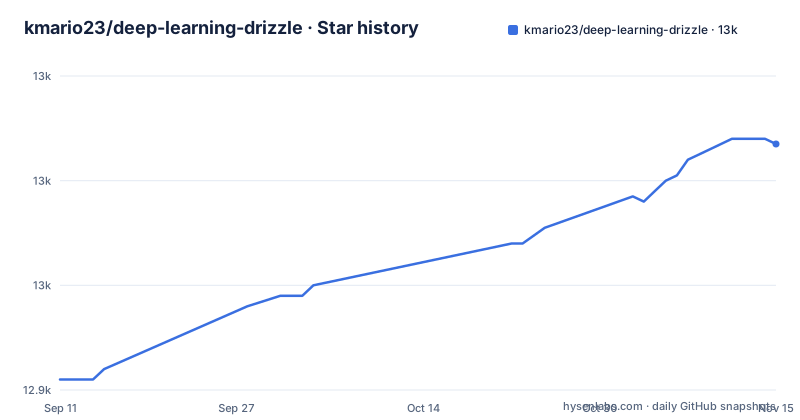
- kmario23/deep-learning-drizzle12,987 ★ · +45
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| kmario23/deep-learning-drizzle | 12.9k | 13k |
45 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem is not a shortage of deep learning material, it is a shortage of an index
Search for a lecture series on graph neural networks or Bayesian deep learning and you get a mix of course pages that have moved, YouTube playlists with no syllabus, and blog posts that paraphrase a textbook. Deep Learning Drizzle takes the opposite approach. It is a hand-maintained catalogue: one page, grouped by subject, where each entry points at an external lecture series or summer school recording. The README lists the top-level groups explicitly, including Deep Learning (Deep Neural Networks), Machine Learning Fundamentals, Optimization for Machine Learning, General Machine Learning, Reinforcement Learning, Bayesian Deep Learning, Graph Neural Networks, Probabilistic Graphical Models, Natural Language Processing, Automatic Speech Recognition, Modern Computer Vision, Boot Camps or Summer Schools, Medical Imaging, and a Bird's-eye view of Artificial Intelligence. The audience is narrow and specific. It is for the engineer who already knows what a transformer is and wants to know which recorded course explains the derivation properly. It is not for someone starting from zero, because the page does not sequence anything and does not state prerequisites between groups.
One HTML page, a GitHub Pages site, and a README that mirrors it
The mechanism is deliberately thin. The repository's primary language is reported as HTML, the default branch is master, and the homepage is a GitHub Pages URL at deep-learning-drizzle.github.io. The README contains a two-column contents table whose cells are anchor links into headings further down the same document, for example the link target #tada-deep-learning-deep-neural-networks-confetti_ball-balloon for the deep learning section. That tells you the README and the published page are two views of the same curated list, not a generated site with a database behind it. There is no crawler and no database. When a course link rots, nothing detects it. The only detection mechanism is a human reading the page and opening a pull request. That is the whole architecture, and it is worth stating plainly because it sets the ceiling on what the project can promise: the value is entirely in the curation decisions, not in any code.
Getting it running locally is a git clone and a browser
Because the output is static HTML, there is no install step. The practical route is to clone the repository and open the page directly. In a terminal, git clone https://github.com/kmario23/deep-learning-drizzle.git followed by cd deep-learning-drizzle gets you the working tree on the master branch. From there, read README.md directly; the repository's top level holds only README.md and a markdown2html_py/ folder, so there is no root HTML file to open. To contribute a lecture, the flow is the standard fork and pull request against master: fork the repository, add the entry to the relevant section in the README, commit, and open the PR. The README's contents table means any new top-level group also needs an anchor link added to that table, otherwise the navigation at the top of the page will not reach it. That is a manual consistency requirement, and it is the most likely place for a contributor's change to be incomplete.
The maintenance signal is a 2019 release tag and a 2026 push date
The release history contains exactly one entry: v19.11-lw, labelled "A first release", dated 2019-11-13. The repository's last push is 2026-08-22, and it is not archived. Those two facts sit awkwardly together. A single tagged release from 2019 with continued commits in 2026 suggests the project is maintained as a living document rather than as versioned software, which is consistent with a link list. It also means there is no changelog to read, no migration path between versions, and no way to tell from tags alone whether a section was rewritten or a single URL was corrected. If you depend on this page, depend on it as a snapshot. Pin the commit you reviewed, or vendor the list into your own notes, because the next push may reorder sections and there is no release note explaining what moved. The absence of a second release tag is not a defect in a curated index, but it does mean you cannot answer the question "what changed since I last looked" from the repository metadata alone.
The licence is unknown, and that is a real constraint
The repository metadata reports the licence as unknown. There is no licence identifier to quote, and no LICENSE file sits at the root. For a repository that is mostly a list of links, the practical exposure is smaller than for a code library, because you are not redistributing source. It is not zero. The README and the HTML are the author's compilation, and the compilation itself may attract copyright even where the linked lectures do not. The linked lectures belong to their own institutions and carry their own terms, which this project does not restate. If you plan to mirror the page, translate it, or fold its structure into internal training material, treat the licence question as unresolved until you have read the repository root yourself. This is a factual gap in the project as presented, not a legal opinion, and I am not giving legal advice. The honest position is that you cannot confirm reuse rights from the repository as published.
Where a curated link list fails, and what to use instead
The failure mode is staleness plus missing structure. Video platforms retire recordings, universities reorganise course pages, and a link that worked when the entry was added can 404 silently. Nothing in the repository layout suggests automated link checking, and the single 2019 release tag gives no indication of a periodic audit. The second failure is pedagogical: the README groups material by subfield, but a subfield is not a learning path. If you need sequencing and graded work, a structured course with assignments is the better tool, and the difference is not cosmetic. A course gives you a schedule, problem sets and a feedback loop. Deep Learning Drizzle gives you a set of doors and no floor plan. The two are complementary: use the index to find candidate courses, then commit to one course's own materials rather than sampling across the list.
Who should adopt it, and what to check before you do
Adopt it if you are a working engineer or a graduate student who already has the mathematical background and wants a shortlist of recorded lecture series per topic, particularly in the areas the README names that are harder to find good recordings for, such as Graph Neural Networks, Bayesian Deep Learning, Probabilistic Graphical Models and Medical Imaging. Do not adopt it if you need a curriculum with prerequisites, exercises or assessment, and do not treat the presence of a topic in the contents table as evidence that the linked material is current. Two things to verify first, both from the repository itself rather than from this review. Note that no LICENSE file sits at the root and the licence is reported as unknown. Then check how the GitHub Pages site at deep-learning-drizzle.github.io is produced, since this repository has no .github/ directory, only README.md and markdown2html_py/. Until both are checked, treat the page as a useful pointer collection with an open question attached to it.
Editorial conclusion
Adopt it as a discovery layer if you already know which subfield you want and need pointers to recorded lectures; skip it if you need graded exercises, runnable notebooks, or a curriculum with prerequisites. Before relying on it, open the repository and confirm two things: that no LICENSE file sits at the root, and how the published site is produced, since the repository has no .github/ workflows.
Frequently asked questions
What is Deep Learning Drizzle?
Deep Learning Drizzle is a curated index of external lecture series and courses for deep learning, reinforcement learning, machine learning, computer vision and NLP, grouped into fourteen topic buckets and published as a README plus a page at deep-learning-drizzle.github.io.
How do I use Deep Learning Drizzle?
You read it. The repository holds README.md and the markdown2html_py/ folder that generates the HTML page, and there is no package, manifest or install step to run.
Can I reuse the Deep Learning Drizzle list in my own project?
The repository lists no license file, so reuse terms are not stated anywhere in it. Linking to the list is different from copying the table, and the lectures themselves belong to the organisations that publish them.
Is Deep Learning Drizzle still being updated?
The repository is not archived and its last push to master was 2026-08-22, but the only tagged release is v19.11-lw from 2019-11-13, so there is no release cadence to follow and no version to pin.
Does Deep Learning Drizzle include the lectures themselves?
No. The top level of the repository holds only README.md and markdown2html_py/, so no videos, slides or exercises sit alongside the entries, which are links to courses hosted elsewhere.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/kmario23-deep-learning-drizzle)Star history chart for your README
[](https://hysenlabs.com/projects/kmario23-deep-learning-drizzle)Was this useful?