AI Engineering Hub and the cost of ninety three unconnected notebooks
In-depth tutorials on LLMs, RAGs and real-world AI agent applications.
At a glance
- What is it?
- The AI Engineering Hub is a public index of LLM, RAG and agent tutorials rather than a runnable project: ninety three projects, no CI, and a repository whose own homepage is a newsletter signup page.
- Who is it for?
- The hub fits a learner who wants a graded path from a first OCR app to an agent workflow and is willing to read someone else's notebook before writing their own. It is a poor fit as a dependency, as a reference implementation to copy without reading, or as a source of maintained components.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 12 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
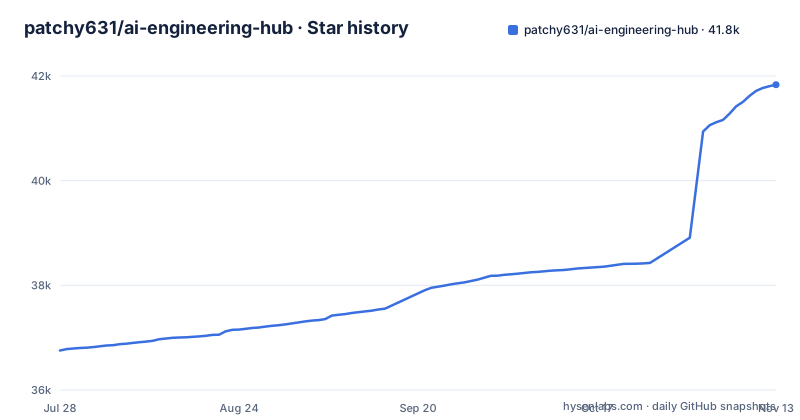
- patchy631/ai-engineering-hub41,834 ★ · +5,079
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| patchy631/ai-engineering-hub | 36.8k | 41.8k |
5,079 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The repository's front door is a newsletter signup page
The homepage field for this repository points at join.dailydoseofds.com, and the same link is the loudest call to action in the README, which offers a free Data Science eBook with 150 or more essential lessons in exchange for a newsletter subscription.
Worth sitting with that for a moment. The tutorials themselves are public and the LICENSE file is MIT, so nothing technical is behind the form. What is behind the form is the eBook; the Getting Started section sends complete beginners to a roadmap directory, ai-engineering-roadmap/, that is in the repository itself.
Ninety three directories, and no environment that holds them together
The count is stated and consistent: 93 or more production-ready projects, split as 22 beginner, 48 intermediate, and 23 advanced. The top level of the repository is those project directories plus assets/ and courses/, and one more file that matters, .gitmodules.
Now count what is missing. There is no CI directory in the tree, so no job checks any of the ninety three. There are no GitHub releases, so there is no version to install and nothing to roll back to. And a .gitmodules file means at least some content is referenced from other repositories, which a plain clone does not bring down.
The consequence is blunt: this is a shelf, not a system. Every project is an island you set up, debug, and maintain yourself, and the only thing the repository guarantees is that a directory exists.
Four naming conventions in one directory listing
Look at how the projects are named and you can see how the shelf was assembled over time:
local-chatgpt%20with%20DeepSeek
agentic_rag_deepseek
Colivara-deepseek-website-RAG
Multi-Agent-deep-researcher-mcp-windows-linux
One link in the README is URL encoded, with the space written as %20 inside a directory path. Others use underscores, others hyphens, others mixed case, and one spells out two operating systems in its own name. The projects are ordered by tier and then by category, so the listing is the index, and the listing is where the inconsistency shows.
The consequence is for anyone automating over the tree or linking to a project from their own writing: four conventions to handle, and any path written by hand from a blog post or a slide is a guess. The README is the only reliable map, and it is a markdown file that changes whenever a project is added.
One line per project, and never a line about cost
Each entry gets a sentence. Llama OCR is a 100% local OCR app with Llama 3.2 and Streamlit. The Fastest RAG Stack is fast RAG with SambaNova, LlamaIndex and Qdrant. The DeepSeek Thinking UI is a ChatGPT with visible reasoning using DeepSeek-R1. That is the level of detail, and it is genuinely useful for orientation.
It is also where the reader gets stranded, because the descriptions name vendors without saying what a project costs to run. One entry is explicitly local, another names a hosted inference provider, and the one-line descriptions do not say which keys you need or which plans you have to open before the first cell executes. The Milvus and Groq entry quotes Sub-15ms retrieval latency with no hardware, dataset, or method attached. Budget for discovering the API keys yourself, project by project.
The model list spans generations, and nothing pins a version
Across the beginner and intermediate tiers the tutorials name Llama 3.2 vision, Llama 3.3, Llama 4, DeepSeek-R1, DeepSeek Janus-Pro 7B, Gemma 3, Qwen 2.5 VL, Qwen3:4B, Qwen3-Coder, GPT-OSS, Gemini, and ModernBERT. That is a wide surface, assembled over time, and the last push to main is dated 2026-11-01 with no releases published.
Two consequences. There is no tag to move to when a provider retires a model version, so a tutorial that named a specific checkpoint is on its own. And because the primary language of the repository is Jupyter Notebook, what you inherit is a notebook someone ran once, with the cell order and the assumptions that implies, rather than a package with a version range and a test suite.
The practical advice is narrow: read the notebook before you run it, and check which model id it calls before you budget for it.
Difficulty tiers are the only navigation offered
The table of contents has five entries: Getting Started, the newsletter, Projects by Difficulty, Contributing, and License. Navigation within each tier is by category headings; the beginner tier alone splits into OCR and Vision, Chat Interfaces and UI, Basic RAG, Multimodal and Media, and Other Tools.
The Getting Started section does give a real path, in four steps: the roadmap directory for complete beginners, then beginner projects such as OCR apps and simple RAG implementations, then intermediate projects with agents and complex workflows, then advanced material covering fine-tuning and production systems. Intermediate is the largest tier by far at forty eight projects, grouped into agents and workflows, voice and audio, advanced RAG, multimodal, and a section on the Model Context Protocol.
So the intended reader is someone moving up a ladder. The cost is that anyone arriving with a specific problem, wanting RAG over Excel or a meeting notes tool, has to scan the whole ladder to find it.
The word production-ready is a description, not a check
The README calls its contents production-ready projects, and that phrase is the repository's own characterisation. Nothing in the tree verifies it: no continuous integration runs the notebooks, no release process stamps them.
What the MIT license does cover is the code as written, and the Contributing section exists for people who want to add to the hub. What it does not do is tell an adopter which projects still run, which API versions they assume, or which notebooks were last touched.
The honest way to use this repository is as an index to sample, not as a dependency to adopt. Pick the two or three projects that match your stack, read them properly, and treat the ninety one others as unverified until you have looked.
Editorial conclusion
The hub fits a learner who wants a graded path from a first OCR app to an agent workflow and is willing to read someone else's notebook before writing their own. It is a poor fit as a dependency, as a reference implementation to copy without reading, or as a source of maintained components. Before you adopt a specific project from it, check which hosted API it needs and what it costs, read the notebook end to end rather than the one line summary, and confirm the model it uses is still one you can call.
Frequently asked questions
Is AI Hub free?
The tutorials in the repository are public and the project is MIT licensed, so the code and notebooks are free to read and copy. The one gated item is a Data Science eBook with more than 150 lessons, which is offered in exchange for a newsletter subscription at join.dailydoseofds.com.
Which AI is best for engineers?
The repository does not pick a winner, it names models per project: Llama 3.2 vision, Llama 3.3, Llama 4, DeepSeek-R1, DeepSeek Janus-Pro 7B, Gemma 3, Qwen 2.5 VL, Qwen3:4B, Qwen3-Coder, GPT-OSS and Gemini each appear in specific tutorials.
Which 3 jobs will survive AI?
This is a tutorial collection, not a source on jobs or the labour market. Its projects are grouped by difficulty, 22 beginner, 48 intermediate and 23 advanced, and by topic across OCR, RAG, agents, voice, the Model Context Protocol, fine-tuning and multimodal work.
What is AI engineer's salary?
This is a tutorial collection, not a salary resource. The README states its intended audience, beginners, practitioners and researchers, and that the projects are meant to be implemented, adapted and scaled in your own work.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/patchy631-ai-engineering-hub)Star history chart for your README
[](https://hysenlabs.com/projects/patchy631-ai-engineering-hub)Was this useful?