MindsHub: A Superproject for Running Swappable AI Agents
Make AI do actual work. Swap the model anytime, keep everything you've built.
At a glance
- What is it?
- MindsHub is an open-source platform that wraps a desktop/web app, an agent backend, and a data engine into one superproject, letting you automate multi-step knowledge work with interchangeable models and agents. The Model Router and submodule-based build system are the core ideas, but the README leaves some operational details to the docs.
- Who is it for?
- Adopt MindsHub if you want a self-hosted, open-source workspace where you can route work across multiple models and agents without per-provider key wiring, and if you are comfortable with a Makefile-driven build and submodule management. Do not adopt it if you need a stable, packaged Linux installer or if you prefer a single-binary tool with minimal moving parts.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 21 days ago.
- What is it written in?
- Mainly Makefile, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
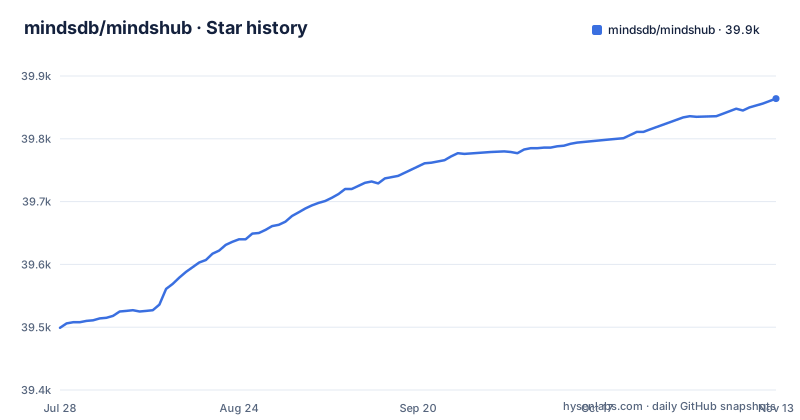
- mindsdb/mindshub39,864 ★ · +365
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| mindsdb/mindshub | 39.5k | 39.9k |
365 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What MindsHub Actually Packages
MindsHub is not a single application. It is a platform superproject that pins four modules: `frontend`, `backend/core_api`, `backend/core_agent`, and `backend/data-vault`. The README describes it as an agent workspace for completing knowledge work and developing software, where you can automate multi-step work and publish artifacts (apps, dashboards, decks, docs, analyses) to a live URL. The intended users are knowledge workers: creators, strategists, and operators who want to automate multi-step reading and writing tasks without engineering help. The key distinction from a typical AI wrapper is the explicit promise of model and agent interchangeability: you can swap the underlying model or agent harness and keep the rest of your setup intact. The repository is the assembly point, not the product itself, which matters when you evaluate it: the value lives in the modules it pins, and the superproject is just the build orchestration.
The Model Router and Agent Harness Mechanism
The core mechanism is the Model Router, which sits between your tasks and multiple providers. According to the README, you can switch between frontier models (Claude, GPT, Gemini) and open models (DeepSeek, Qwen, Kimi) without wiring up a key for each provider. That implies a single credential or gateway layer that abstracts provider-specific API calls. Alongside the router are open agent harnesses: Anton is the default, and Hermes is an alternative, both selectable from a dropdown. The README's overview does not explain how the router decides which model to use or how the harnesses differ internally, so the docs at docs.mindshub.ai are the place to look. If you need deterministic routing or per-task model pinning, check the docs or the backend modules.
Data Vault and Credential Scoping
A separate module, `backend/data-vault`, handles connected data. The README says a secure vault links systems like BigQuery, Postgres, Gmail, Drive, HubSpot, Notion, and Linear, and that credentials stay scoped per connection so agents never see raw keys. This is a meaningful architectural choice: instead of giving an agent a single API key with broad access, each connection holds its own scoped credential. That reduces the blast radius if an agent misbehaves or if a prompt injection leaks data. The presence of a dedicated data-vault module suggests that data access is a first-class concern, not an afterthought. For an enterprise deployment, check the vault's encryption method, secret rotation and revocation handling in the docs.
Build from Source: The Makefile Workflow
The project uses a Makefile as its primary interface, and the primary language listed is Makefile, which is unusual for an AI platform. The README gives a clear sequence: clone with `--recurse-submodules`, run `make setup`, then launch with `make dev` (Electron with hot reload) or `make dev-web` (browser SPA). Production builds use `make build`, and packaging for macOS or Windows uses `make dist-mac` or `make dist-win`. There is also `make flush`, which wipes the local runtime and app state under `~/.anton` (provider keys) and `~/.cowork` (database, hermes, projects). The README warns that `make flush` deletes conversations and saved keys, and it prompts for confirmation unless you pass `FORCE=1`. This is a destructive command, and the fact that it exists as a convenience suggests the install can break in ways that require a full reset. The reliance on a Makefile means you need a Unix-like environment; the README only offers prebuilt packages for macOS and Windows, not Linux, so the source path is effectively for Linux users or developers on other platforms who want to build from scratch.
Submodule Pinning and the dev.env Workflow
The superproject pins each module to a specific commit, and submodules are configured with `ignore = all` so that branch work does not dirty the parent `git status`. To work on a feature branch, you copy `dev.env.example` to `dev.env` and set `REF=feat/my-thing` or per-module `API_REF=...`. Then `make use` checks out those refs across all submodules, and `make dev` or `make dev-web` runs against that local source. Pins move only via `make pin`, which records the current submodule commits as the superproject's pins in one deliberate commit. This is a disciplined workflow: it prevents accidental pin changes and keeps the parent repository stable. However, it adds cognitive overhead. Anyone who clones the repo and runs `make setup` without reading the submodule instructions will get the pinned versions, which is fine for evaluation. But if you want to contribute or customize a backend module, you must understand the `dev.env` mechanism. The README points to `CLAUDE.md` for the full workflow, which suggests the process is more complex than the table implies. This is a trade-off: the pinning gives reproducibility, but it complicates local development and makes the repository harder to navigate for newcomers.
Deployment Targets and the Hosted Option
The README states that MindsHub is built for flexible deployment: cloud, VPC, on-prem, air-gapped, and hybrid infrastructure. That is a broad claim, and the README does not provide details on how to achieve each mode. The repository includes a docker-compose.yml with an api service (port 26866) and a web service (published on port 3000), and the Makefile has docker-build, docker-up and docker-down targets. The other paths in the Get started list are the hosted web app at `console.mindshub.ai` and the desktop apps for macOS and Windows. If you want to run MindsHub in a VPC or air-gapped environment, you can start from the Docker Compose file or contact the team for enterprise SLAs, as the README suggests. The hosted option is the easiest entry point, but it means your data and model calls go through MindsHub's infrastructure, which may not be acceptable for sensitive workloads.
Limitations and When It Is the Wrong Tool
The most obvious limitation is the lack of a packaged Linux distribution. If you are on a server without a GUI, the desktop app is irrelevant, and the source build assumes a desktop environment for `make dev`. Another limitation is the opacity of the agent harnesses. The README names Anton and Hermes as interchangeable harnesses but does not describe their capabilities in its overview. If your tasks require specific agent behaviors, you cannot evaluate whether MindsHub fits without trying it. The `make flush` command, while useful, is a blunt instrument that deletes all local state, including provider keys and the database. That is acceptable for a fresh start but dangerous in a shared environment. Finally, the project's dependence on a superproject with submodules means that any upstream module change requires a deliberate `make pin` to take effect. If you want to track upstream fixes quickly, this workflow adds friction. For a team that needs rapid iteration on the agent backend, this could be the wrong tool.
Alternatives: The Difference in Approach
A direct alternative is to use a framework like LangChain or LlamaIndex, which also provide model abstraction and agent harnesses. The difference is that those are libraries you assemble yourself, giving you full control over routing logic, memory, and tool use, but requiring you to build the application layer. MindsHub is a turnkey workspace with a UI, a data vault, and a publishing pipeline for artifacts. MindsHub's open-source nature and the ability to swap models without per-provider keys is the key differentiator, but it comes at the cost of a more complex build and a thinner documentation trail. If you need fine-grained control over the agent loop, a library approach is more transparent. If you need zero-maintenance deployment, a hosted platform is simpler. MindsHub sits in between, and its suitability depends on your tolerance for Makefiles and submodules.
Editorial conclusion
Adopt MindsHub if you want a self-hosted, open-source workspace where you can route work across multiple models and agents without per-provider key wiring, and if you are comfortable with a Makefile-driven build and submodule management. Do not adopt it if you need a stable, packaged Linux installer or if you prefer a single-binary tool with minimal moving parts. Before committing, verify the submodule pin workflow with `make refs` and `make baseline`, test `make flush` on a disposable machine to understand the data wipe scope, and confirm that the agent harnesses (Anton, Hermes) meet your task complexity needs, since their capabilities and failure modes are best checked in the docs.
Frequently asked questions
What does MindsDB do, and what is this repository?
This repository is MindsHub, described as an agent workspace for completing knowledge work and developing software, with open-source agent harnesses and a choice of models. It is the platform superproject, pulling together the desktop and web app, the agent backend, and the data engine so you can build and run the whole stack from source.
Is MindsDB free to use?
The code is MIT licensed and the README says free to start. The paid part is named as well: Pro adds all frontier models and private artifacts, and a separate inference product is sold on one set of controls and one bill across providers.
How do I create an AI agent in MindsDB?
The Get started section gives no step-by-step for creating an agent. What it describes is two interchangeable open-source harnesses, Anton as the default and Hermes, swappable from a dropdown, and a from-source path of cloning the superproject with submodules, running `make setup`, and then `make dev`.
What are some open-source alternatives to MindsDB?
The opening sections of the README name no alternatives. The one related thing it points to is MindsHub Inference, a separate hosted offering for reaching models and providers through one API, one set of controls, and one bill.
what is mindshub
MindsHub is an open-source agent workspace for research, analysis, content creation, and software development, offering a choice of models and providers rather than one ecosystem. It can run on your machine, in your VPC, or through the hosted app at console.mindshub.ai.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/mindsdb-mindshub)Star history chart for your README
[](https://hysenlabs.com/projects/mindsdb-mindshub)Was this useful?