OpenMythos: a looped-transformer guess at Claude Mythos, packaged as a PyTorch library
A theoretical reconstruction of the Claude Mythos architecture, built from first principles using the available research literature.
At a glance
- What is it?
- OpenMythos implements a Recurrent-Depth Transformer with a Prelude, a looped Recurrent Block and a Coda, plus MoE feed-forward and switchable MLA or GQA attention. It is a speculative reconstruction in Alpha, useful for experimenting with looped depth, not a copy of Anthropic's model.
- Who is it for?
- OpenMythos suits researchers who want a ready PyTorch implementation of a looped transformer with MoE and MLA or GQA attention to train and probe themselves. It does not suit anyone looking for Claude Mythos itself or for a model they can download and run: it is an unaffiliated, speculative Alpha package last pushed on 2026-05-23.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 175 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
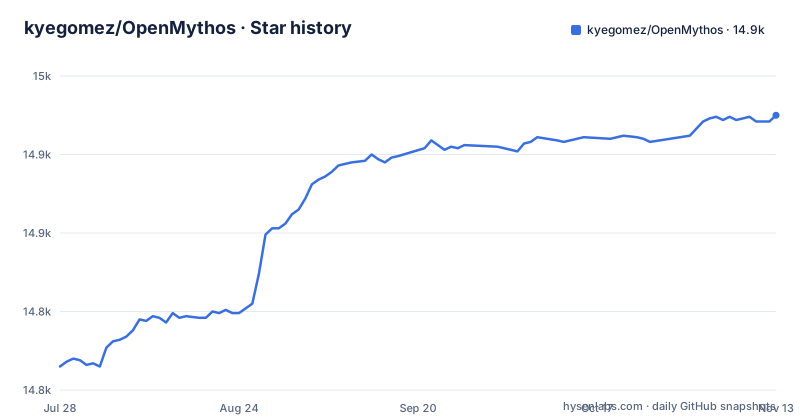
- kyegomez/OpenMythos14,925 ★ · +160
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| kyegomez/OpenMythos | 14.8k | 14.9k |
160 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Prelude, a looped Recurrent Block, and a Coda
The model in open_mythos/main.py splits its layers into three stages. The Prelude is a set of standard transformer layers that runs once. The Recurrent Block reuses the same weights and runs up to max_loop_iters times per forward pass. The Coda is another set of standard layers that runs once and produces the output. In the config these map to prelude_layers, max_loop_iters and coda_layers, so the small example config uses one Prelude layer, one Coda layer and four loops.
The point of the design is that depth comes from repetition instead of stacking more unique layers. The project frames this as reasoning that happens silently inside a single forward pass in continuous latent space, with no intermediate tokens, which separates it from chain-of-thought prompting. The preset variants scale the loop count with size: mythos_1b and mythos_3b loop 16 times, mythos_10b 24, mythos_50b and mythos_100b 32, mythos_500b 48 and mythos_1t 64.
Input injection keeps the loop tied to the prompt
Each pass through the Recurrent Block applies this update:
h_{t+1} = A·h_t + B·e + Transformer(h_t, e)Here h_t is the hidden state after loop t, e is the encoded input coming out of the Prelude, and A and B are learned injection parameters. Because e is fed back in on every iteration, the original input signal stays present across the whole recurrence depth instead of being washed out by repeated application of the same block. The project names this injection as the mechanism that prevents drift. The pyproject keywords also list LTI stability and adaptive computation time, which places the package in that line of looped-transformer research, but the update rule above is the concrete piece you can inspect in main.py.
cfg.attn_type picks MLA or GQA, and each needs different keys
Attention is chosen with attn_type in MythosConfig. Setting "gqa" selects GQAttention, Grouped Query Attention with fewer KV heads than query heads; the KV-cache memory drops by a factor of n_heads / n_kv_heads. The usage example passes n_kv_heads=2 against n_heads 8 for this mode. Setting "mla" selects MLAttention, the Multi-Latent Attention scheme from DeepSeek-V2, which caches a compressed KV latent sized by kv_lora_rank instead of full keys and values. The MLA branch of the example passes n_kv_heads=8 and kv_lora_rank=32.
The consequence is that a config is not portable between the two modes by flipping one string: the GQA and MLA branches expect different extra arguments. The feed-forward side is the same in both, a sparse mixture of experts controlled by n_experts, n_shared_experts, n_experts_per_tok and expert_dim.
Flash Attention 2 only helps the GQA path and needs a CUDA build
The base install is a single package:
pip install open-mythosFlash Attention 2 is an optional extra:
pip install open-mythos[flash]That extra pulls flash-attn>=2.8.3 and requires CUDA plus build tools, so it is not an option on a CPU-only machine or one without a working compiler toolchain. It is wired into GQAttention, where it handles grouped heads natively without expanding KV heads. When the package is absent, GQAttention falls back to manual scaled dot-product attention without failing. If you pick attn_type "mla", installing the flash extra is not what changes your attention kernel, so check which mode you are running before spending time on the build.
The variant example calls mythos_7b, which is not in the preset list
The presets are imported from the package root: mythos_1b, mythos_3b, mythos_10b, mythos_50b, mythos_100b, mythos_500b and mythos_1t. The accompanying snippet then runs `cfg = mythos_7b() # returns a MythosConfig`. There is no 7B row in the variant table and mythos_7b is not among the imported names, so copying that snippet as written will raise a NameError. Replace it with one of the seven listed functions, for example mythos_3b, which is also the size the bundled training script targets.
The table shows how fast the presets grow: dim goes from 2048 at 1B to 16384 at 1T, experts from 64 to 512, and context from 4k up to 1M for the three largest variants, which also raise max output from 4k to 128k. Instantiating the large configs and counting parameters with the sum over model.parameters() is cheap to write but not cheap to run, since the whole model is built in memory.
pyproject pins torch 2.11.0 while requirements.txt accepts 2.1.0
The two dependency files disagree. pyproject.toml, which drives the PyPI package version 0.5.0, pins torch = "2.11.0" exactly and requires Python 3.10 or newer. requirements.txt asks only for torch>=2.1.0 alongside transformers>=4.40.0, datasets>=2.18.0 and pytest. Installing with pip from PyPI therefore forces one specific torch release into your environment, which can conflict with a CUDA setup or another library that needs a different version, while installing from requirements.txt in a clone can leave you on a much older torch than the package declares.
The metadata has a second mismatch: pyproject lists the homepage and repository as The-Swarm-Corporation/OpenMythos, while the repository discussed here is kyegomez/OpenMythos. Check which one you are cloning before filing issues.
Getting usable weights means running the 3B FineWeb-Edu script yourself
OpenMythos(cfg) builds a model from a config; the route to a trained model that the project lays out is training/3b_fine_web_edu.py. On one GPU:
python training/3b_fine_web_edu.pyAcross every visible GPU on the node:
torchrun --nproc_per_node=$(python -c "import torch; print(torch.cuda.device_count())") training/3b_fine_web_edu.pyThe script uses AdamW, streams HuggingFaceFW/fineweb-edu with sample-10BT by default (sample-100BT or default for a full run), tokenizes with openai/gpt-oss-20b through MythosTokenizer, and runs DDP over a sharded streaming dataset. It uses bfloat16 on H100 or A100 and float16 with GradScaler on older cards, with 2000 linear warmup steps into cosine decay. The target is 30B tokens, described as roughly Chinchilla-adjusted for a looped architecture. That is a large compute budget, and nothing in the training section reports results from completing it.
A reconstruction of a hypothesis, with no tie to Anthropic
The starting premise is that Claude Mythos is suspected to be a Recurrent-Depth Transformer. OpenMythos builds that suspicion out from public research and speculation, and its disclaimer states it is not affiliated with, endorsed by or connected to Anthropic or any of its proprietary systems. Nothing in the repository verifies that the architecture matches the real model, so results you get from it tell you about looped transformers, not about Claude.
The maturity signals point the same way. The package classifier is Development Status 3 - Alpha, the repository has no GitHub releases, and the last push was on 2026-05-23. Treat the code as a research scaffold under an MIT license: fine to fork and modify, but expect to fix things like the mythos_7b reference yourself.
Editorial conclusion
OpenMythos suits researchers who want a ready PyTorch implementation of a looped transformer with MoE and MLA or GQA attention to train and probe themselves. It does not suit anyone looking for Claude Mythos itself or for a model they can download and run: it is an unaffiliated, speculative Alpha package last pushed on 2026-05-23. Before building on it, check which torch version you actually get, confirm the variant functions you call exist, and decide whether you can afford a training run.
Frequently asked questions
What is OpenMythos?
OpenMythos is an MIT-licensed PyTorch implementation of a Recurrent-Depth Transformer with a Prelude, a looped Recurrent Block and a Coda, built as a theoretical reconstruction of the Claude Mythos architecture from public research.
How do I install OpenMythos?
Run pip install open-mythos. For Flash Attention 2 in GQAttention, run pip install open-mythos[flash], which needs CUDA and build tools.
How do I use OpenMythos?
Import OpenMythos and MythosConfig from open_mythos.main, build a MythosConfig with fields such as dim, n_heads, max_loop_iters and attn_type, then pass it to OpenMythos. Preset configs like mythos_1b and mythos_3b return a ready MythosConfig.
Is OpenMythos legit?
It is an independent, community-driven reconstruction based on public research and speculation, and it states it is not affiliated with or endorsed by Anthropic. The package is marked Alpha and has no GitHub releases.
How does OpenMythos compare with Claude Mythos?
OpenMythos is not Claude Mythos. It implements the hypothesis that Claude Mythos is a looped Recurrent-Depth Transformer, without any connection to Anthropic's proprietary systems.
Does OpenMythos contain the code for Claude Mythos?
No. The repository contains its own reconstruction in open_mythos/main.py, based on public research and speculation, and is not connected to Anthropic's proprietary code.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/kyegomez-openmythos)Star history chart for your README
[](https://hysenlabs.com/projects/kyegomez-openmythos)Was this useful?