LightRAG: A Graph-Based RAG Framework That Trades Setup Complexity for Retrieval Depth
[EMNLP2025] "LightRAG: Simple and Fast Retrieval-Augmented Generation.
At a glance
- What is it?
- LightRAG is a Python framework that builds a knowledge graph from documents and uses it to answer queries with entity-level context. This review covers its architecture, installation, storage backends, and the trade-offs of adopting it.
- Who is it for?
- Adopt LightRAG if you need a RAG system that goes beyond flat vector search and can handle multi-hop questions with entity relationships, and if you are comfortable managing a knowledge graph index and multiple storage backends. Do not use it if you want a minimal, single-file solution or if your data is simple enough that keyword or vector search suffices.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
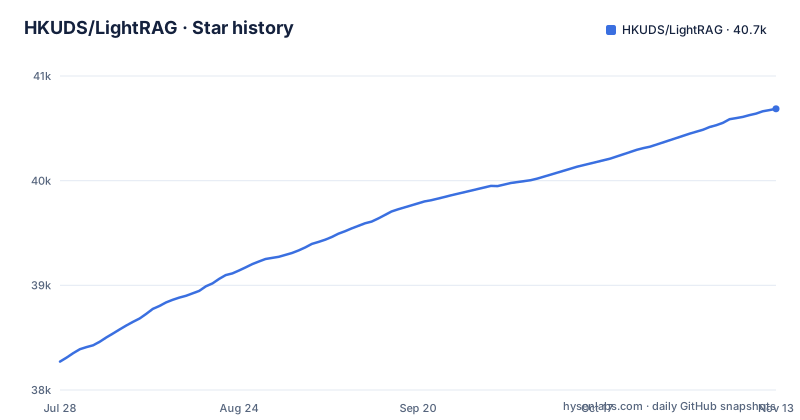
- HKUDS/LightRAG40,687 ★ · +2,416
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| HKUDS/LightRAG | 38.3k | 40.7k |
2,416 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What LightRAG Solves and Who Should Care
LightRAG addresses a specific weakness in plain RAG pipelines: they retrieve text chunks based on surface similarity, which fails when an answer requires linking facts across documents. By building a knowledge graph during indexing, LightRAG lets queries traverse entity relationships. This matters for engineers building question-answering over corporate wikis, research paper collections, or legal document sets, where the same entity appears in many contexts. The target user is a developer who wants a production-ready RAG framework with graph capabilities, not a researcher experimenting with a toy demo. The README emphasizes speed and simplicity, but as we will see, the simplicity claim only holds after you accept a fairly involved setup.
Indexing and Retrieval: The Graph Mechanism
The core mechanism is a two-stage process. First, during indexing, LightRAG parses documents, chunks them, and extracts entities and relationships to populate a knowledge graph. The README's flowchart, linked from the LearnOpenCV guide, shows an indexing pipeline that converts raw text into graph structures. Second, during retrieval, a query is processed to identify relevant entities and relationships, and then the system gathers surrounding context from the graph. This is different from dense vector retrieval because it can follow edges between entities. The recent addition of a reranker, set as the default query mode in August 2025, suggests that graph retrieval alone was not enough and that a secondary ranking step improves mixed queries. The system also supports four chunking strategies: Fix, Recursive, Vector, and Paragraph, giving you control over how the graph is built. This is a real design choice: smaller chunks may miss relationships, while larger chunks may blur entity boundaries.
Getting It Running: Commands and Configuration
Installation is via uv, a Python package manager, or pip. The recommended path is `uv tool install "lightrag-hku[api]"` which installs the server as a command-line tool. After that, you copy `env.example` to `.env` and fill in your LLM and embedding configurations. The README explicitly says to update `.env` with your LLM and embedding settings. There is also a setup wizard introduced in March 2026 that supports local deployment of embedding, reranking, and storage backends via Docker. This wizard is a recent addition, so its behavior may still be rough. For a full deployment, you need to decide on storage: the framework supports Neo4J, MongoDB, PostgreSQL, OpenSearch, and others. OpenSearch was added in March 2026 as a unified storage backend for all four LightRAG storage types, which suggests that the storage layer is modular but also that you must pick one. The README also mentions an offline deployment guide for air-gapped environments, which is a practical concern for many enterprises.
Storage Backends: Flexibility Comes with Complexity
LightRAG does not dictate a single storage solution. You can use Neo4J for graph storage, MongoDB or PostgreSQL as an all-in-one solution, or OpenSearch as a unified backend. This is both a strength and a burden. The strength is that you can align storage with your existing infrastructure. The burden is that you must understand the trade-offs. Neo4J gives you a dedicated graph database, which may be overkill if your graph is small. MongoDB or PostgreSQL simplify operations by storing everything in one place, but they may not scale to very large graphs as efficiently. OpenSearch, being a search engine, could be a good fit for text retrieval but might not handle graph traversals as naturally.
Multimodal and Role-Specific Configurations: Recent Expansions
Since its initial release, LightRAG has grown beyond text. The May 2026 merge of RagAnything brings multimodal content parsing and extraction via MinerU or Docling services, supporting PDFs, images, Office documents, tables, and formulas. This is a significant expansion, but it also means the core graph-based retrieval now has to handle non-text modalities. A May 2026 update also introduced role-specific LLM configurations: you can set separate LLMs for EXTRACT, QUERY, KEYWORDS, and VLM roles. This is useful if you want a cheap model for keyword extraction and a powerful one for query answering. However, it adds four more configuration points. The README also mentions Smart Heading recognition for Word documents, which is a niche feature. These additions show a project that is actively evolving, but they also increase the surface area for bugs and configuration errors.
Limitations and Failure Modes
The most obvious limitation is the complexity of the setup. Installing via uv is straightforward, but configuring storage backends, LLM roles, chunking strategies, and rerankers is not trivial. The README's own news section lists multiple new features in quick succession, which suggests that the API may shift between releases. The v1.5.7 release went through two release candidates in August 2026 before the stable tag on 2026-09-02, which suggests the project is still changing quickly. Another failure mode is the knowledge graph extraction quality: if the underlying LLM fails to extract entities correctly, the entire retrieval is compromised. The README notes that graph extraction accuracy was enhanced for open-source LLMs like Qwen3-30B-A3B, which implies that accuracy varies by model. Also, document deletion triggers automatic KG regeneration, which could be expensive for large corpora. If you have a rapidly changing document set, the regeneration cost may outweigh the benefits of graph retrieval.
Alternatives and How They Differ
The obvious alternative is a standard vector-based RAG framework like LlamaIndex or LangChain, which retrieves text chunks using embeddings. The difference is fundamental: vector RAG does not build a knowledge graph, so it cannot answer questions that require multi-hop reasoning across entities. LightRAG's graph structure gives it an advantage for complex queries, but at the cost of indexing time and storage overhead. Another alternative is a pure graph database approach, such as using Neo4J directly with your own extraction pipeline. That would give you full control over the graph schema, but you would have to build the retrieval logic yourself. LightRAG provides a ready-made pipeline, which is its value. The choice depends on whether your queries are simple fact lookups or require relationship traversal.
Maintenance and Upgrade Considerations
The project is under active development, with v1.5.7 released on 2026-09-02 after two release candidates in August 2026. This means you should expect frequent updates and potential breaking changes. Upgrading may require manual adjustments to configuration files. The license is MIT, which is permissive and allows commercial use without restrictions, but you should still review the license terms yourself. The maintenance cost is non-trivial: you need to keep up with new features like the setup wizard, OpenSearch integration, and role-specific LLMs, and you need to test them against your data. The project also has a Discord channel for community support, but that is not a substitute for documentation. Before adopting, check the GitHub issues for known problems, especially around storage backends and the new multimodal features.
Editorial conclusion
Adopt LightRAG if you need a RAG system that goes beyond flat vector search and can handle multi-hop questions with entity relationships, and if you are comfortable managing a knowledge graph index and multiple storage backends. Do not use it if you want a minimal, single-file solution or if your data is simple enough that keyword or vector search suffices. Before committing, verify the current state of the v1.5.7 release, test the new chunking strategies and role-specific LLM settings on your own documents, and confirm that the setup wizard and Docker-based backends work in your deployment environment. The project is actively maintained with regular releases, but the breadth of features means you must budget time for configuration and tuning.
Frequently asked questions
what is lightrag
LightRAG is a Python retrieval-augmented generation library that extracts entities and relationships into a knowledge graph while documents are inserted, and combines that with vector and keyword search at query time. It is on PyPI as lightrag-hku under the MIT license, and its own classifiers say Development Status :: 4 - Beta.
how to install lightrag
The README recommends uv, installed with `curl -LsSf https://astral.sh/uv/install.sh | sh`, and says pip also works. The distribution name is `lightrag-hku` rather than `lightrag`, and the package requires Python 3.10 or newer. There is also a container path using the compose file in the repository root.
What are the key differences between LightRAG and GraphRAG?
What LightRAG's configuration shows is that graph construction happens at insert time through dedicated EXTRACT and KEYWORDS model roles, while retrieval is a separate query-time path with its own model and a reranker enabled by default. Evaluate both on your own corpus.
is lightrag open source
Yes. The repository carries an MIT LICENSE at the root, the package metadata declares `license = {text = "MIT"}` with the MIT OSI classifier, and the README links an arXiv paper describing work presented at EMNLP2025.
lightrag is slow
It records a scalability change in 2025.10 and made a reranker the default query mode in 2025.08, which adds a model call to every query. Those are the first two things to look at, alongside whether the four model roles, EXTRACT, QUERY, KEYWORDS, and VLM, are pointed at models sized for their jobs.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Does Graph RAG Actually Help? I Measured It on Postgres and TypeScriptdev.to · Nov 5, 2026 · 2 points · 4 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/hkuds-lightrag)Star history chart for your README
[](https://hysenlabs.com/projects/hkuds-lightrag)Was this useful?