Jasminum for Zotero: ordered metadata sources, image-based AI recognition, and outlines that do not reach the PDF until you save them
A Zotero add-on to retrieve CNKI metadata.
At a glance
- What is it?
- Jasminum is a Zotero plugin for Chinese-language literature that fetches metadata from PubScholar, NCPSSD, CNKI, Yiigle and an optional vision model, matches downloaded attachments, and manages PDF bookmarks and outlines. Most of its behavior depends on source order, file names, and which Zotero version you run.
- Who is it for?
- Jasminum fits Zotero users who manage Chinese PDFs and want CNKI, PubScholar, NCPSSD or Yiigle metadata without retyping it. It does not fit anyone still on a Zotero release older than 9.0.3, or anyone who cannot send PDF page images to a third-party model provider and still expects the AI features to work.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
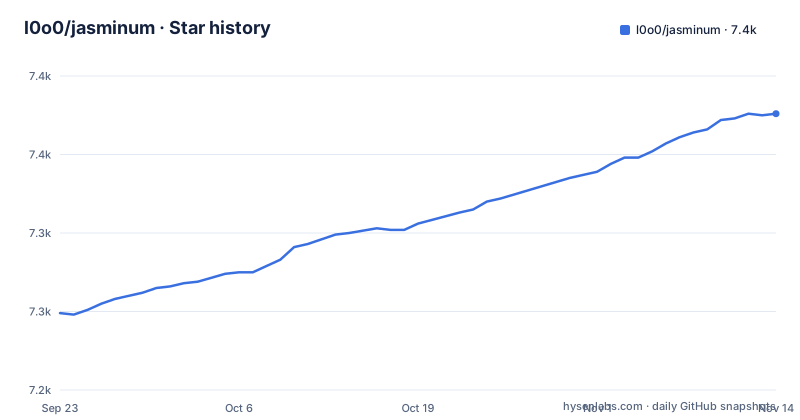
- l0o0/jasminum7,376 ★ · +127
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| l0o0/jasminum | 7.2k | 7.4k |
127 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Metadata sources run in your configured order, and AI only runs when the earlier ones come back empty
Jasminum's metadata fetch starts from a PDF attachment that is not yet attached to a parent item. You right-click it, open the Jasminum metadata menu, and choose to fetch metadata. A task window reports the outcome, and when more than one candidate record matches, you pick the right one and confirm.
Where the record comes from is set under Data Sources in the Jasminum settings. Five sources are available: PubScholar, the National Center for Philosophy and Social Sciences Documentation (NCPSSD), CNKI, Yiigle (the Chinese Medical Association journal full-text database), and AI recognition. You can enable, remove, and reorder them.
The order matters because sources run one after another. AI recognition only executes when the sources ahead of it have not produced a reliable result. If you would rather have the model answer first, you have to move AI to the top of the list yourself. The consequence of leaving the default arrangement is that AI is a fallback, and you pay nothing to a model provider for papers the traditional sources already resolve.
Traditional sources search by your file name, so a mangled name means no match
PubScholar, NCPSSD, CNKI and Yiigle lookups are driven by the attachment's file name. Jasminum parses the name to build its query, which is why the project asks you to keep the accurate paper title in the file name and to adjust the file name parsing settings when your naming scheme differs.
This is the plugin's most common point of failure. If a PDF arrives as a download ID, a hash, or a truncated title, the traditional sources have little to search with, and the fetch can return nothing. The troubleshooting notes for a missing result point at three things: the attachment title, the file name parsing rules, and the Data Sources configuration. They also name a cause outside your control: access restrictions on the source websites can block retrieval.
For a reader with a backlog of badly named files, the practical choice is between renaming files before fetching and moving AI recognition earlier in the order, which reads page images instead of the file name.
The AI connection test checks image reading and JSON output, not just whether your key works
AI recognition talks to an OpenAI-compatible endpoint. In the AI recognition interface settings you either pick a preset or define a custom endpoint, then enter a Base URL, an API Key, and a model ID. The Base URL must be the API root, not the full /chat/completions address; pasting the full path is an easy way to break the setup.
The Test Connection button sends a built-in jasmine test image and checks whether the model correctly reads the text in the image, identifies the petal color, and returns JSON. The test times out after two minutes.
The presets are MagicZotero, SiliconFlow (硅基流动) and DeepSeek. Choosing a preset does not mean the model you select can accept images. The model needs both image input and JSON Object output, and the connection test result is the thing to trust. For MagicZotero, the setup path runs through the Garden plugin: register an account, follow the Open Model Store link in the interface settings, and copy the API Key from the chosen model's View Details, then Show Configuration page. Passing the test is not enough for metadata fetching on its own; AI also has to be enabled under Data Sources.
Every AI feature ships PDF page images to the provider you configured
Jasminum states plainly what leaves your machine. The connection test sends the built-in test image. Metadata recognition sends images of the first few pages of the PDF. Full-text outline recognition sends page images in batches across the document. All of it goes to whichever provider you configured, and that provider may bill you for the calls.
This has two consequences. First, if your library contains unpublished manuscripts, review copies, or anything under a confidentiality agreement, the AI features send those pages off your machine, and the only control is not enabling them. Second, outline recognition on a long book is a batch job against a paid API, so cost scales with page count.
There is also a hard version gate. AI metadata recognition and AI outline recognition require Zotero 10 or later. On Zotero 9.x the rest of the plugin works, but these two features do not. The project also asks users to check AI results by hand and never to paste an API Key into a public issue.
Local attachment matching moves your downloaded files into jasminum-backup by default
When the browser connector saves a record but fails to download the attachment, you can download the PDF or CAJ file yourself, right-click the item, and choose Find attachment in download folder under the tools menu. Jasminum compares the item title against file names in the download directory and picks the closest match, so the same file naming discipline that helps metadata lookup also helps here.
The download directory defaults to the system Downloads folder and can be changed in settings. The part to watch is what happens to the original file after a successful match: by default it is moved to a jasminum-backup folder inside the download directory. Settings let you delete the original instead, or leave it untouched. The copy imported into Zotero is not affected by any of these choices.
If you never clean out jasminum-backup, it accumulates a second copy of every paper you match. If you choose delete, the only remaining copy is the one inside Zotero.
Hand-edited outlines stay in plugin data until you save them to the PDF
In the Zotero PDF reader's left sidebar, Jasminum adds a bookmarks panel and an outline panel. Bookmarks record reading positions and support add, delete, and drag reordering. The outline panel holds hierarchical headings with add, edit, delete, level changes, and drag reordering. You can add either from selected text through a selection popup or the right-click menu; the popup button can be turned off in settings while the context menu entry stays.
With a node selected, the outline sidebar takes keyboard input: Up and Down move between visible nodes, Left and Right expand or collapse, Space edits the title, [ and ] promote or demote a level, \ creates a child node, and Delete or Backspace removes the node.
The catch is storage. Manually edited outlines are kept in the plugin's local data, not in the PDF. To write them into the file you choose Save outline to PDF from the More menu at the right of the outline toolbar. Until you do, another PDF reader opening the same file will not show your outline. If the save fails, the troubleshooting list points to a read-only file or another application holding it open.
Closing the task window during AI outline recognition throws away the run
AI full-text outline recognition starts from the tools submenu on an attachment's context menu or from the More menu in the outline sidebar. Progress appears in the Jasminum task window, where you can stop recognition and resume it later.
When it finishes, a separate review window opens. You check each heading's title, level and PDF page number. Up and Down switch headings, drag reorders, Delete or Backspace removes, and Left and Right adjust the level. Page numbers are editable, and a jump button on the right shows the corresponding spot in the PDF. Icons and hover hints separate headings matched against the original text from headings whose position was estimated, so the estimated ones are where your checking effort should go. Clicking Save writes the result to both the Jasminum outline and the PDF, and the review window closes on success.
Closing the task window clears the task list and stops outline recognition. If you close it before reviewing and saving, the recognition work, and the API calls you paid for, are lost.
Installing the wrong file, or the wrong Zotero, is the first failure most users hit
The current release is v1.1.43, published on 2026-10-22, following v1.1.42 and v1.1.41 earlier that week. The last push to the repository was on 2026-10-27. This release requires at least Zotero 9.0.3; users on older Zotero versions are pointed to the release notes of earlier plugin versions.
Installation is manual. Download the .xpi package from the GitHub Releases page, not the Source code archive, which Zotero cannot install. In Zotero open Tools, then Plugins, use the gear menu, choose Install Plugin From File, and select the .xpi. Menu names vary slightly by Zotero version and language. The Jasminum page then appears in Zotero settings, where you can also download or update the Chinese translators from l0o0/translators_CN for web capture, download the community-maintained Chinese citation styles from zotero-chinese/styles, and use tools for language settings and splitting or merging Chinese names.
Building from source uses the Zotero Plugin Template toolchain. A .env file copied from .env.example tells the scaffold where Zotero and a development profile live:
ZOTERO_PLUGIN_ZOTERO_BIN_PATH = /path/to/zotero.exe
ZOTERO_PLUGIN_PROFILE_PATH = /path/to/profile
The code is licensed AGPL-3.0-or-later.
Editorial conclusion
Jasminum fits Zotero users who manage Chinese PDFs and want CNKI, PubScholar, NCPSSD or Yiigle metadata without retyping it. It does not fit anyone still on a Zotero release older than 9.0.3, or anyone who cannot send PDF page images to a third-party model provider and still expects the AI features to work. Before relying on it, confirm your Zotero version, check that your attachment file names carry accurate titles, and run the AI connection test against the exact model you plan to use.
Frequently asked questions
What is Jasminum in Zotero?
Jasminum (茉莉花) is a Zotero plugin for managing Chinese-language literature. It fetches metadata from sources such as CNKI and PubScholar, matches downloaded attachments, and manages PDF bookmarks and outlines.
Which Zotero version does Jasminum v1.1.43 need?
Jasminum v1.1.43 requires Zotero 9.0.3 or later. AI metadata recognition and AI outline recognition additionally require Zotero 10 or later.
Why does Jasminum not find metadata for my PDF?
Traditional sources search using the attachment file name, so check that the file name holds the accurate title and review the file name parsing rules and Data Sources settings. Access restrictions on the source websites can also block retrieval.
What data does Jasminum send to an AI provider?
The connection test sends a built-in test image, metadata recognition sends images of the first few PDF pages, and outline recognition sends page images in batches. The provider you configure may charge for these calls.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/l0o0-jasminum)Star history chart for your README
[](https://hysenlabs.com/projects/l0o0-jasminum)Was this useful?