OpenAssistant: A Finished Crowdsourcing Platform for RLHF Data, Not a Running Chatbot
OpenAssistant is a chat-based assistant that understands tasks, can interact with third-party systems, and retrieve information dynamically to do so.
At a glance
- What is it?
- OpenAssistant is a completed LAION project that built a crowdsourced pipeline for collecting and ranking instruction data. It is not a deployable assistant; its value now lies in the oasst2 dataset and the reference architecture.
- Who is it for?
- Adopt OpenAssistant if you need a reference implementation for a crowdsourced data collection and ranking pipeline, or if you want to use the oasst2 dataset for supervised fine-tuning or reward model training. Do not adopt it if you expect a maintained, runnable assistant: the project is explicitly completed, the last release is an alpha from November 2023, and the README warns that local setup is for development only.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Probably not. The repository last received commits 27 months ago, on August 17, 2024.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
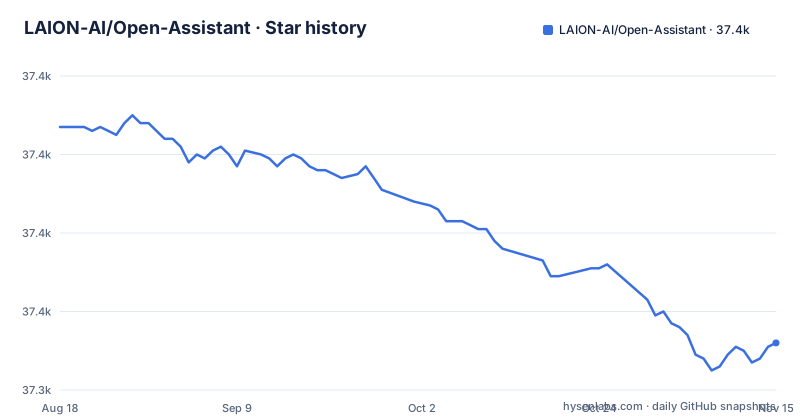
Star history
- LAION-AI/Open-Assistant37,352 ★ · -55
| Repository | 2026-08-18 | 2026-11-15 |
|---|---|---|
| LAION-AI/Open-Assistant | 37.4k | 37.4k |
-55 Stars in the last 89 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What OpenAssistant Actually Was
OpenAssistant was a LAION project with a simple goal: give everyone access to a chat-based large language model. The README describes it as a project to collect high-quality human generated instruction-fulfillment samples. The plan followed the InstructGPT paper: collect prompts and responses, have users rank multiple completions, then train a reward model and run RLHF. The README states at the top that OpenAssistant is completed and the project is finished. The final published oasst2 dataset is on HuggingFace at OpenAssistant/oasst2. That dataset is the lasting output. The codebase remains on GitHub under Apache-2.0, but it is no longer under active development. The last push was 2024-08-17, and the most recent release is v0.0.4-alpha2. Anyone evaluating this today should treat it as a historical artifact with a useful data product, not as a live project.
The Crowdsourcing Pipeline and the Three-Step Plan
The architecture is visible from the README and the repository layout. The project ran a public website at open-assistant.io with two frontends: a data collection app and a chat interface. The data collection app let users submit prompts, write responses, and rank completions. The ranking step was designed to handle unreliable users: the plan called for multiple votes by independent users and a leaderboard to motivate contributors. The pipeline had three phases. First, collect over 50,000 prompt-response pairs. Second, sample multiple completions per prompt and have users rank them from best to worst. Third, use that ranking data to train a reward model, then run RLHF. The README explicitly says the goal was to replicate ChatGPT and go beyond it, with APIs and dynamic research. But the core mechanism was always the human feedback loop. The repository contains the backend, the frontend, and the inference system in a folder called inference. The Docker setup ties these together for a local development stack.
Running It Locally: Docker Profiles and a Mail Trap
The README gives a concrete path to run the development stack. You do not need to run the project locally unless you are contributing, but the commands are there. From the root directory, run docker compose --profile ci up --build --attach-dependencies. On an M1 Mac, you must prefix it with DB_PLATFORM=linux/x86_64. The stack includes the website, backend, and dependent services. After boot, navigate to http://localhost:3000. There is a catch: email login goes through a local mail trap at http://localhost:1080, where you pick up the magic login link. For the chat inference system, you add --profile inference to the command. The README warns that the local setup is only for development and is not meant to be used as a local chatbot. This is a significant constraint. The project is not a turnkey assistant; it is a development environment for contributors. The devcontainer folder exists for VS Code or GitHub Codespaces, which suggests the intended workflow was contribution, not deployment.
The Inference System: Present but Not Self-Service
The repository includes an inference folder, and the README points to it for getting the inference system up and running. The README's local-setup section points to that folder and to --profile inference. The project's vision was to build an assistant that could use APIs and research information dynamically. The alpha release tags (v0.0.4-alpha2) suggest the inference stack never reached a stable version. For an engineer, this means the inference part is the least documented and least proven component. If your goal is to run an open assistant, this repository will not get you there quickly.
The Real Limitation: The Project Is Done and the Code Is Cold
The most honest limitation is the project's status. The README says it is finished. There is no maintenance. The last release is an alpha from November 2023. That means security fixes, dependency updates, and compatibility patches are not coming. The Docker setup may break on newer versions of Docker or macOS. The README itself references an FAQ for Docker issues, which indicates the build was already fragile. Another limitation is the scope: the data collection app was designed for a web-based crowd, not for private use. The ranking system assumes many users and a leaderboard. If you want to collect your own RLHF data with a small team, this architecture is overkill. The README's vision says the assistant should be small and efficient enough to run on consumer hardware.
Alternatives: The Dataset Is the Product, Not the Code
The most direct alternative to OpenAssistant is not another assistant project; it is the oasst2 dataset itself. The README directs users to HuggingFace for the final dataset. If you need RLHF training data, you can download that dataset and skip the entire platform. That is a fundamentally different approach: instead of running a crowdsourcing pipeline, you consume the finished output. For building a reward model or fine-tuning a model, the dataset is the practical choice. Another alternative is to build your own pipeline using tools like Argilla or Label Studio, which are general-purpose data labeling platforms. Those tools are not specific to RLHF, but they are actively maintained. The difference is that OpenAssistant's code is specifically designed for prompt-response ranking, while generic labeling tools require you to configure that workflow yourself. If you want a maintained, general solution, Argilla or Label Studio is the safer bet. If you want a proven dataset, use oasst2 directly.
Maintenance and License Implications
The project is licensed under Apache-2.0. That is a permissive license, so you can reuse the code with attribution and without copyleft obligations. But the maintenance cost is effectively zero because there is no maintenance. The repository is archived in spirit, though not marked as archived on GitHub. The release cycle stopped at alpha versions. For a production system, this is a red flag. You would be adopting a codebase that will not receive updates. The dataset, however, is a static artifact. Once you download it, there is no maintenance cost. The license allows commercial use and modification, but you should verify the exact terms of the dataset on HuggingFace, as dataset licenses can differ from the code license. The README note says only that the dataset is published on HuggingFace. That is a specific thing to check before using it.
Who Should Use It and What to Verify First
The target audience is researchers and engineers who want to understand how a large-scale RLHF data collection effort was organized. The codebase is a reference architecture for crowdsourced prompt and ranking collection. It is also useful for anyone who wants to reproduce the pipeline for a similar community effort. The oasst2 dataset is immediately useful for training or evaluation. The wrong audience is anyone who wants a chatbot to deploy. The README is explicit that the local setup is not for that. The inference system is unmaintained and the README only points to its folder. Before you commit, verify that the Docker build still works on your machine. Check the FAQ for known issues. Look at the GitHub issues for unresolved problems. Confirm the dataset license on HuggingFace. If those checks pass, you can use the dataset with confidence. The code, however, is best treated as a historical reference, not a foundation for new work.
Editorial conclusion
Adopt OpenAssistant if you need a reference implementation for a crowdsourced data collection and ranking pipeline, or if you want to use the oasst2 dataset for supervised fine-tuning or reward model training. Do not adopt it if you expect a maintained, runnable assistant: the project is explicitly completed, the last release is an alpha from November 2023, and the README warns that local setup is for development only. Before building on it, verify that the Docker images still build on your host, check the GitHub issues for known workarounds, and confirm that the Apache-2.0 license covers the parts you plan to reuse. The real deliverable is the dataset, not the code.
Frequently asked questions
what is open assistant
It was LAION's project to give everyone access to a chat based large language model, built on a crowdsourced pipeline of collecting, ranking, and labelling prompts and responses. Its README states that the project is completed and finished, and that the lasting output is the oasst2 dataset published on HuggingFace.
how to open assistant
The README points to two hosted pages rather than to a local run: the chat frontend at open-assistant.io/chat, where you log in and can rate responses with a thumbs up or down, and the data collection app at open-assistant.io, where contributors submit, rank, and label prompts and responses. Project documentation is at projects.laion.ai.
Can I run OpenAssistant locally as a chatbot?
The README warns against it. The local setup is described as only for development and not meant to be used as a local chatbot unless you know what you are doing. If you do, the instructions point at the inference folder, or at adding a second --profile inference argument alongside --profile ci.
What did OpenAssistant leave behind?
The final published oasst2 dataset, available on HuggingFace as OpenAssistant/oasst2, plus a blog post explaining that the project is completed. The code is still in the repository, with a last push dated 2024-08-17 and releases v0.0.4-alpha0 through alpha2 all tagged on 2023-11-25.
Why does the OpenAssistant compose stack need a profile flag?
Every service in docker-compose.yaml is gated behind a profile: frontend-dev, backend-dev, ci, and inference-dev, with redis-insights under backend-dev alone. Without a profile almost nothing starts. The file's comments describe ci as the profile used by CI automations for end to end testing, and backend-dev and frontend-dev as the modes for working on each half of the stack.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/laion-ai-open-assistant)Star history chart for your README
[](https://hysenlabs.com/projects/laion-ai-open-assistant)Was this useful?